The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

The cheapest model on the price list isn't the cheapest to run
We ran the same 25 synthetic invoices through every candidate model:
The cheapest listed model answered "rate-limited upstream" on 15 of 25, even when run alone. A model that doesn't answer costs a person's time.
The model that read invoices best wrote passport names as one line instead of surname and given names. The grounding check flagged them, and genuine applicants would have waited for a review. So it stays second.
On one provider, turning reasoning to "minimal" took about 10 s; turning thinking off took about 2 s. We now pin the measured hosts first.
Model choice is an eval, not a price-list decision.
The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started



Related posts

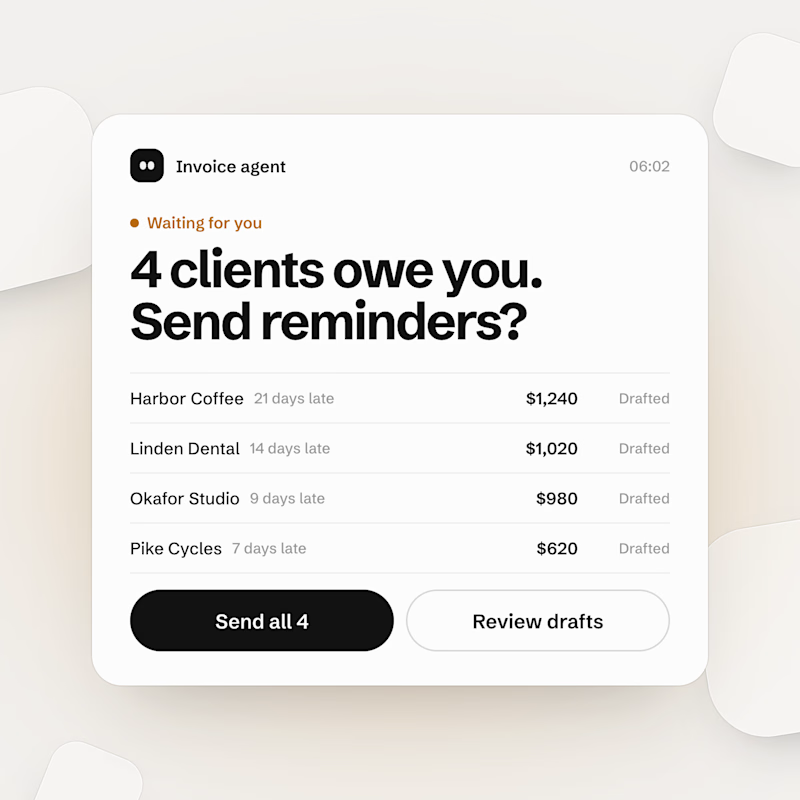
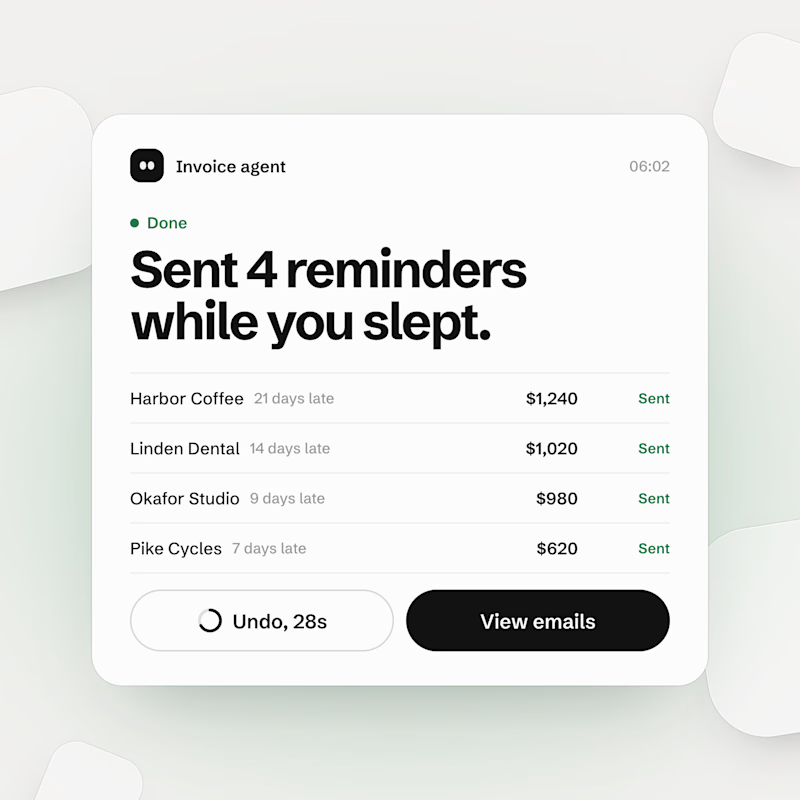
An AI agent that asks before everything is a to-do list with extra steps. One that never asks is an apology email waiting to happen.
Built both for a concept invoice agent. Same 4 late clients, same $3,860. Which one gets to email your clients, A or B?
3 votes
Ends in 8h

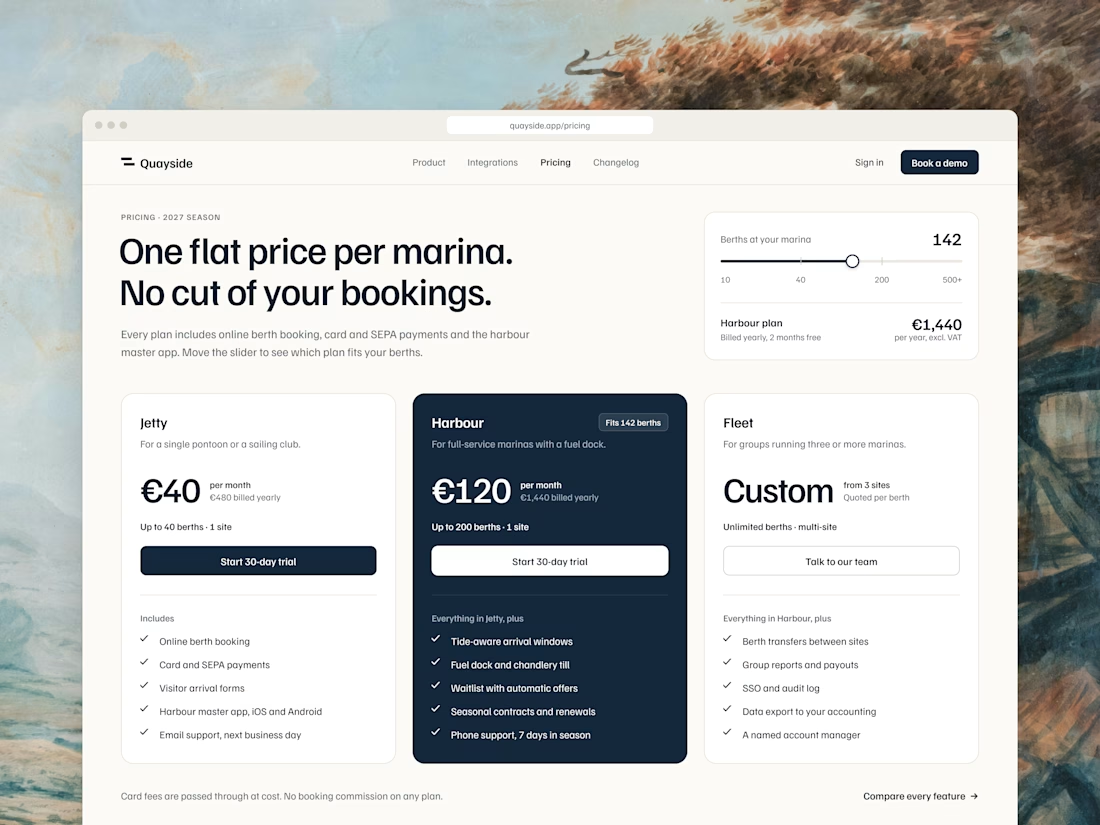
Pricing page: let visitors size their own plan.
One slider picks the right plan and shows the yearly total, so nobody has to do the math before a call.



The most expensive customer service tool is a personal phone.
When one person answers clients from their own WhatsApp, the business doesn’t own those conversations. If they’re sick, on vacation, or leave the company, the history goes with them
Fix it early: one shared inbox, a clear owner for every chat, and notes your team can read. Clients never see the handoff, they just get answered faster.