The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

A developer asked me about latency in my reasoning gate. Here is the full architecture, and the tradeoff I made.
This is a case study of OIL-NEWS-SYSTEM—an autonomous oil trading pipeline I built from scratch.
The Problem
Most trading bots trade on headlines that were never about oil, or they fire on stale news because they acted on the first tweet they saw instead of the newest one. The developer assumes the strategy is bad. They tweak the RSI. It bleeds again. The flaw is not the strategy. It is the signal.
The Decision
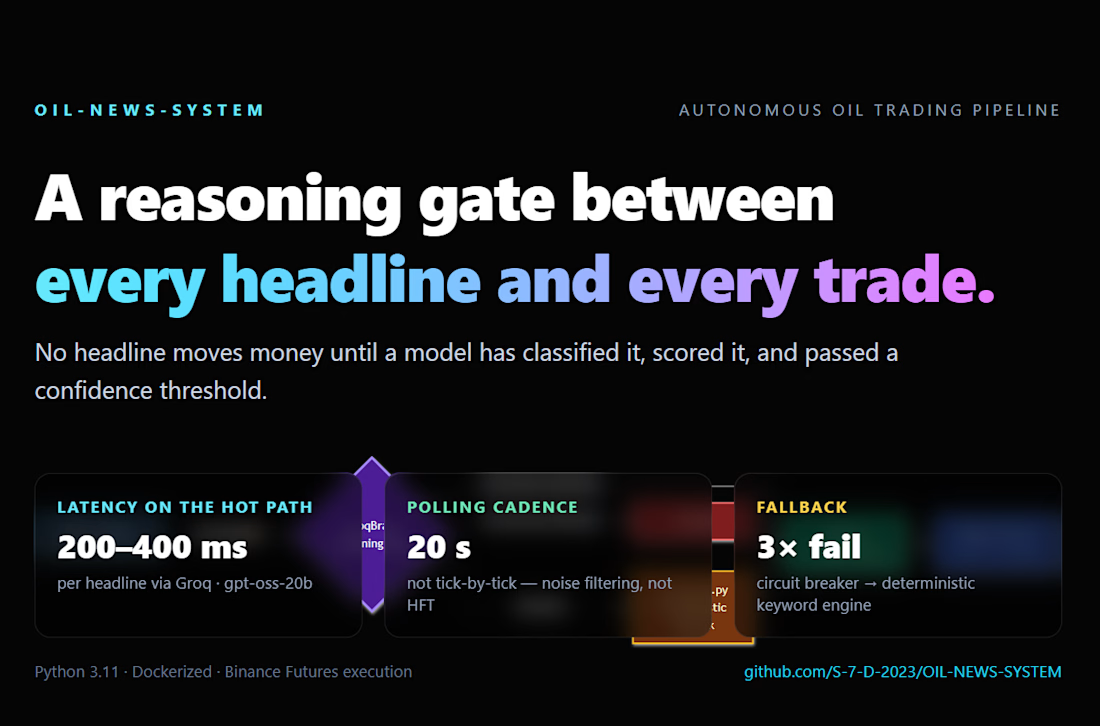
I put a reasoning model in front of every headline before a single dollar moves. The model returns four fields: Is this actually about oil? Impact (BULL/BEAR/NEUTRAL). Strength (1–5). Confidence (0.0–1.0). A trade only executes if confidence passes a hard threshold.
The Tradeoff (the latency question)
A reasoning call per headline costs ~200–400ms on the hot path via Groq (gpt-oss-20b). That sounds expensive—until you look at the cadence. The monitor polls every 20 seconds, not every tick. I am not competing in a high-frequency race. I am filtering noise before it reaches execution.
Headlines are processed sequentially, not in parallel, so every trade has a single auditable reasoning trace. If the API fails 3 times in a row, a circuit breaker falls back to the deterministic keyword engine. The system gets dumber for one cycle. It does not go dark.
The Honest Gap
There is no two-tier local/hosted setup yet. A small local model for the first gate, escalating to the hosted model only when the impact field is ambiguous, is the next optimization. I chose auditability over raw speed for v1. If you need sub-100ms decisions, this is the wrong architecture. If you can tolerate a 20-second cadence, the reasoning gate pays for itself in false-signal reduction.
The Architecture
twitter_monitor.py → primes on first poll, never trades stale news.
groq_brain.py → reasoning gate, structured JSON out.
sentiment.py → deterministic fallback.
main.py → Binance Futures execution, leverage + SL/TP locked before order.
Dockerized. Python 3.11.
The Result
A pipeline that reads the world, reasons through noise, and executes with precision. No human in the chair. No stale signals. No keyword guessing.
This is not a script. It is a system with a brain, a fallback, and an audit trail.
If you are building autonomous systems and need an execution layer that ships, my inbox is open.
#AITrading #Python #LLM #BuildInPublic #QuantDev


The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started



Related posts

AI Telemetry & Evaluation Widgets 🟢
What if AI infrastructure data felt calm instead of overwhelming? 🌿
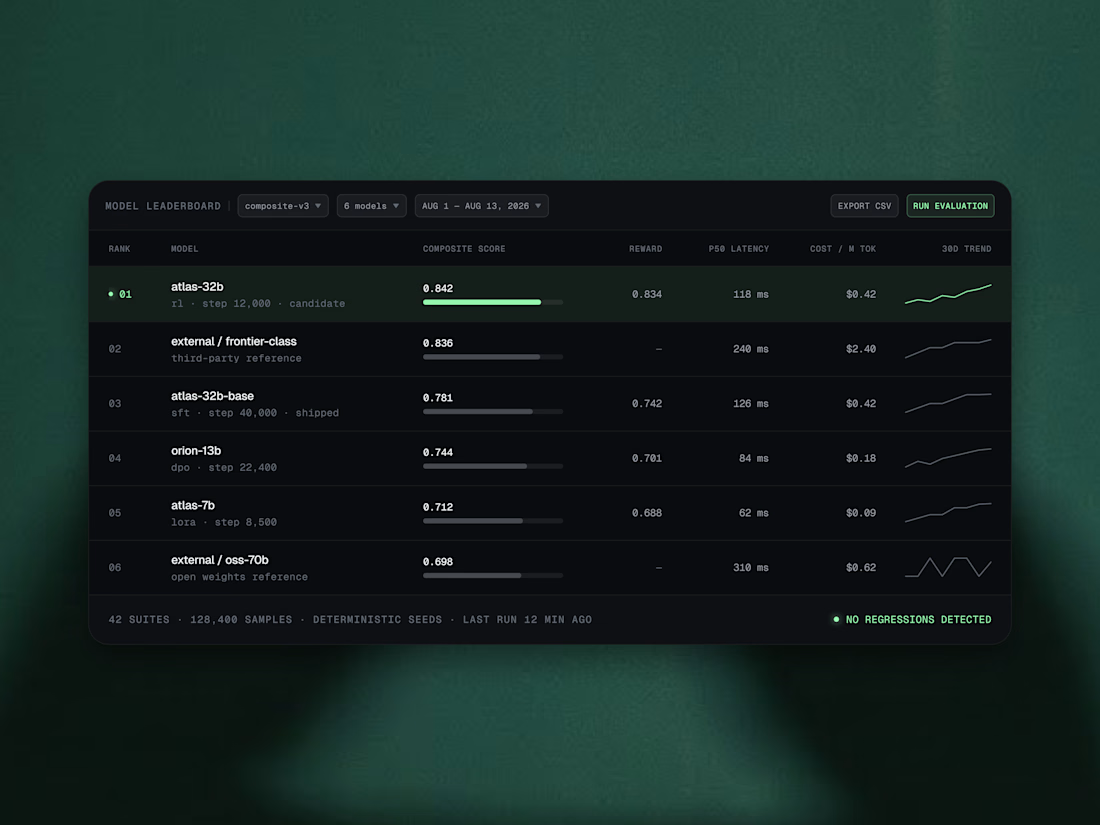
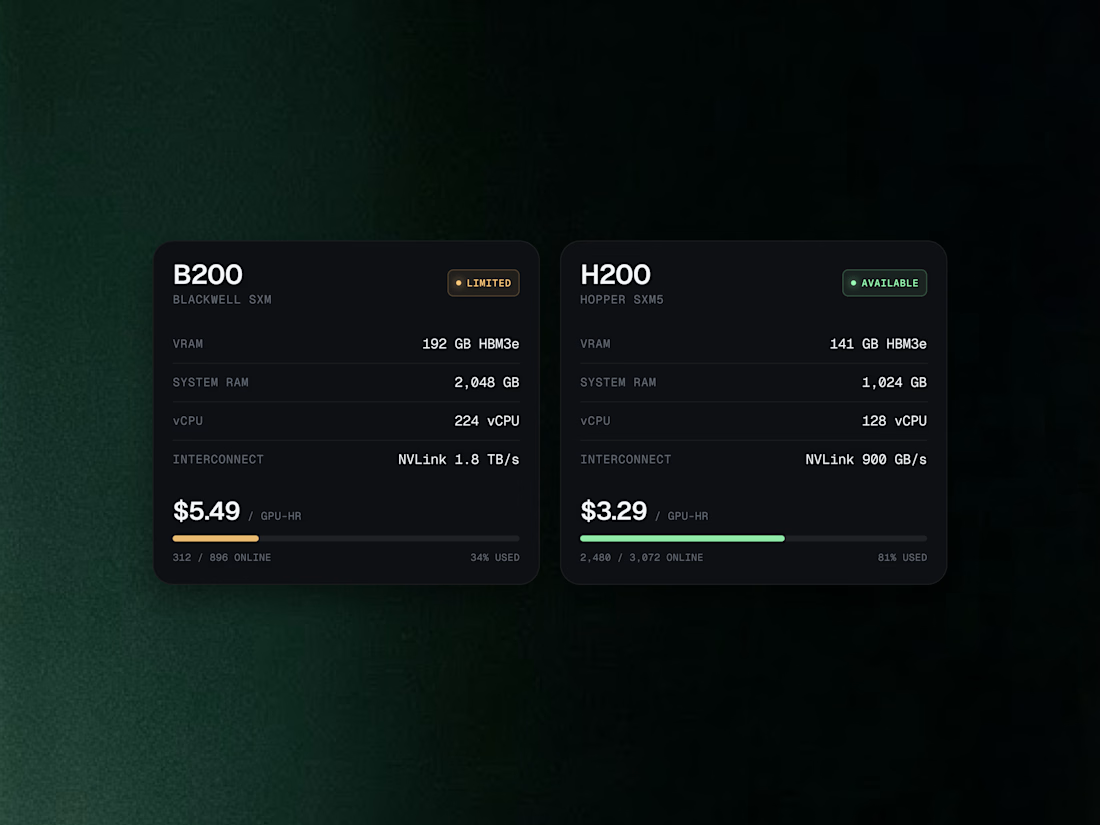
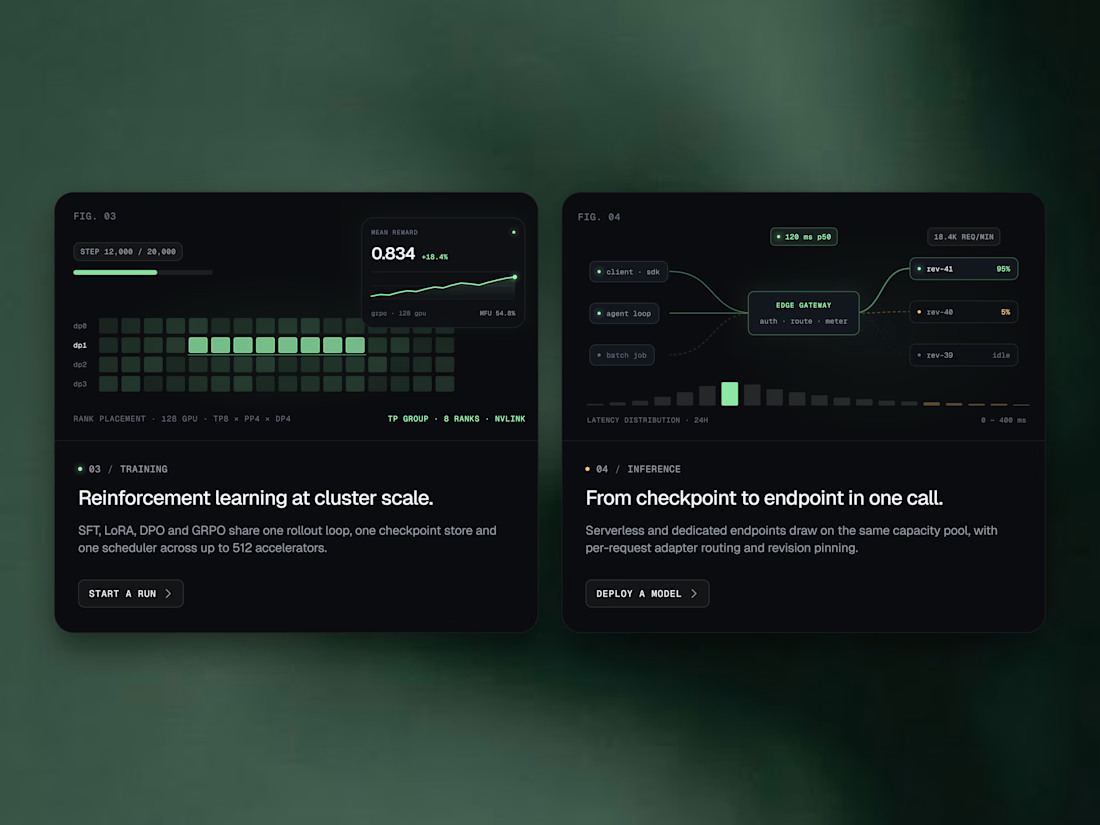
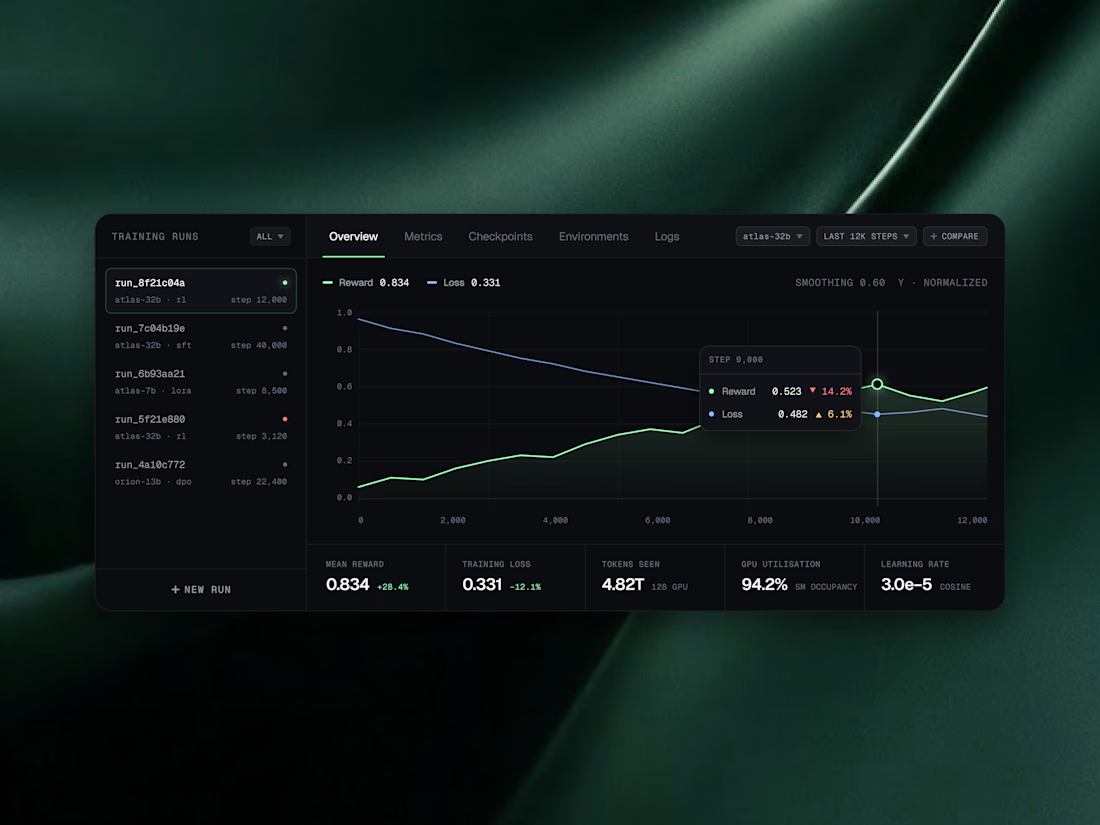
We designed a set of widgets for tracking models, GPUs, and training runs, where every score, price, and metric is easy to scan. Sleek dark cards with soft green highlights float over a rich emerald silk backdrop, turning dense telemetry into something you actually want to look at.
Swipe through the 4 frames to see the model leaderboard, GPU pricing cards, training and inference flows, and live training run charts. 👀
Which widget would you want on your dashboard first? Tell us in the comments! 💬👇
#UIDesign #UXDesign #DashboardDesign #DataVisualization #AIDesign #SaaSDesign #DarkModeUI #DeveloperTools



Nice work

AI Automation Platform — SaaS Dashboard & Mobile App UI Design
✨ Smarter Workflows, Powered by AI
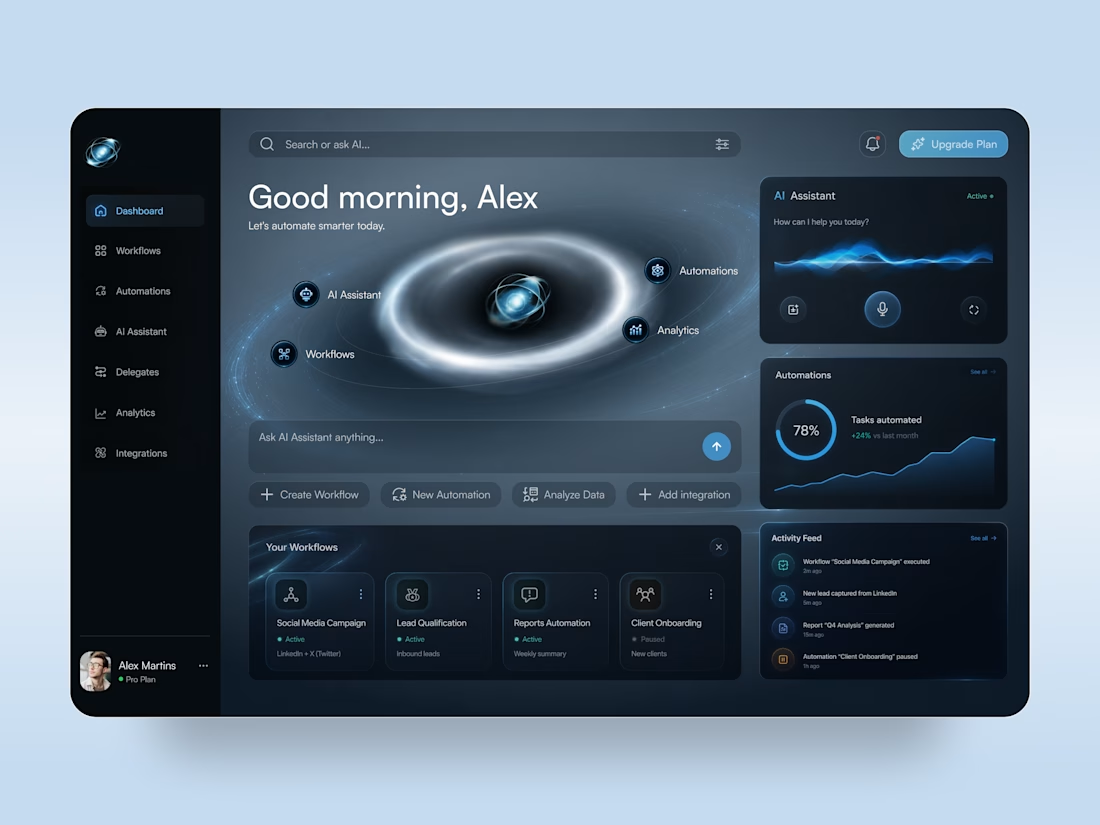
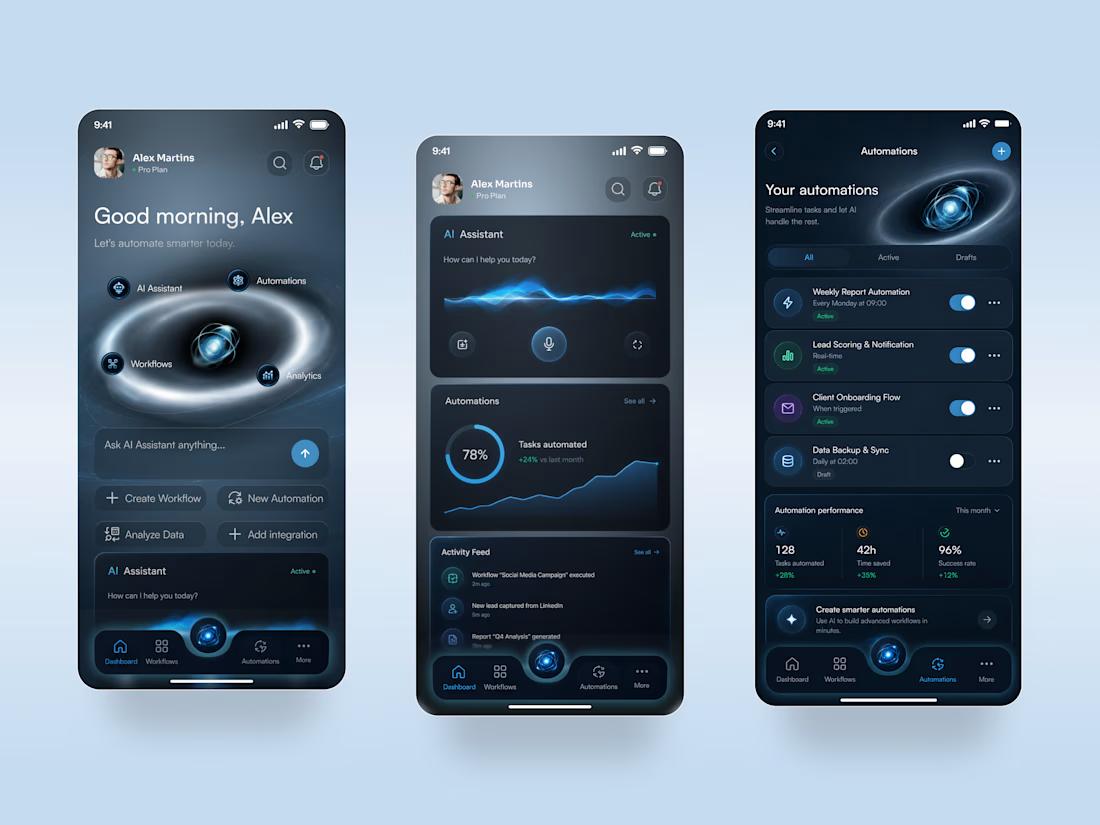
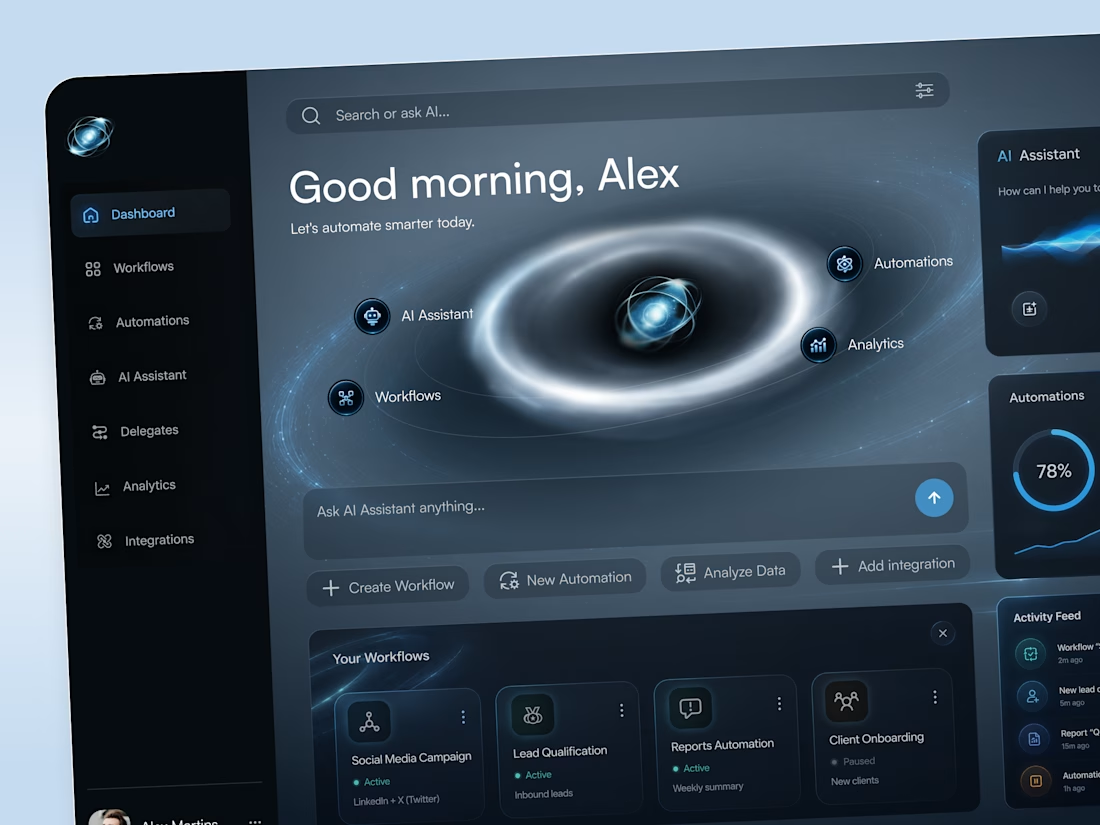
A futuristic AI automation platform concept that brings workflows, intelligent assistance, and performance analytics into one digital workspace. The design combines a deep navy interface, electric blue accents, and immersive orbital visuals to make complex automation tools feel intuitive and accessible.
Special attention was given to:
• Immersive dashboard composition with glowing orbital graphics and futuristic visual elements
• AI assistant interface featuring voice interaction controls, animated-inspired waveforms, and quick actions
• Organized workflow cards, automation management, and real-time activity feeds
• Clear analytics widgets with progress indicators, performance charts, and automation status controls
• Responsive desktop and mobile layouts with consistent dark-mode styling and streamlined navigation
The result is a modern SaaS experience that balances futuristic aesthetics with practical usability, giving users a clear view of their workflows, AI tools, and automation performance.

Another example of just how far we've come with the evolution of AI.
AI is evolving faster than ever. Every day, it's getting better at recreating human faces, voices, and expressions.
And soon, it might become so realistic that we may not even need to step in front of a camera anymore.
But that raises a bigger question.
How do we preserve the emotions and authenticity that only a human touch can bring?
This is where the "Heart" clashes with the "Brain." Human creativity versus artificial intelligence.
But perhaps this clash isn't about deciding which one comes out on top.
Perhaps it's about discovering how far we can go when human creativity and artificial intelligence coexist.


Great concept