The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

Most AI agent memory systems today are still glorified vector databases.
Store embeddings. Retrieve top-k. Inject context.
That works for RAG.
It does NOT work for production agents operating continuously over months.
The most valuable idea in “Production Agent Memory: Compaction, Decay, and the Observation Engine” is the shift from storage → behavioral learning architecture.
A few concepts that stood out to me:
• Memory should be separated into:
Working memory
Episodic memory
Semantic memory
Procedural memory
Each has different retrieval logic, decay behavior, and lifecycle.
• The Observation Engine is the real innovation.
Agents shouldn’t just “remember” events — they should detect repeated behavioral corrections and promote them into procedural rules.
Example:
If a user removes semicolons from generated emails 8 times, the system learns:
“Never use semicolons.”
That’s application-layer behavioral learning.
• The “No-Delete Principle” is incredibly important.
Low retrieval frequency ≠ low importance.
A memory from 3 months ago may become mission-critical the moment a specific client or workflow reappears.
The correct solution is compaction, not deletion.
• Tiered compaction is how long-running agents scale:
Raw Episodes → Weekly Summaries → Monthly Behavioral Patterns
This is essentially memory consolidation for AI systems.
• Hybrid retrieval (BM25 + vectors) is mandatory in enterprise environments.
Names, IDs, invoice numbers, organizations, and dates do not embed reliably enough for pure semantic search.
• Procedural memory is massively underrated.
A few validated behavioral rules injected into every prompt are often more valuable than thousands of retrieved tokens.
This is where agent systems start moving beyond “chatbots with memory” toward actual adaptive cognitive infrastructure.
The industry is slowly realizing:
Persistent agents are fundamentally a systems architecture problem, not just a prompting problem.
The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started




Related posts

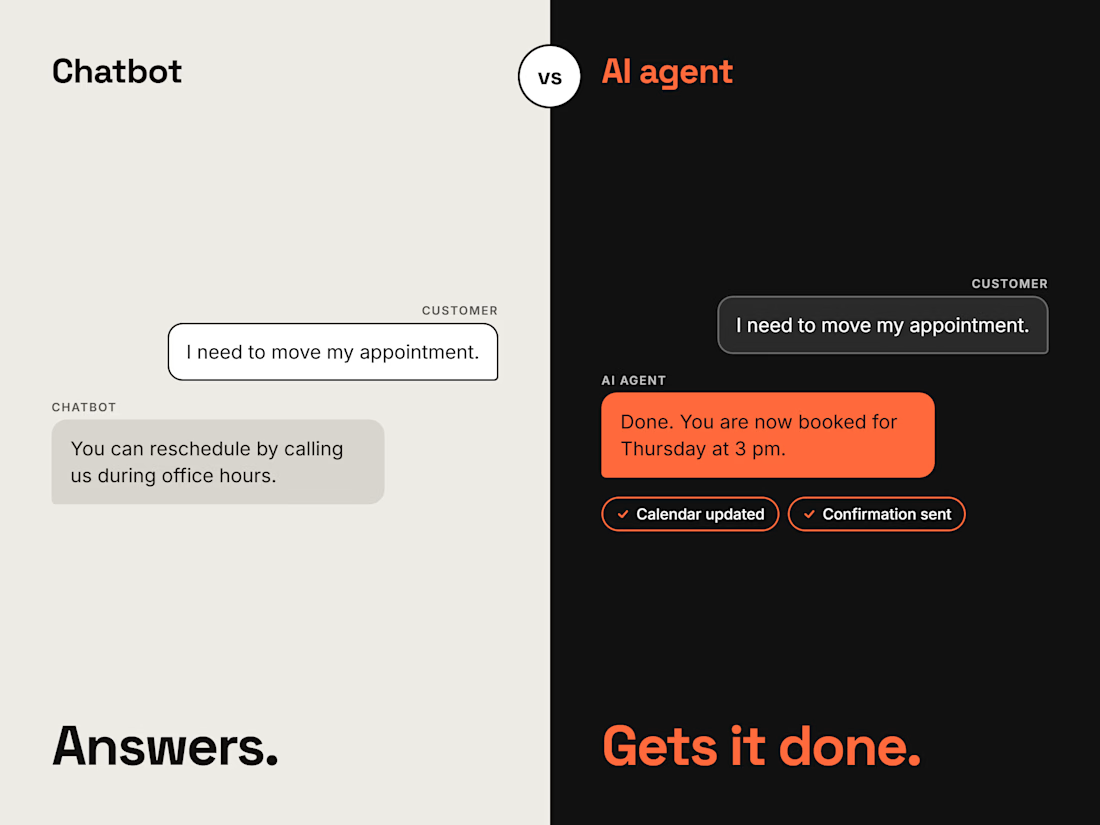
A chatbot answers. An AI agent gets it done.
Take one simple request: “I need to move my appointment.”
A chatbot tells the customer how to do it: call during office hours, wait on hold, hope someone picks up.
An AI agent does it. It checks the calendar, moves the booking, sends the confirmation, and updates the CRM. The customer is finished in ten seconds, and nobody on your team touched it.
That’s the difference I build for businesses. The agent gives the answer and also completes the task behind it.
Which task in your business still ends with “please call us”?

AI Agents, Agentic AI, Generative AI, Conversational AI, AI Automation, LLM Integration, AI Chatbot, Python Development, FastAPI Development, React Development,


An exploration of how you fix an AI answer while it’s still being written.
In most AI chats, if one line of the reply is wrong, you wait for the whole answer, then retype the request and start over. Here you tap the sentence that’s off, choose Correct, and say what should change in your own words. The fix waits in a queue in the input bar while the plan keeps writing, then folds into the reply in place. You see the old line struck through and the new one highlighted, with an Undo.
Every claim in the plan cites its source, and your correction appears beside them as a source too. That way you can always see why the plan says what it says.