The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost
BREAKING NEWS FROM THE FUTURE 🚀
Part 1 of Tomorrow News is officially on its way to the New York Lift-Off Film Festival 2026.
A satirical animated journey through tomorrow's headlines, created with imagination, AI, and a little bit of madness.
Made with @CapCut Dreamina Seedance 2.0 😍 @Marlenn Alba
Stay tuned... Tomorrow's news starts today.
#DreaminaCPP #DreaminaAI #CapCutCPP #Capcut #Seedance2 #AIAnimation #AIVideo


This is gold! 😂👏🏼

Thank you!🙌 😍

Interesting
Thanks a lot!😍

Cool
Thanks so much! 🙌 😍
The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started

Challenges
View all


Related posts

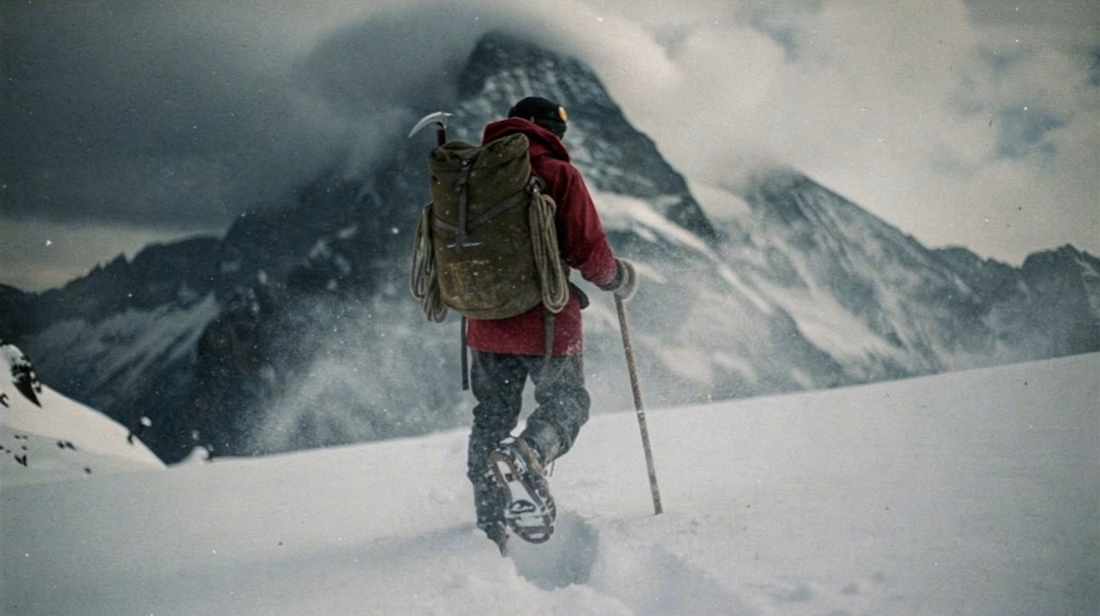
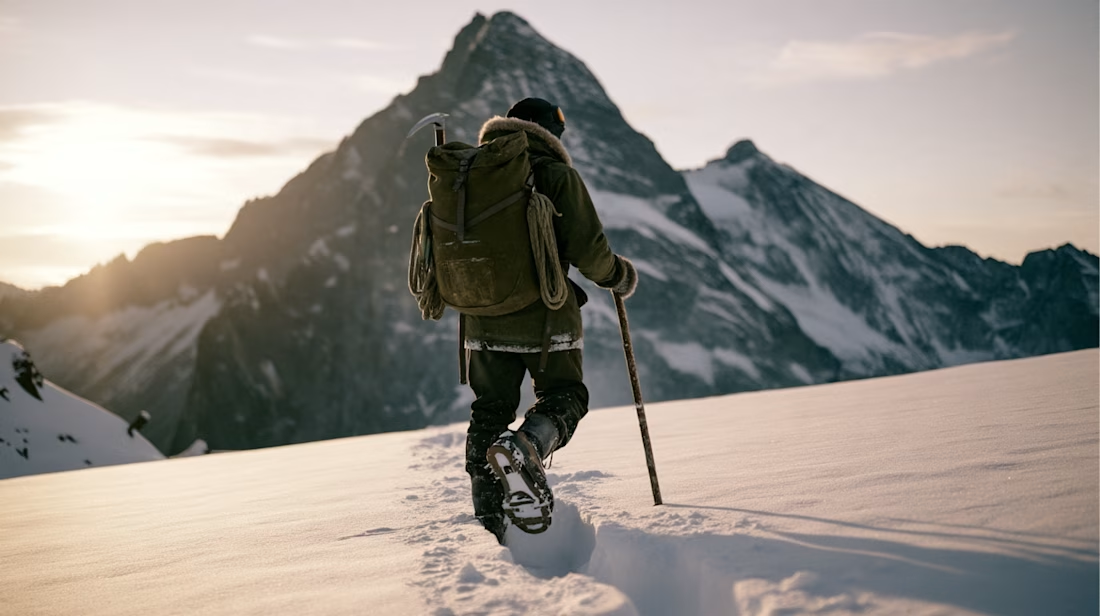
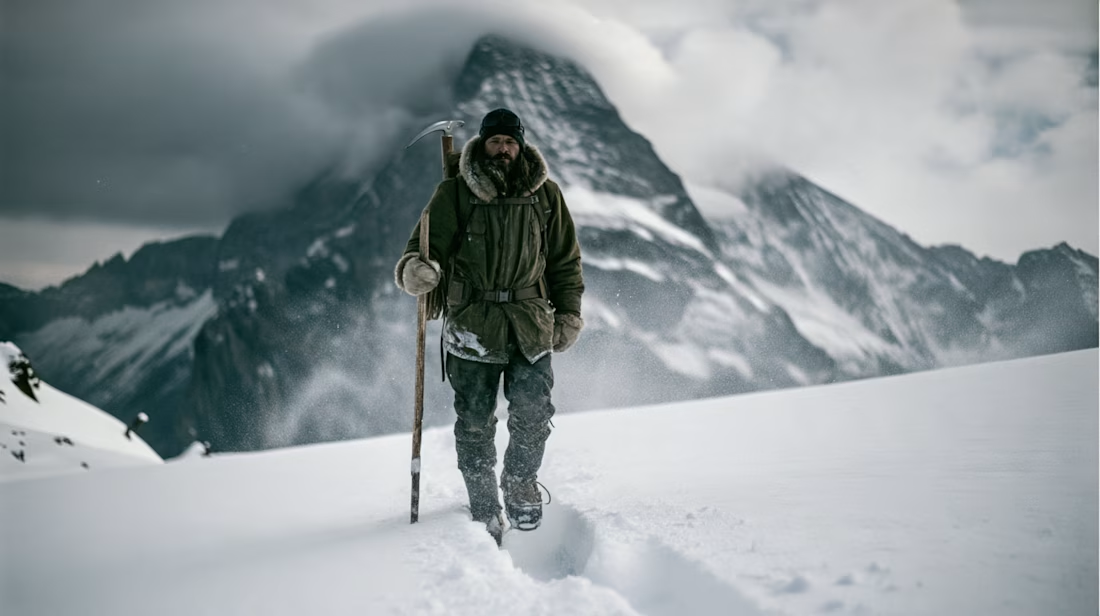
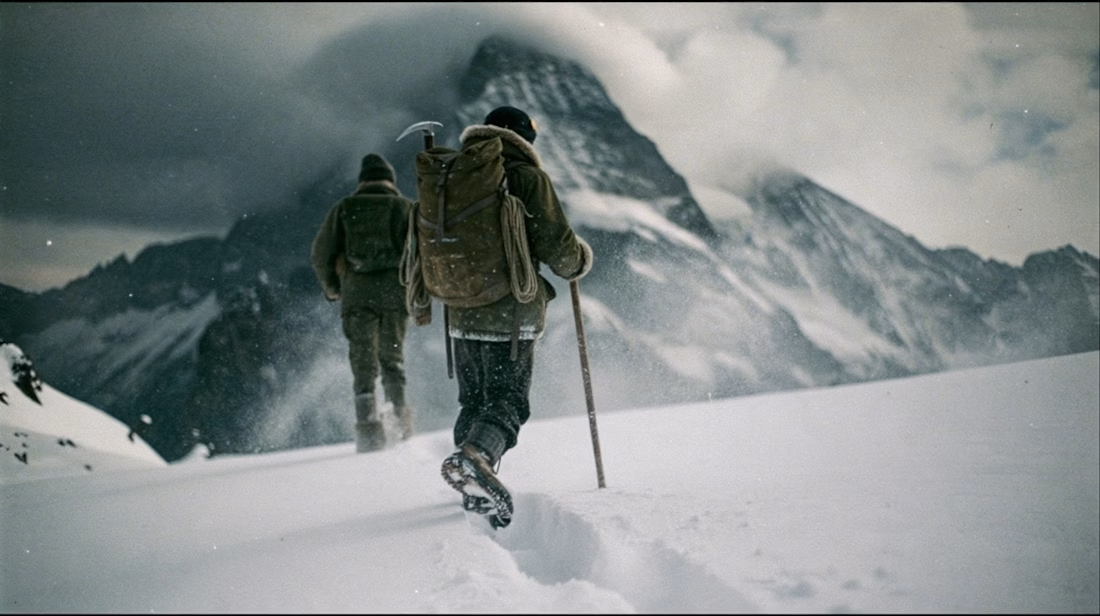
What happens when you take a hero frame from an AI-generated video and push it back into an image edit model?
This weekend I took a still from a recent Seedance 2.5 piece I made —depicting a solo mountaineer in a harsh alpine environment — and ran it through Midjourney's new v8.2 edit model to see how far I could iterate on a single frame without regenerating from scratch.
Tested wardrobe swaps, environment shifts, and style transfers.
Video walkthrough of the process coming in a separate post.


This looks cool

Experimented a bit today with Krea and image generation for a case study I’m putting together around AI EarPods connected to OpenAI.
The focus has been on creating fashion-forward product imagery and art directing a world that feels specific to the identity, rather than just generating nice-looking AI images.
The trickiest part has been product consistency. Especially getting the EarPods to actually sit snug in the ear. If you’ve worked through this process, you probably know the struggle 😅
Simply telling AI to “make it fit more snug or in the ear” doesn’t always work. It loves to reinterpret the product every time.
Still experimenting, but getting closer. If anyone has found a good workflow for keeping products consistent across AI-generated shoots, I’d love to hear it!


TOP!

Recent design project. The cube was created in Midjourney, refined and cleaned up in Photoshop (yeah), video generated in Google Flow. Interface and icon animations made with Figma. I hope it works okay for iPhone Duo too.
I still can’t seem to master the whole “design in one prompt” thing. What am I doing wrong? /s


Creative approach