The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

Nurses are the best AI auditors in your hospital. You're just not asking them
The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started





Related posts

Reading a document is easy. Understanding its meaning is the real challenge.
While building AI-powered medical document intelligence systems, I’ve been learning that extracting words is only one part of the problem.
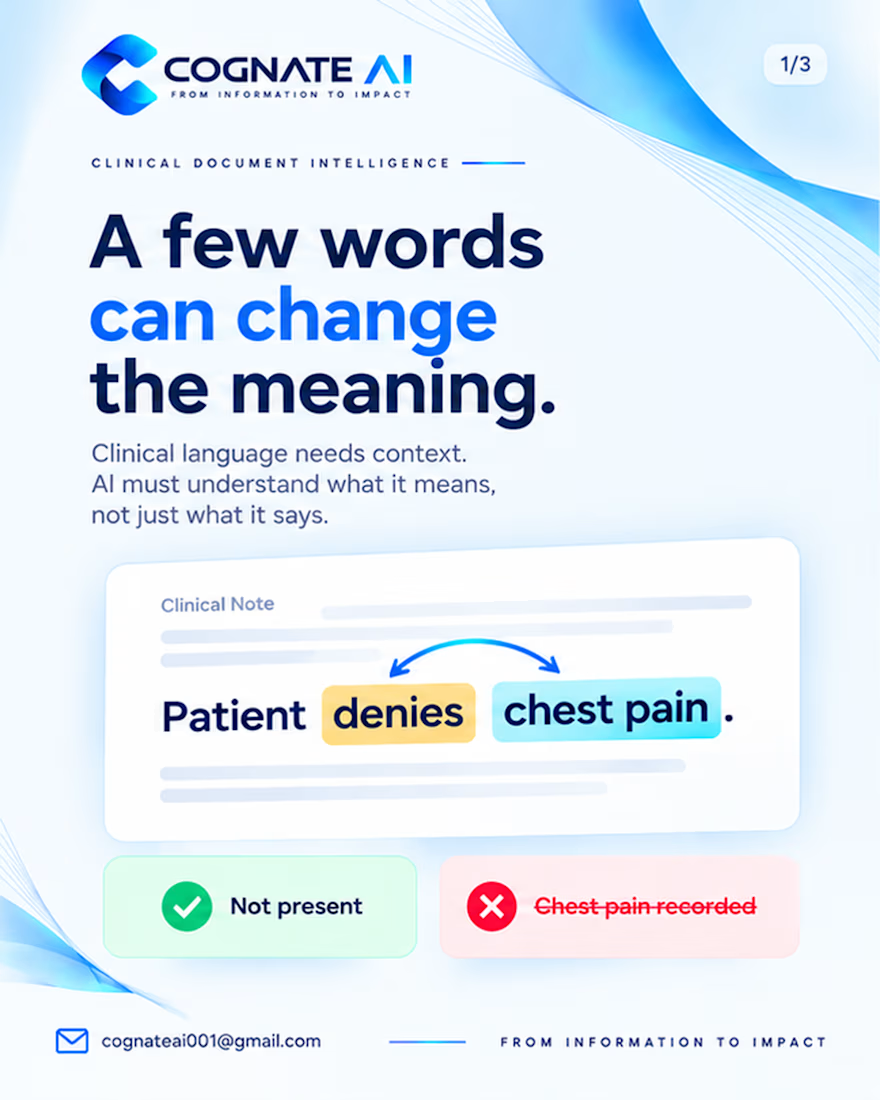
Consider this sentence:
“Patient denies chest pain.”
A system might recognize the words correctly but still extract the wrong information if it ignores the word “denies.”
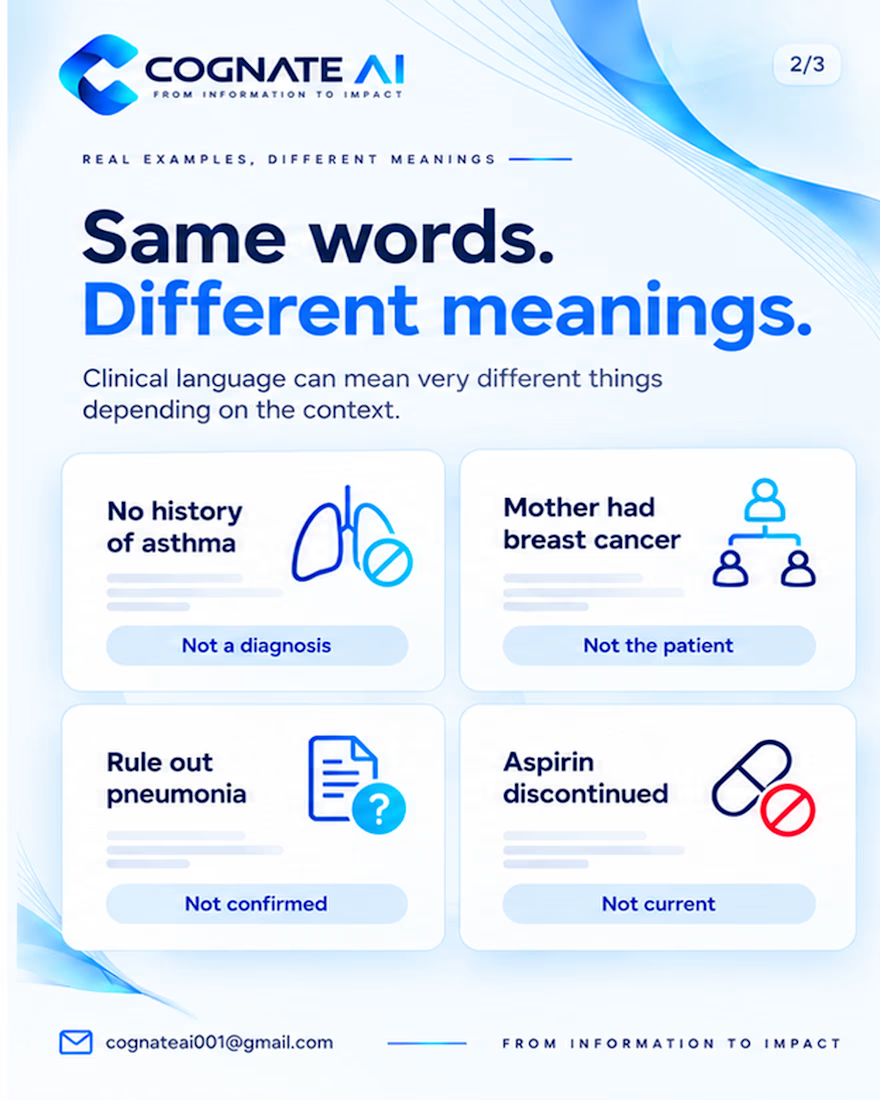
The same challenge appears in phrases like:
“No history of asthma”
“Mother had breast cancer”
“Rule out pneumonia”
“Aspirin discontinued”
Each sentence requires more than text recognition. It requires understanding context, negation, uncertainty, relationships, and whether information is current.
This is one of the challenges I’m exploring while building MDIS (Medical Document Intelligence System) at Cognate AI.
My focus is on developing systems that go beyond extracting information—toward structured outputs, validation, evidence traceability, and human review.
Because in healthcare AI, extracting the right words is not enough. The system must preserve what those words actually mean.
I’m continuing to learn, build, test, and improve this system one step at a time.
What do you think is the biggest challenge in making AI understand clinical language accurately?
#AIEngineering #HealthcareAI #MedicalAI #DocumentIntelligence #BuildingInPublic



I build AI that’s measured before it ships. Now open for freelance work.
Most AI features fail quietly. No one measured them, and the numbers come straight from the model. My work fixes both.
What I’ve built:
→ A multi-agent tax copilot for UAE–US businesses, live in production. The LLM reads the documents and cites the rule, and a deterministic engine does every calculation. 89% answer correctness on a human-reviewed eval.
→ An evaluation harness for legal AI. It benchmarked three frontier models on contract clauses (F1 0.88–0.90) and found a failure mode all three share: they cut off the legal condition that actually matters.
→ A brain MRI research platform with 3D lesion segmentation, sealed audit trails and FHIR export.
→ A pricing tool for metals traders that turns offer sheets (Excel, PDF, photos, voice) into priced bids.
→ Voice agents: a voice-to-clinical-note scribe, and a browser agent you control by speaking.
How I can help:
• AI agents and RAG systems, with evals built in
• Reliability audits for an AI feature you already shipped
• Document extraction from PDFs, sheets and scans
• Voice agents for calls and intake
• Healthcare AI workflows
If you have an AI feature that’s unreliable, or one you haven’t built yet, send me a message. First 3 clients get a priority start this month.
#AIEngineering #LLM #AIAgents #RAG #HealthcareAI