The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

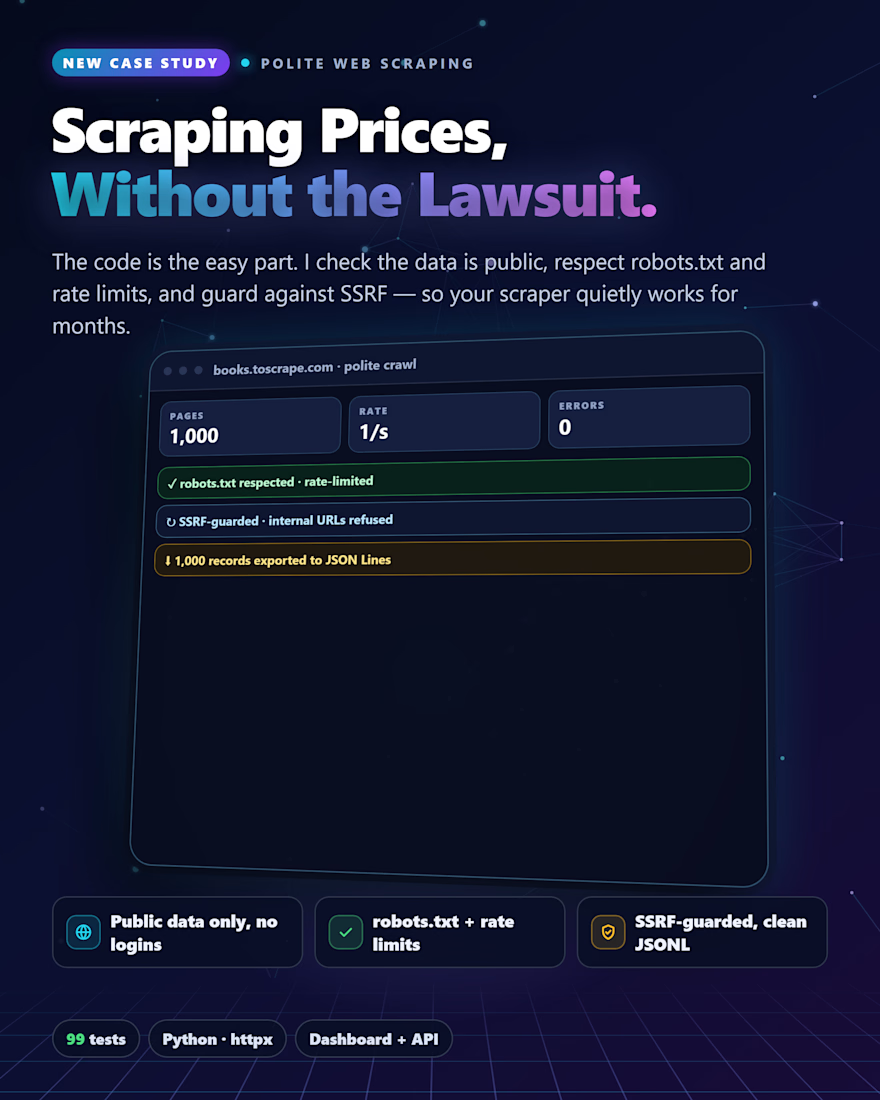
Half the "web scrapers" sold online would get a real business blocked, or a cease-and-desist.
When a client asks me to scrape competitor prices or build a lead list, the risky part isn't the code. It's what the scraper touches and how hard it hits.
So before any scraping job, I check three things:
Is the data public, and do the site's terms allow it? No logins, no paywalls, no personal data.
Does it respect robots.txt and rate limits, so it reads like a polite visitor, not a flood?
Is it guarded against SSRF and bad input, so a crawled URL can never reach an internal system?
On a real price tracker I built, a page once came back "successful" but empty, and nearly overwrote good data. Now an unreadable page is refused, and a change is only logged when the new price differs from the last real one.
Boring? Yes. But it's the difference between a scraper that quietly works for months and one that gets your client in trouble.
What do you check before you point a scraper at a site?
The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Related posts

FirstReply — reply first, win the booking
Description
Event venues lose bookings because they reply a day late. By then the client has booked somewhere else. FirstReply answers every inquiry with a priced proposal and a held date in seconds.
The automation
1. An inquiry arrives from the venue page, or staff paste in an email.
2. AI extracts event type, date, guests, budget and requests, each with a confidence level and the exact words it came from.
3. Missing date or guest count? It writes a clarifying reply instead.
4. It matches the smallest free space that fits (or the two nearest free dates when it's booked), prices the right package and holds the date for 5 days.
5. The client gets their own proposal page and books with one tap. The hold becomes a confirmed booking.
6. Unsure details, over-budget totals or Review mode send it to a review queue first. Humans step in only when needed.
7. Views, acceptances and expiring holds update the pipeline and alert the team live. Every step is logged to the second.
The design A full design system first (tokens, type scale, components), built as a clickable prototype, then rebuilt in Base44 from prompts. Client pages are mobile-first; the venue side is desktop-first.
Try it Client side: firstreply.base44.app · Venue side: firstreply.base44.app/dashboard


From a packing-slip PDF to a shipment your team can track.
This TechFoundry IMS demo matches boxes, parts, and weights from the vendor document and connects courier tracking to the shipment record. A practical example of the AI and automation workflows we build into business software.
Watch the vendor shipment demo:
https://www.youtube.com/watch?v=FmjdRRfUZh8
#AI #Automation #SoftwareDevelopment #SupplyChain

Small automations like these can save teams so much manual work and reduce errors.

Skycall 🎈: the dawn call, made automatically
An AI-powered operations brain for hot-air balloon operators, wrapped in a cinematic, living website. Tomorrow’s forecast comes in, the call gets made, and every passenger hears about it, with nobody working the phones.
Every balloon operator knows the feeling: it’s 6 pm and the forecast just changed. The pilot is reading wind at three heights while dozens of passengers set alarms for 4 am. Then the phone tree starts: voicemails, the wrong hotel, a family that flew halfway around the world, told at midnight. Tomorrow evening, the same again. Skycall turns that whole evening into one automated flow, so a small operator can run like a big one.
The problem: dawn flights live or die on the wind, and every “no” lands on a person with a phone. Rebooking is done by hand, empty seats go unfilled, and reviews blame the operator for the sky. The decision belongs to the pilot. The messaging shouldn’t eat their evening.
The solution:
The evening call. At 18:00 Skycall reads tomorrow’s forecast at the surface, 80 m and 180 m, checks it against the operator’s own limits, and calls it GO, HOLD or NO-GO, with the reasons in plain English.
Every passenger told automatically. Each one gets an email with the verdict, meeting point, what to wear and a calendar link.
The dawn recheck. Two hours before launch it looks again, and only writes if the sky changed.
One-tap rebooking. A no comes with two flyable dates, one tap each. Quiet after 24 h? A reminder. Still quiet? Pencilled onto the next flyable dawn.
Waitlist seat fill. On a GO with empty seats, the waitlist gets a 45-minute offer, and the first tap wins.
The crew manifest. The pilot’s phone shows passengers, basket load against the maximum, a hot-dawn warning and the hotel pickup order.
A Monday digest for the owner, plus a public ops log where every automated run is on the record.
A live demo console where anyone can run the call on any sky and watch it happen.
Built on Base44: 15 entities and 21 backend functions sharing one rules engine. The forecast comes live from Open-Meteo, and scheduling runs via an external cron hitting a Base44 backend function. This build runs a demo operator: the operator and bookings are demo data, and the passenger emails go to a demo inbox. The forecast, the decisions and the sends are real.
Skycall is a planning aid. Every verdict is advisory, and the pilot in command decides.
🔗 Skycall

Really interesting concept! The best part is that this goes beyond weather alerts and automates the entire operational workflow, from flight decisions and passenger notifications to rebooking and waitlists. Keeping the final decision with the pilot is an especially important touch. Great use of automation!