The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost
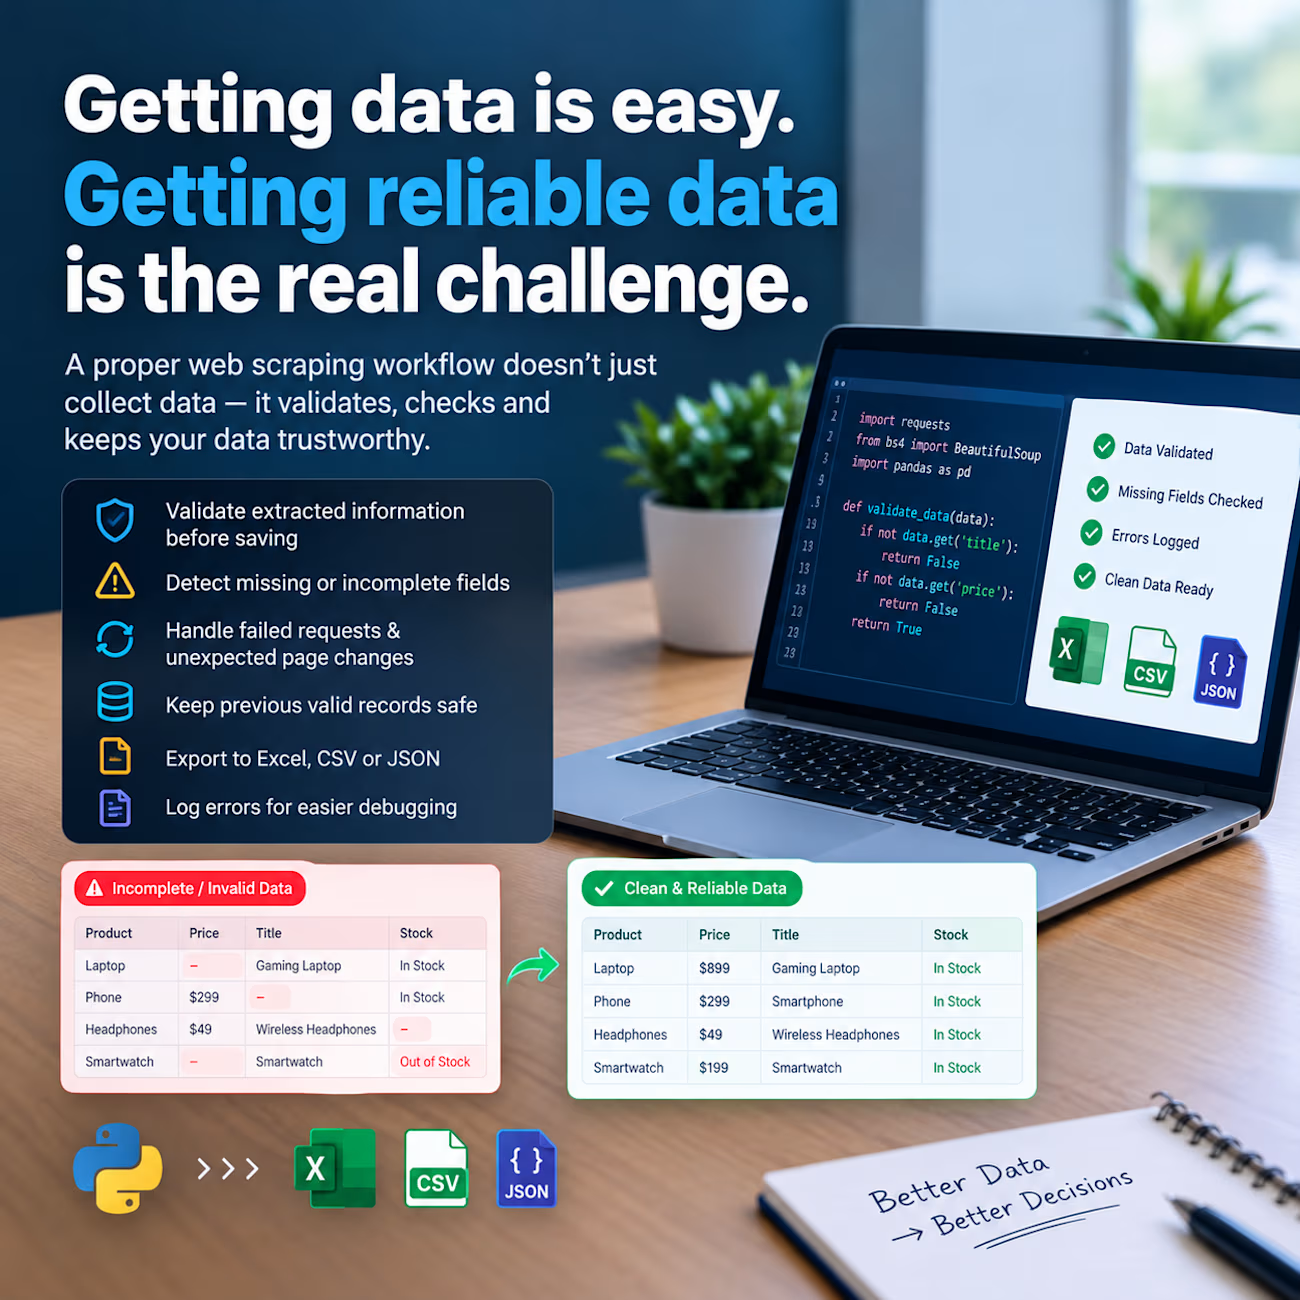
Getting data is easy. Getting reliable data is the real challenge.
Imagine your scraper runs successfully, but the website returns incomplete information.
A product has no price.
A listing has a missing title.
A page loads, but the data is outdated.
If your system saves that information without checking it, your entire dataset can become unreliable.
That's why a good web scraping workflow should do more than collect data.
With Python, you can build systems that:
→ Validate extracted information before saving
→ Detect missing or incomplete fields
→ Handle failed requests and unexpected page changes
→ Keep previous valid records safe
→ Export clean data to Excel, CSV, or JSON
→ Log errors for easier debugging
The goal isn't just to collect more data. It's to make sure the data is useful and trustworthy.
At ScrapePro Solutions, I focus on building practical web scraping and automation workflows around real business requirements.
What's more important for your business: collecting data quickly or ensuring it's accurate?


The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started






Related posts

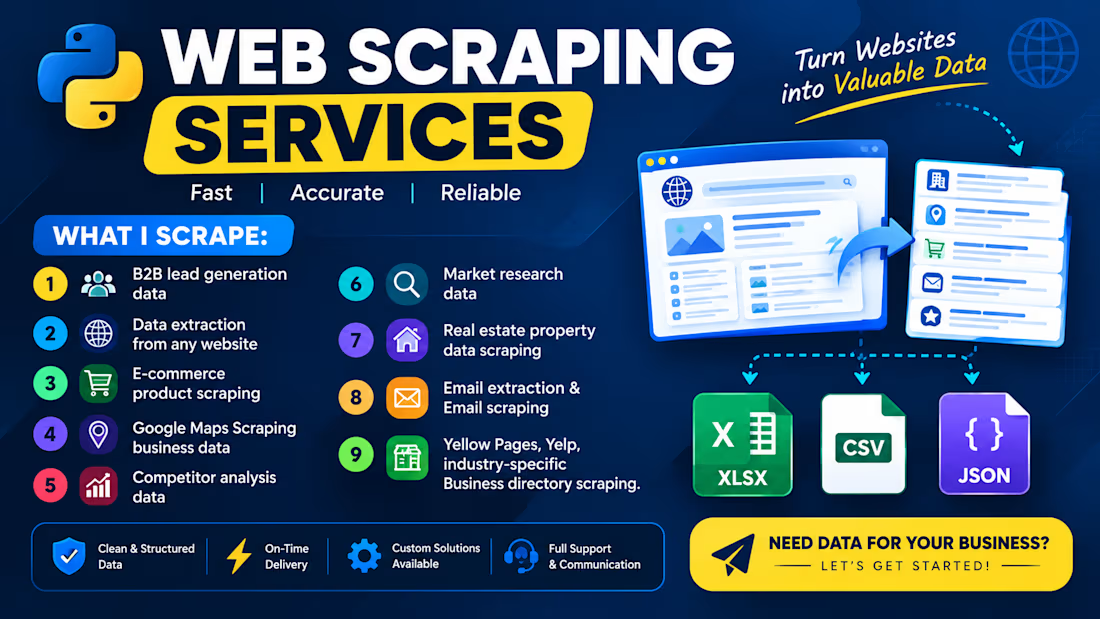
Web Scraping Services
WHAT I SCRAPE:
1. B2B lead generation data
2. Data extraction from any website
3. E-commerce product scraping
4. Google Maps Scraping business data
5. Competitor analysis data
6. Market research data
7. Real estate property data scraping
8. Email extraction & Email scraping
9. Yellow Pages, Yelp, industry-specific Business directory scraping

Nice work

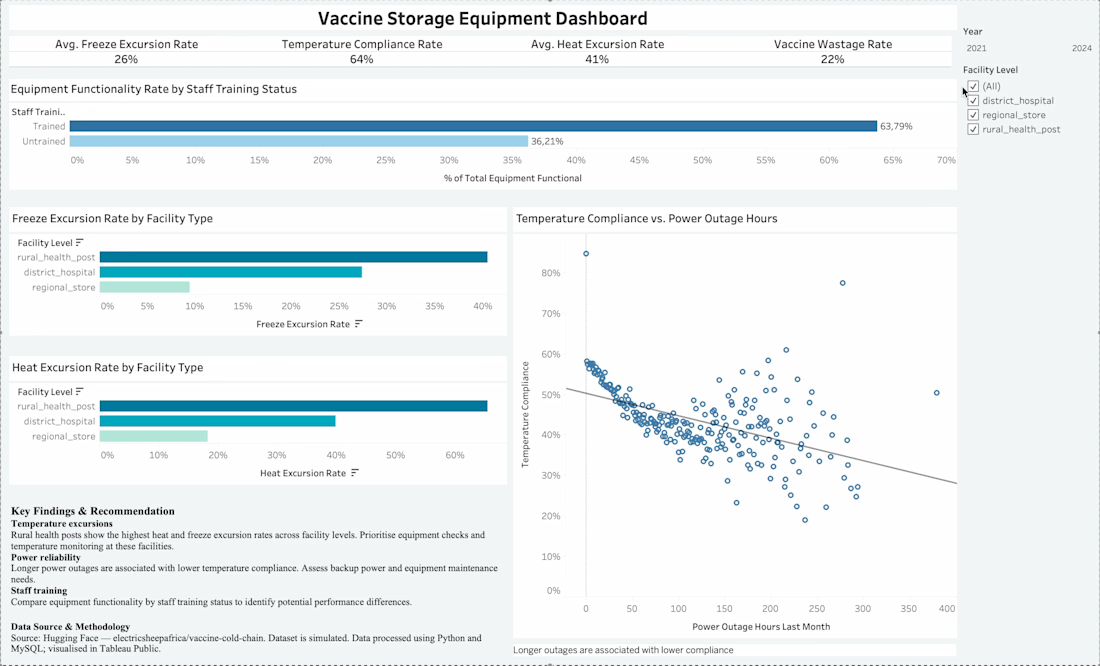
Understanding Vaccine Cold-Chain Performance
I used stimulated data to examine the effect of storage equipment and associated variables on vaccine excursion.
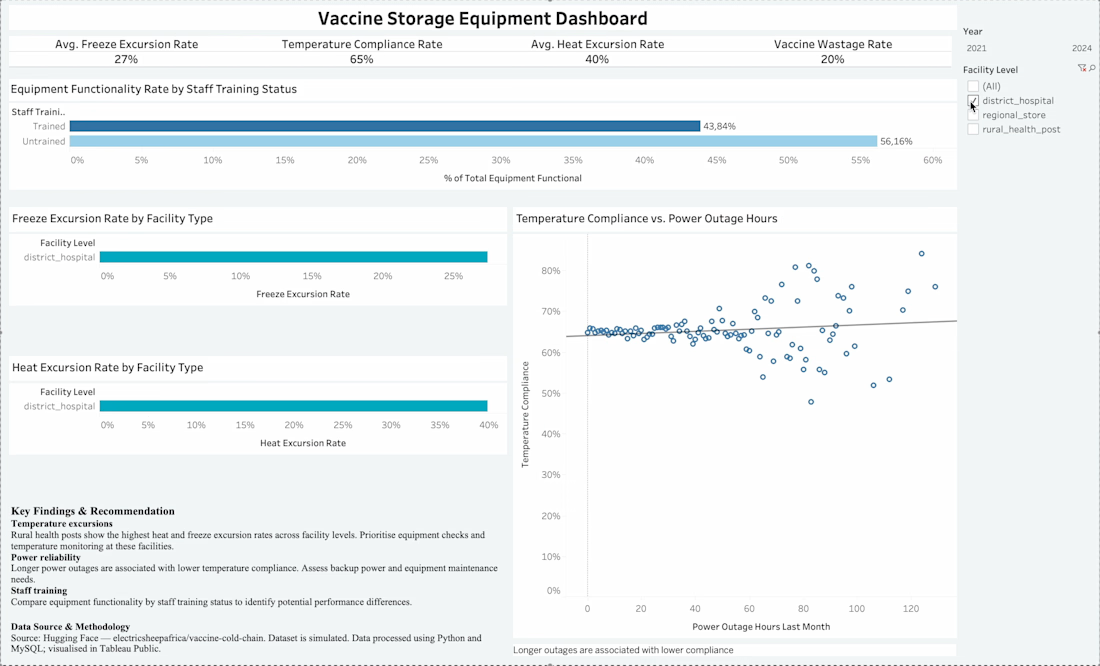
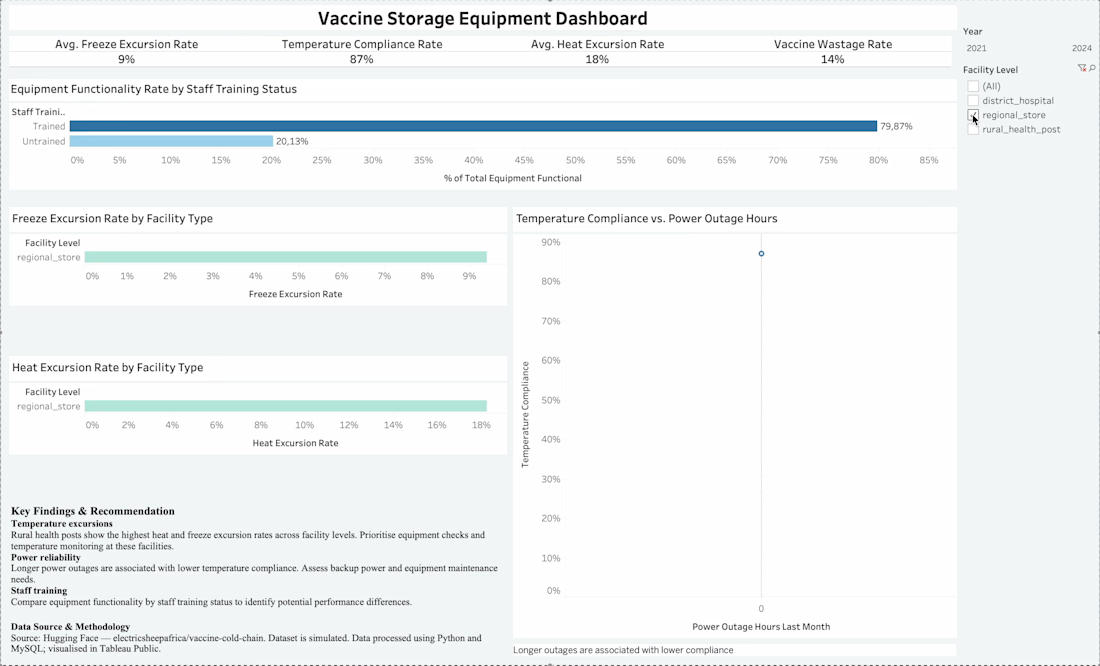
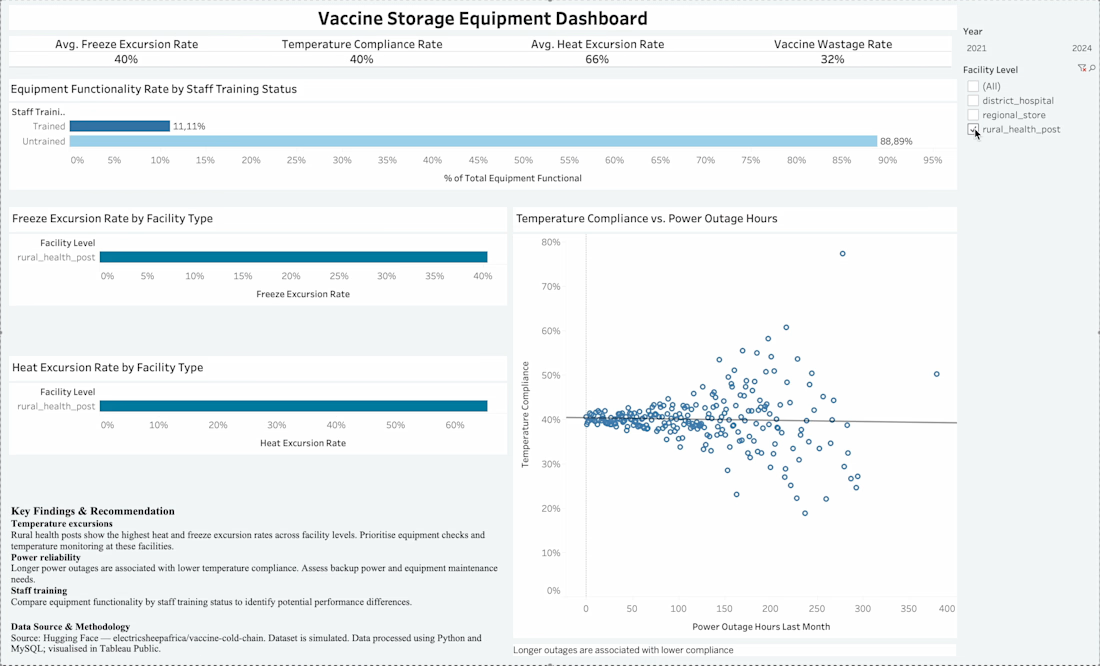
I downloaded the Vaccine Cold Chain Management dataset from Hugging Face using Python. I organized and combined the data from regional vaccine stores, district hospitals, and rural health posts using MySQL, then used Tableau Public to build an interactive dashboard exploring equipment functionality, staff training, temperature compliance, vaccine wastage, and power outages.
Three key insights were uncovered.
Rural health posts recorded the highest heat and freeze excursion rates.
Longer power outages were associated with lower temperature compliance.
Reliable equipment alone isn't enough. Staff training and proper maintenance matter too.



Very interesting 👌

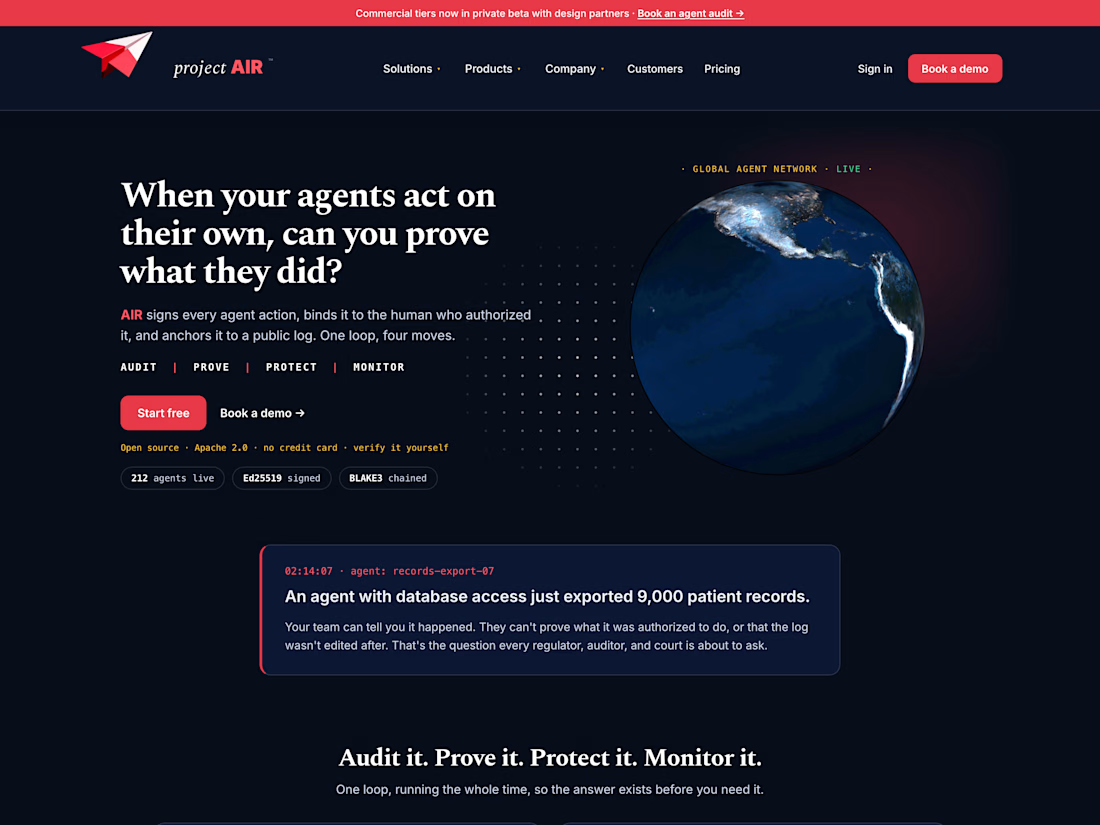
Project AIR is an open-source toolkit that keeps a tamper-proof record of what AI agents do. Every action an agent takes gets signed, chained to the step before it, and tied to the person who authorized it. The chain is anchored to Sigstore Rekor, a public transparency log, so anyone can check later that nothing was changed or deleted. When something goes wrong, you can show exactly what happened and who approved it, instead of just saying it happened.
It also runs 16 detectors over every record, covering all ten risks on the OWASP Top 10 for Agentic Applications, three from the OWASP list for LLM apps, and three of its own. It can stop an agent mid-action until a person signs off. It plugs into LangChain, LlamaIndex, and the OpenAI, Anthropic and Gemini SDKs with a line or two of code.
I built the Python library and command-line tool, published on PyPI as projectair (now at version 1.3.1) under the Apache 2.0 license, plus the website and dashboard in SvelteKit. We run it on our own infrastructure too: every request to vindicara.io is recorded and anchored to Rekor every minute.



Impressive work! 👏 Excellent approach to AI agent security, tamper-proof audit trails, and human oversight for more trustworthy AI systems.