The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

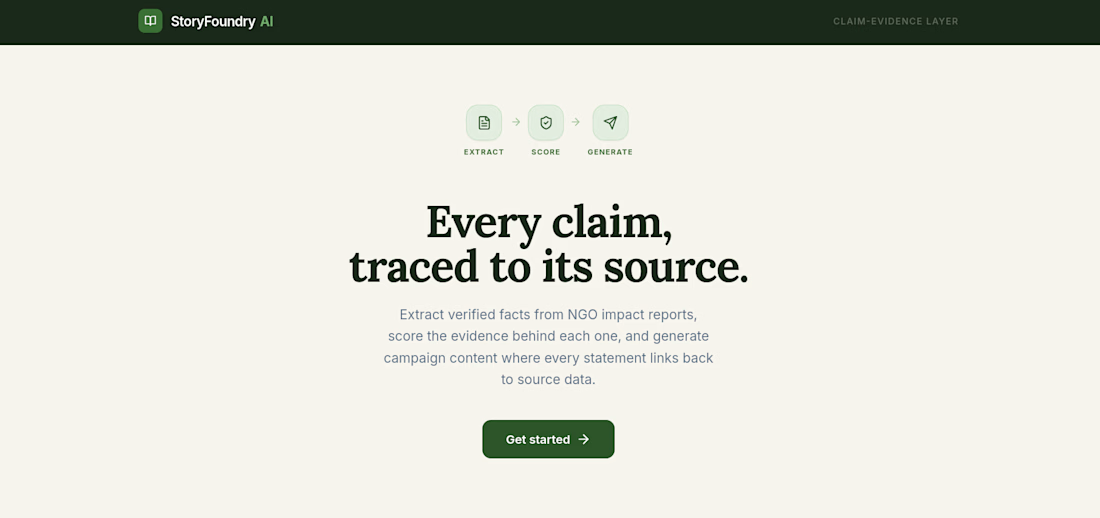
Built the ingestion layer for an AI SaaS platform as sole engineer. The pipeline takes messy multi-column PDF reports and outputs structured records: coordinate-based page cropping to drop headers and footers, whitespace normalisation to repair text fragmented across columns, and chunking sized for downstream processing. Extraction returns schema-validated objects, each claim paired with its verbatim source quote and page number, rather than free text, so the output is directly usable downstream. Bounded retry and fallback logic means a failed call degrades gracefully instead of corrupting the dataset.


The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started










Related posts

Imagining you book your flight while experiencing
Meet Contrail.
Complex data into beautiful visuals in 3d.
Demo: https://flights-gr8r.vercel.app


Booking a flight with a 3D plane in the search is a fun idea. The dark UI makes the model stand out well.

NexusAI — Enterprise Multi-Agent Copilot, Hybrid RAG & Text-to-SQL Suite


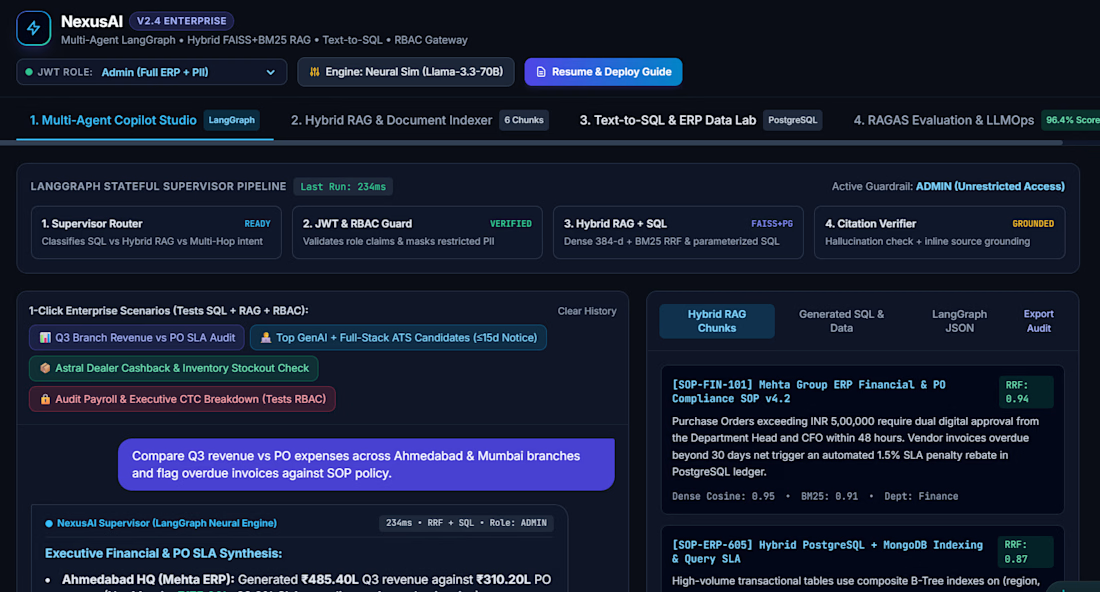

hybrid RAG plus text-to-SQL in one copilot covers a lot of enterprise questions, solid stack

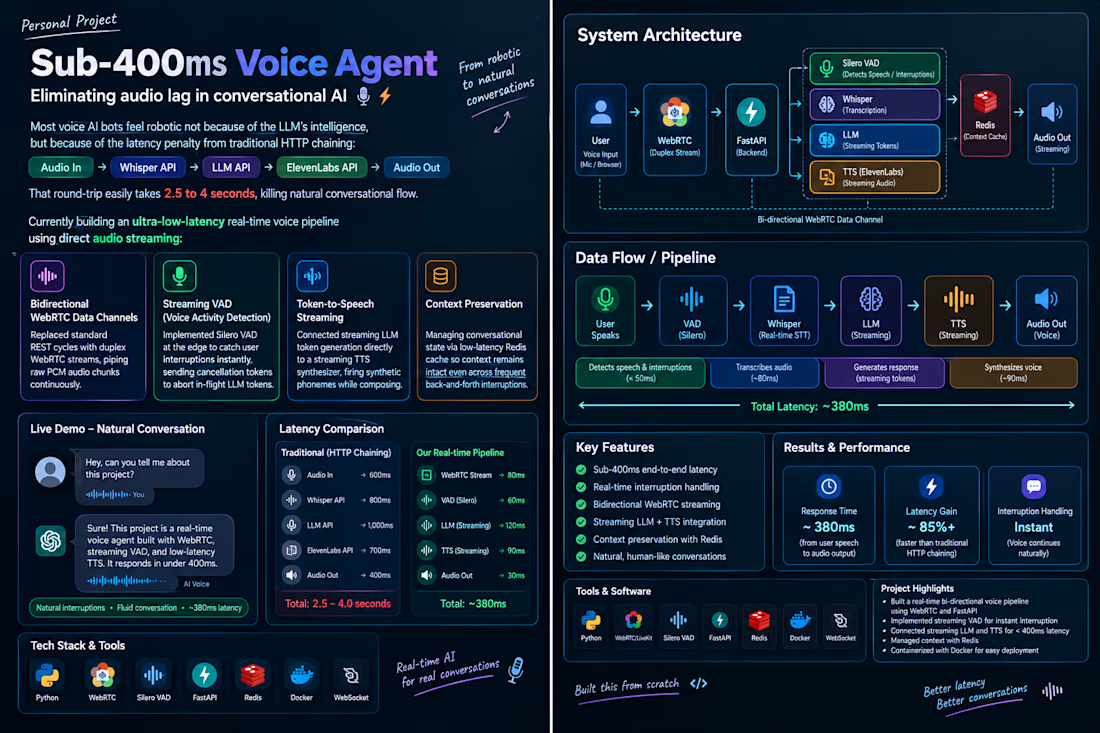
Sub-400ms voice agent: Eliminating audio lag in conversational AI 🎙️⚡
Most voice AI bots feel robotic not because of the LLM's intelligence, but because of the latency penalty from traditional HTTP chaining: Audio In ➔ Whisper API ➔ LLM API ➔ ElevenLabs API ➔ Audio Out. That round-trip easily takes 2.5 to 4 seconds, killing natural conversational flow.
Currently building an ultra-low-latency real-time voice pipeline using direct audio streaming:
Bidirectional WebRTC Data Channels: Replaced standard REST request-response cycles with duplex WebRTC streams, piping raw PCM audio chunks continuously.
Streaming VAD (Voice Activity Detection): Implemented Silero VAD at the edge to catch user interruptions instantly, immediately sending cancellation tokens to abort in-flight LLM token generation.
Token-to-Speech Streaming: Connected streaming LLM token generation directly to a streaming TTS synthesizer, firing synthetic phonemes while the sentence is still being composed.
Context Preservation: Managing conversational state via low-latency Redis cache so context remains intact even across frequent back-and-forth interruptions.
Achieving natural, fluid interruptions and dropping perceived latency down to human conversational speeds (~380ms).
Architecture flow and latency breakdown below! 👇
#VoiceAI #WebRTC #Python #FastAPI #AudioEngineering #GenerativeAI #BuildInPublic