LLM Pipeline Reliability Review in 1 WeekLukas Janda
For teams whose LLM feature (scoring, extraction, classification, summarising) runs fine in a demo and fails quietly in production.
I read how the pipeline actually works, find the places it can go wrong without anything erroring, and hand you a prioritised list of fixes plus the tests that keep them fixed.
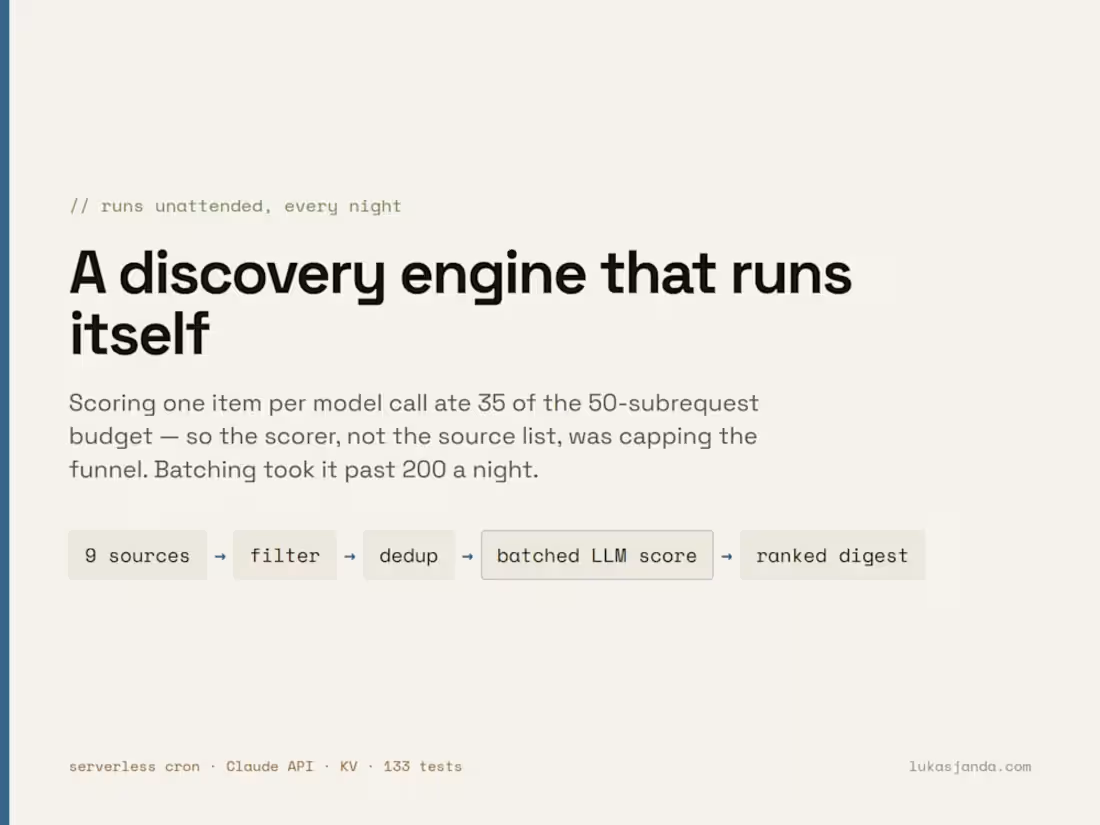
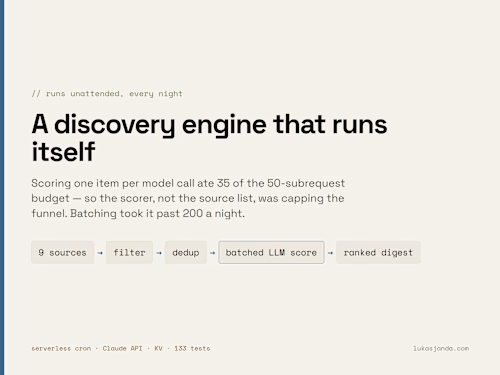
Why trust me with this. I run an LLM scoring pipeline of my own, unattended, on Cloudflare Workers in TypeScript. It taught me the failures this review looks for: a scorer that misread the same hard constraint four times with nothing erroring, so that decision moved out of the prompt and into code, with each real failure kept as a test; a source adapter that silently read half its data for six days, because the only thing reported was a total; and a per-call design that spent most of its request budget, until batching took it from 35 scored a night to over 200. The write-ups are public at lukasjanda.com/writing.
How it works. You give me read access to the pipeline code and a sample of real inputs and outputs, with personal data removed. I trace one item end to end, then work through where decisions are made, where errors are swallowed, what is measured, and what it costs. At the end there is a 60-minute walkthrough.
What it is not. A review, not a rebuild: fixes are quoted separately. Not model fine-tuning, and not infrastructure or on-call work.
FAQs
Starting at$2,800
Duration1 week
Tags
AI Engineering
TypeScript
Automation
Consultant
LLM
Code Review
Evaluation
Reliability
Service provided by
Lukas Janda Prague, Czechia
LLM Pipeline Reliability Review in 1 WeekLukas Janda
Starting at$2,800
Duration1 week
Tags
AI Engineering
TypeScript
Automation
Consultant
LLM
Code Review
Evaluation
Reliability
For teams whose LLM feature (scoring, extraction, classification, summarising) runs fine in a demo and fails quietly in production.
I read how the pipeline actually works, find the places it can go wrong without anything erroring, and hand you a prioritised list of fixes plus the tests that keep them fixed.
Why trust me with this. I run an LLM scoring pipeline of my own, unattended, on Cloudflare Workers in TypeScript. It taught me the failures this review looks for: a scorer that misread the same hard constraint four times with nothing erroring, so that decision moved out of the prompt and into code, with each real failure kept as a test; a source adapter that silently read half its data for six days, because the only thing reported was a total; and a per-call design that spent most of its request budget, until batching took it from 35 scored a night to over 200. The write-ups are public at lukasjanda.com/writing.
How it works. You give me read access to the pipeline code and a sample of real inputs and outputs, with personal data removed. I trace one item end to end, then work through where decisions are made, where errors are swallowed, what is measured, and what it costs. At the end there is a 60-minute walkthrough.
What it is not. A review, not a rebuild: fixes are quoted separately. Not model fine-tuning, and not infrastructure or on-call work.
FAQs
$2,800