Rails Production Reliability Review — Risks and Remediation PlanMahmoud Ali
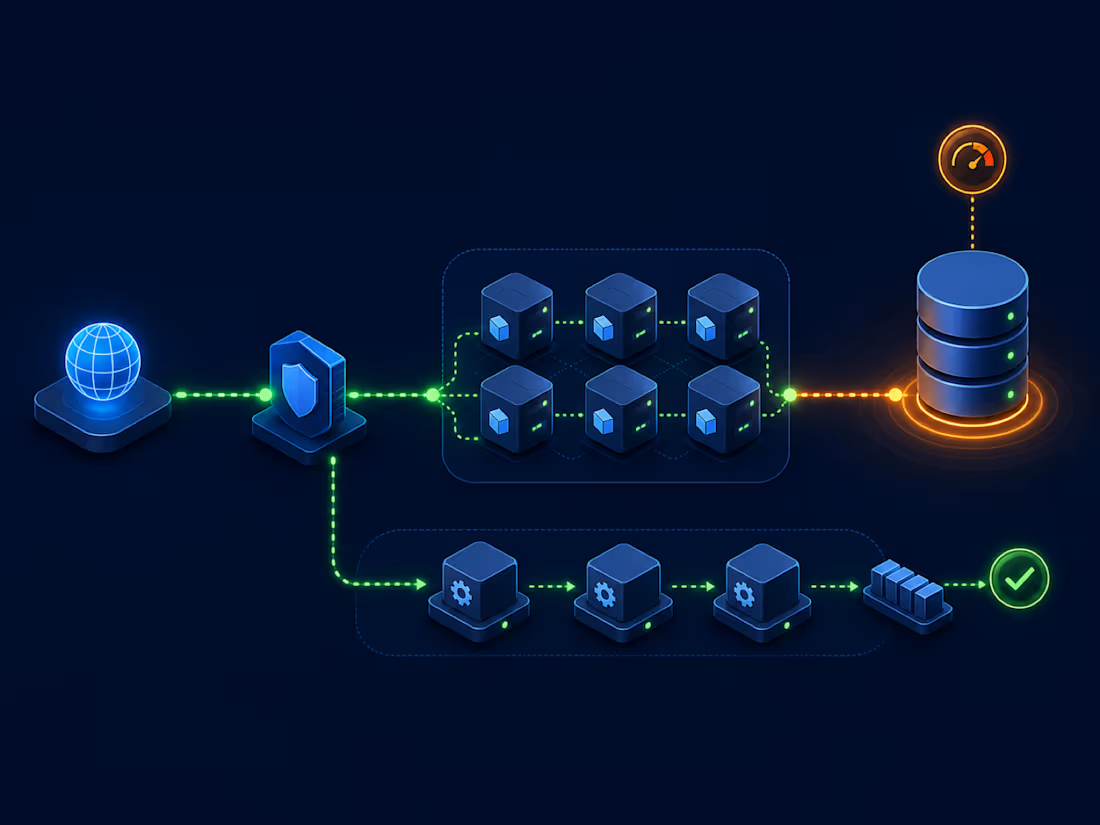
Intermittent Rails failures are difficult because the visible timeout is often not the real fault. A process can report healthy while request threads, database connections, background jobs, or an upstream dependency consume the application's usable capacity.
I will spend up to eight hours reviewing one Rails production-reliability problem or one clearly defined system boundary. You will receive:
a request-path and dependency-boundary map;
a focused review of concurrency, database pooling, layered timeouts, background work, health checks, and observable failure signals where relevant;
the top three risks ranked by evidence, likelihood, impact, and remediation cost;
the first alert or verification gap I recommend closing;
a written remediation plan and a handoff call of up to 45 minutes.
I lead hands-on Rails and PostgreSQL delivery for a production SaaS platform. In one verified incident, I traced a three-hour outage with green process health to stale PostgreSQL connections consuming request capacity, introduced bounded client-side failure detection, validated the change in staging and production, and added a dedicated 504 alert. The same monitored 504 pattern was not observed again during the following month.
FAQs
Example work
Mahmoud's other services
Starting at$450
Duration5 days
Tags
Docker
PostgreSQL
Redis

Ruby on Rails
DevOps Engineer
Software Architect
Backend Developer
Kamal
SaaS
Service provided by
Mahmoud Ali Cairo, Egypt
Rails Production Reliability Review — Risks and Remediation PlanMahmoud Ali
Starting at$450
Duration5 days
Tags
Docker
PostgreSQL
Redis
Ruby on Rails
DevOps Engineer
Software Architect
Backend Developer
Kamal
SaaS
Intermittent Rails failures are difficult because the visible timeout is often not the real fault. A process can report healthy while request threads, database connections, background jobs, or an upstream dependency consume the application's usable capacity.
I will spend up to eight hours reviewing one Rails production-reliability problem or one clearly defined system boundary. You will receive:
a request-path and dependency-boundary map;
a focused review of concurrency, database pooling, layered timeouts, background work, health checks, and observable failure signals where relevant;
the top three risks ranked by evidence, likelihood, impact, and remediation cost;
the first alert or verification gap I recommend closing;
a written remediation plan and a handoff call of up to 45 minutes.
I lead hands-on Rails and PostgreSQL delivery for a production SaaS platform. In one verified incident, I traced a three-hour outage with green process health to stale PostgreSQL connections consuming request capacity, introduced bounded client-side failure detection, validated the change in staging and production, and added a dedicated 504 alert. The same monitored 504 pattern was not observed again during the following month.
FAQs
Example work
Mahmoud's other services
$450