Python & SQL ETL Pipelines: Clean, Integrate & Automate DataSyed Waqas Ur Rehman
Most small teams don't have a data problem, they have a plumbing problem. The same CSV and Excel exports get cleaned by hand every week, numbers from two systems never match, and reports break when a column changes.
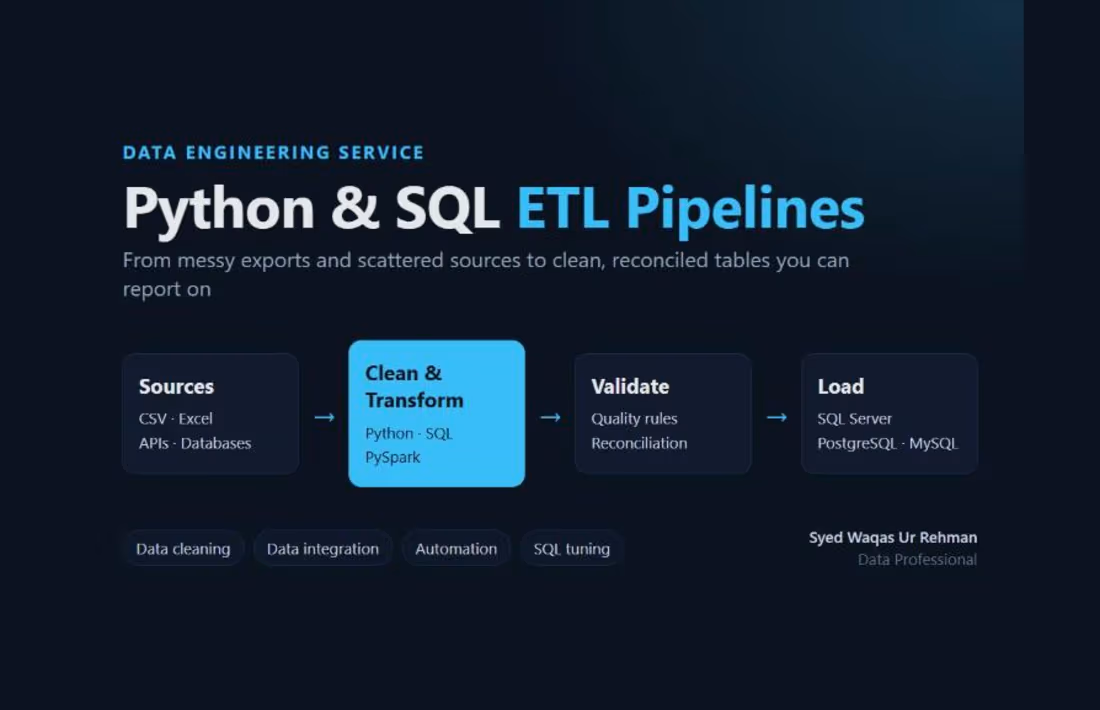
I build Python and SQL pipelines that pull your data together, clean it, check it and load it into a database you can report from. Then it runs the same way every time.
Why work with me
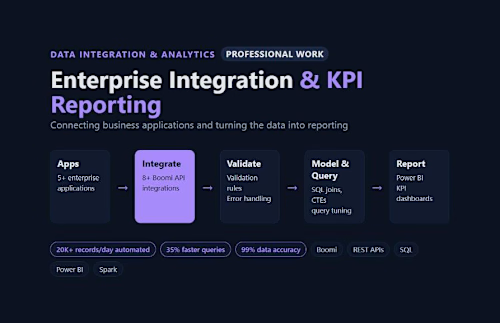
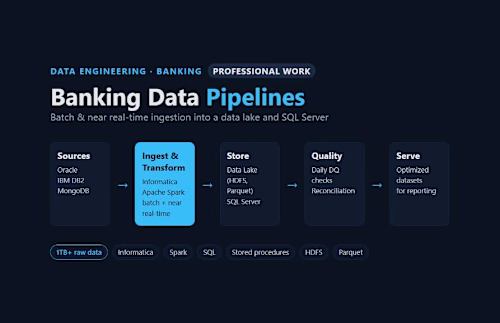
In my current role I build and run batch and near real-time pipelines for banking data, ingesting 1TB+ from Oracle, IBM DB2 and MongoDB with Informatica, Spark and SQL, with daily data quality checks and reconciliation. Before that I built 8+ API integrations between business applications and automated workflows processing 20K+ records a day. I bring the same habit to smaller projects: every row is accounted for, nothing is silently dropped.
What I can build for you
• Python ETL pipelines from CSV, Excel, JSON, APIs or databases
• Data cleaning: duplicates, date and text formats, missing values, mismatched IDs
• Loading into SQL Server, PostgreSQL or MySQL with a simple, reporting-ready schema
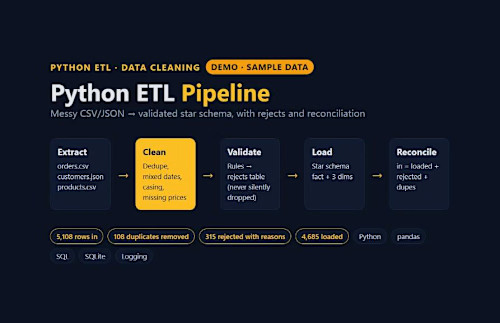
• Data quality rules plus a reconciliation check (rows in = rows loaded + rows rejected)
• Faster SQL: query tuning, views and stored procedures
• PySpark jobs when the data is too large for a single script
What you receive
• Working, tested pipeline code that you own
• Clean tables in your database, or clean output files
• A rejects file listing every row that failed a rule, and why
• A short README on how to run and change the pipeline
• A handover walkthrough (call or written)
How it works
You share sample data and tell me where it needs to end up.
I send a short plan: sources, cleaning rules, target tables and timeline. Work starts once you approve it.
I build and test on your sample and keep you updated.
You review the output and I make the agreed changes.
What I need from you
• A sample of each data source, or read access
• Where the clean data should go
• Any business rules (for example, how to treat refunds or duplicate customers)
The starting price covers one pipeline with up to 3 sources and one destination. Larger or ongoing work is quoted after I've seen your data.
Example work
Syed Waqas Ur's other services
Starting at$60
Duration1 week
Tags
Apache Spark

ETL
Informatica
Microsoft SQL Server
pandas
PostgreSQL
Python
SQL
Data Engineer
Service provided by
Syed Waqas Ur Rehman Islamabad, Pakistan
Python & SQL ETL Pipelines: Clean, Integrate & Automate DataSyed Waqas Ur Rehman
Starting at$60
Duration1 week
Tags
Apache Spark
ETL
Informatica
Microsoft SQL Server
pandas
PostgreSQL
Python
SQL
Data Engineer
Most small teams don't have a data problem, they have a plumbing problem. The same CSV and Excel exports get cleaned by hand every week, numbers from two systems never match, and reports break when a column changes.
I build Python and SQL pipelines that pull your data together, clean it, check it and load it into a database you can report from. Then it runs the same way every time.
Why work with me
In my current role I build and run batch and near real-time pipelines for banking data, ingesting 1TB+ from Oracle, IBM DB2 and MongoDB with Informatica, Spark and SQL, with daily data quality checks and reconciliation. Before that I built 8+ API integrations between business applications and automated workflows processing 20K+ records a day. I bring the same habit to smaller projects: every row is accounted for, nothing is silently dropped.
What I can build for you
• Python ETL pipelines from CSV, Excel, JSON, APIs or databases
• Data cleaning: duplicates, date and text formats, missing values, mismatched IDs
• Loading into SQL Server, PostgreSQL or MySQL with a simple, reporting-ready schema
• Data quality rules plus a reconciliation check (rows in = rows loaded + rows rejected)
• Faster SQL: query tuning, views and stored procedures
• PySpark jobs when the data is too large for a single script
What you receive
• Working, tested pipeline code that you own
• Clean tables in your database, or clean output files
• A rejects file listing every row that failed a rule, and why
• A short README on how to run and change the pipeline
• A handover walkthrough (call or written)
How it works
You share sample data and tell me where it needs to end up.
I send a short plan: sources, cleaning rules, target tables and timeline. Work starts once you approve it.
I build and test on your sample and keep you updated.
You review the output and I make the agreed changes.
What I need from you
• A sample of each data source, or read access
• Where the clean data should go
• Any business rules (for example, how to treat refunds or duplicate customers)
The starting price covers one pipeline with up to 3 sources and one destination. Larger or ongoing work is quoted after I've seen your data.
Example work
Syed Waqas Ur's other services
$60