RAG assistant over your own documentsGöksu Demirci
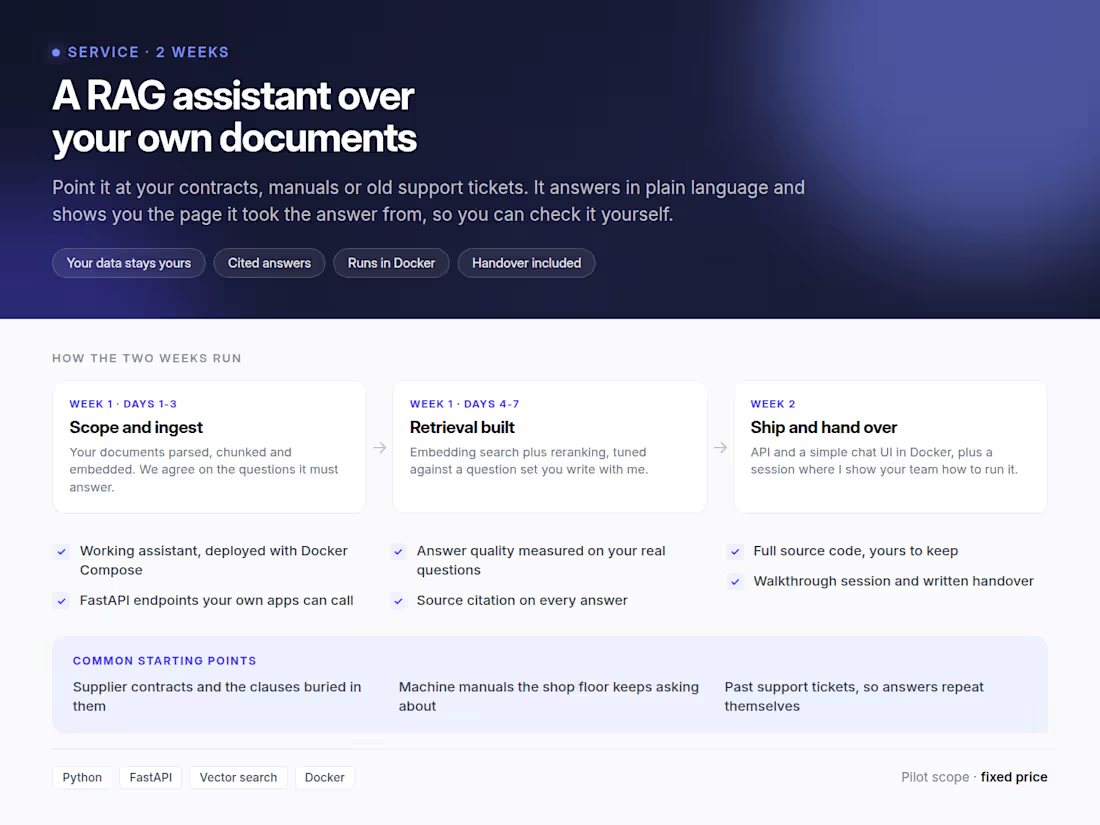
You have a folder of contracts, specs, manuals or reports, and finding anything in it takes too long. In two weeks I build a working retrieval assistant over that content and hand it to you running.
What you get: an ingestion pipeline for your real documents, including PDFs that were never meant to be parsed. A chunking and embedding strategy chosen for your content, not a default from a tutorial. Retrieval and answer generation with source citations, so you can check every response. A FastAPI service in Docker, with the code and a short handover doc.
How it works: week 1 goes to your documents and the retrieval quality. Week 2 goes to the service and handover. You get a working demo at the end of week 1, not a status update.
What this is not: this is a pilot on one document set. If it works and you want it across departments, with permissions, monitoring and scale, that is the production build and we scope it separately.

RAG assistant over your own documentsGöksu Demirci
Starting at$700
Duration2 weeks
Tags
AI Engineer
You have a folder of contracts, specs, manuals or reports, and finding anything in it takes too long. In two weeks I build a working retrieval assistant over that content and hand it to you running.
What you get: an ingestion pipeline for your real documents, including PDFs that were never meant to be parsed. A chunking and embedding strategy chosen for your content, not a default from a tutorial. Retrieval and answer generation with source citations, so you can check every response. A FastAPI service in Docker, with the code and a short handover doc.
How it works: week 1 goes to your documents and the retrieval quality. Week 2 goes to the service and handover. You get a working demo at the end of week 1, not a status update.
What this is not: this is a pilot on one document set. If it works and you want it across departments, with permissions, monitoring and scale, that is the production build and we scope it separately.
$700