Fine-tune an open LLM on your data — when retrieval isn't enoughAnsh Mangukiya
Most companies don't need a fine-tuned model; a good retrieval setup answers their questions. Fine-tuning is the right tool when you need the model to behave differently — your tone, your format, your domain's way of reasoning — or to run small and fast on hardware you own. I'll tell you honestly which case you're in before you spend anything.
What you get:
• An assessment first: your documents and goals, and a clear answer on whether fine-tuning will beat retrieval for your use case
• Synthetic training data generated from your documents with a teacher model, filtered for quality and balanced so the model doesn't learn the wrong lessons (over-refusal, memorised phrasing, template drift)
• A QLoRA adapter trained on an open model — Llama, Gemma or Qwen — on your GPUs or rented ones, with every run tracked
• A held-out evaluation set built before training, and a report comparing the fine-tuned model against the base model and against a retrieval-only baseline on your real questions
• A relevance gate in front of the model so off-topic questions never reach it
• The model served behind an API with vLLM, plus the training code, data pipeline and documentation so your team can retrain
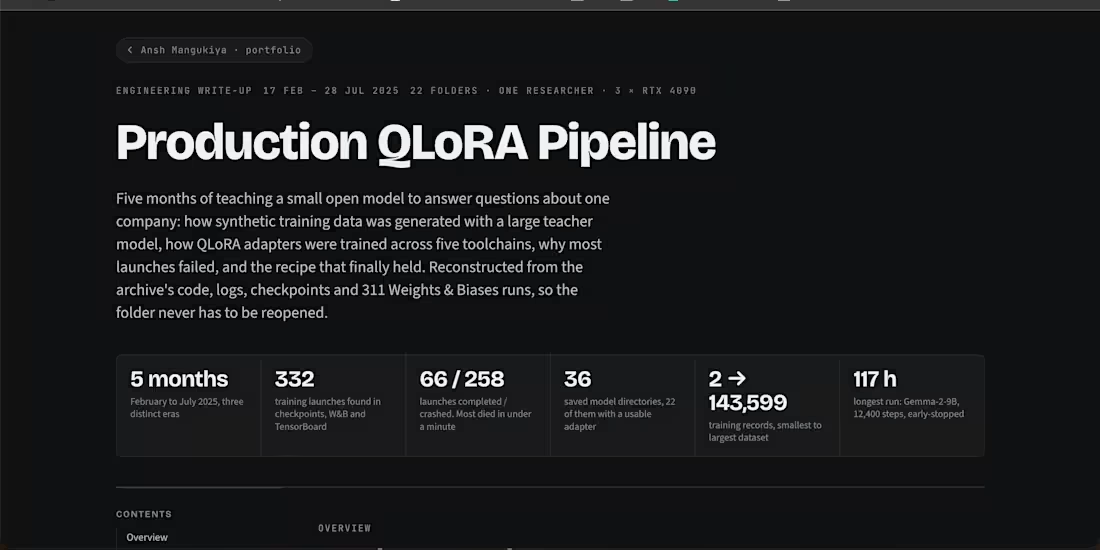
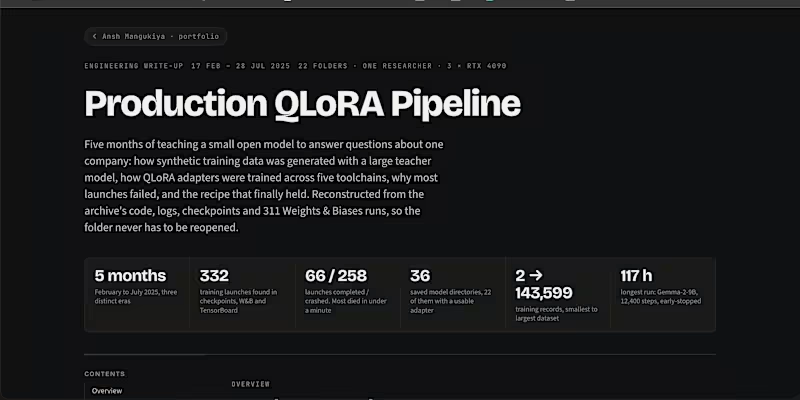
I've run 332 fine-tuning launches on consumer GPUs and documented all of them, including the failures: anshmangukiya.in/fine-tuning-field-notes. Those lessons are what you're paying for — the runs that didn't work are the reason yours will.
The starting price covers one model, one dataset from your documents, and evaluation. Multiple models, DPO or preference training, or training on sensitive data inside your own network are quoted after the assessment.
Starting at$2,250
Duration4 weeks
Tags
Machine Learning
LLM finetuning
Service provided by
Ansh Mangukiya Surat, India
- 1
- Followers
Fine-tune an open LLM on your data — when retrieval isn't enoughAnsh Mangukiya
Starting at$2,250
Duration4 weeks
Tags
Machine Learning
LLM finetuning
Most companies don't need a fine-tuned model; a good retrieval setup answers their questions. Fine-tuning is the right tool when you need the model to behave differently — your tone, your format, your domain's way of reasoning — or to run small and fast on hardware you own. I'll tell you honestly which case you're in before you spend anything.
What you get:
• An assessment first: your documents and goals, and a clear answer on whether fine-tuning will beat retrieval for your use case
• Synthetic training data generated from your documents with a teacher model, filtered for quality and balanced so the model doesn't learn the wrong lessons (over-refusal, memorised phrasing, template drift)
• A QLoRA adapter trained on an open model — Llama, Gemma or Qwen — on your GPUs or rented ones, with every run tracked
• A held-out evaluation set built before training, and a report comparing the fine-tuned model against the base model and against a retrieval-only baseline on your real questions
• A relevance gate in front of the model so off-topic questions never reach it
• The model served behind an API with vLLM, plus the training code, data pipeline and documentation so your team can retrain
I've run 332 fine-tuning launches on consumer GPUs and documented all of them, including the failures: anshmangukiya.in/fine-tuning-field-notes. Those lessons are what you're paying for — the runs that didn't work are the reason yours will.
The starting price covers one model, one dataset from your documents, and evaluation. Multiple models, DPO or preference training, or training on sensitive data inside your own network are quoted after the assessment.
$2,250