Self-hosted LLM on your own servers — private, fastAnsh Mangukiya
If your documents can't be sent to OpenAI, or your API bill has become a line item the CFO asks about, the answer is running an open-weight model on hardware you control. I set that up end to end and hand you an endpoint that works exactly like the OpenAI API, so your existing code keeps working.
What you get:
• Model selection for your workload — Llama, Qwen, Gemma, Mistral — based on quality, context length, and the GPU you have or want to rent
• Deployment with vLLM on your GPU server, VPS or cloud instance, with quantisation chosen to fit your VRAM
• An OpenAI-compatible API endpoint behind authentication, so your applications switch over with a one-line change
• Throughput tuning for your real traffic: batching, KV-cache settings and concurrency limits measured under load, not guessed from defaults
• Docker packaging, startup scripts, monitoring of GPU memory and latency, and a runbook your team can operate from
• A cost comparison: what the same monthly request volume costs on the API you use today versus on your own hardware
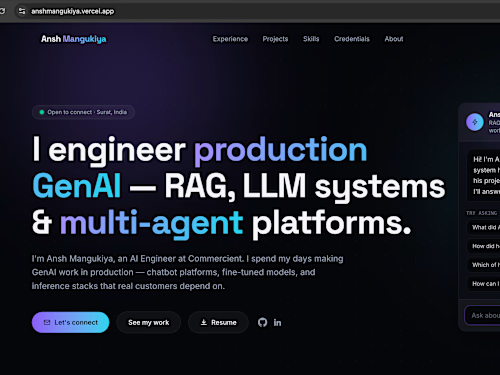
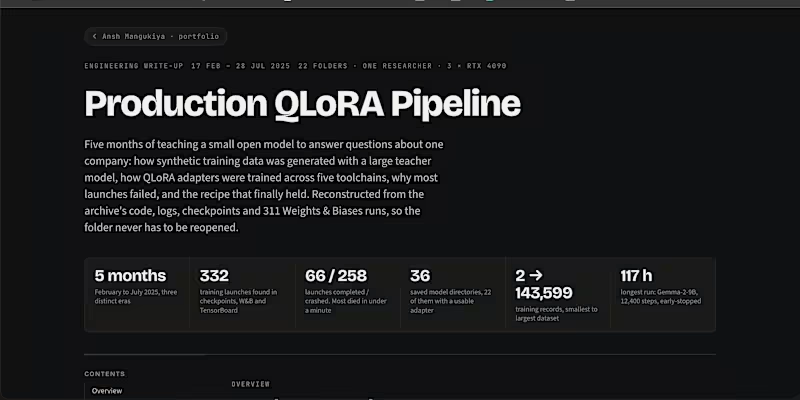
I run this in production for a US software company — a multi-GPU inference stack sustaining 150+ tokens per second under concurrent load — and I've published a write-up of what breaks on consumer GPUs and how to avoid it: anshmangukiya.in/fine-tuning-field-notes
The starting price covers one model on one server with an authenticated endpoint and load tuning. Multi-GPU, multiple models, a RAG layer on top, or an air-gapped environment are quoted after a short call.
Example work
Starting at$1,350
Duration2 weeks
Tags
DevOps Engineer
AI Developement
Service provided by
Ansh Mangukiya Surat, India
- 1
- Followers
Self-hosted LLM on your own servers — private, fastAnsh Mangukiya
Starting at$1,350
Duration2 weeks
Tags
DevOps Engineer
AI Developement
If your documents can't be sent to OpenAI, or your API bill has become a line item the CFO asks about, the answer is running an open-weight model on hardware you control. I set that up end to end and hand you an endpoint that works exactly like the OpenAI API, so your existing code keeps working.
What you get:
• Model selection for your workload — Llama, Qwen, Gemma, Mistral — based on quality, context length, and the GPU you have or want to rent
• Deployment with vLLM on your GPU server, VPS or cloud instance, with quantisation chosen to fit your VRAM
• An OpenAI-compatible API endpoint behind authentication, so your applications switch over with a one-line change
• Throughput tuning for your real traffic: batching, KV-cache settings and concurrency limits measured under load, not guessed from defaults
• Docker packaging, startup scripts, monitoring of GPU memory and latency, and a runbook your team can operate from
• A cost comparison: what the same monthly request volume costs on the API you use today versus on your own hardware
I run this in production for a US software company — a multi-GPU inference stack sustaining 150+ tokens per second under concurrent load — and I've published a write-up of what breaks on consumer GPUs and how to avoid it: anshmangukiya.in/fine-tuning-field-notes
The starting price covers one model on one server with an authenticated endpoint and load tuning. Multi-GPU, multiple models, a RAG layer on top, or an air-gapped environment are quoted after a short call.
Example work
$1,350