Production AI Agent or RAG System, with Evals Built InAbu hamza Khan
Most AI features break the week after launch. Nobody measured them, and the numbers come straight from the model.
I build AI agents and RAG systems that hold up in production:
Measured, not guessed. Every build ships with an eval set and a scorecard, so you know accuracy before your users do.
Numbers you can trust. The LLM interprets the request, and deterministic code does the math, pricing and calculations.
Safe to change. A CI gate re-runs the evals on every update, so a prompt tweak can’t quietly break things.
Shipped, not demoed. I deploy it with auth, logging and cost tracking, and hand over docs your team can maintain.
What you get: a working agent or RAG system on your data, deployed to your cloud (AWS or GCP), an eval report with accuracy and cost per request, and a 30-minute handover call.
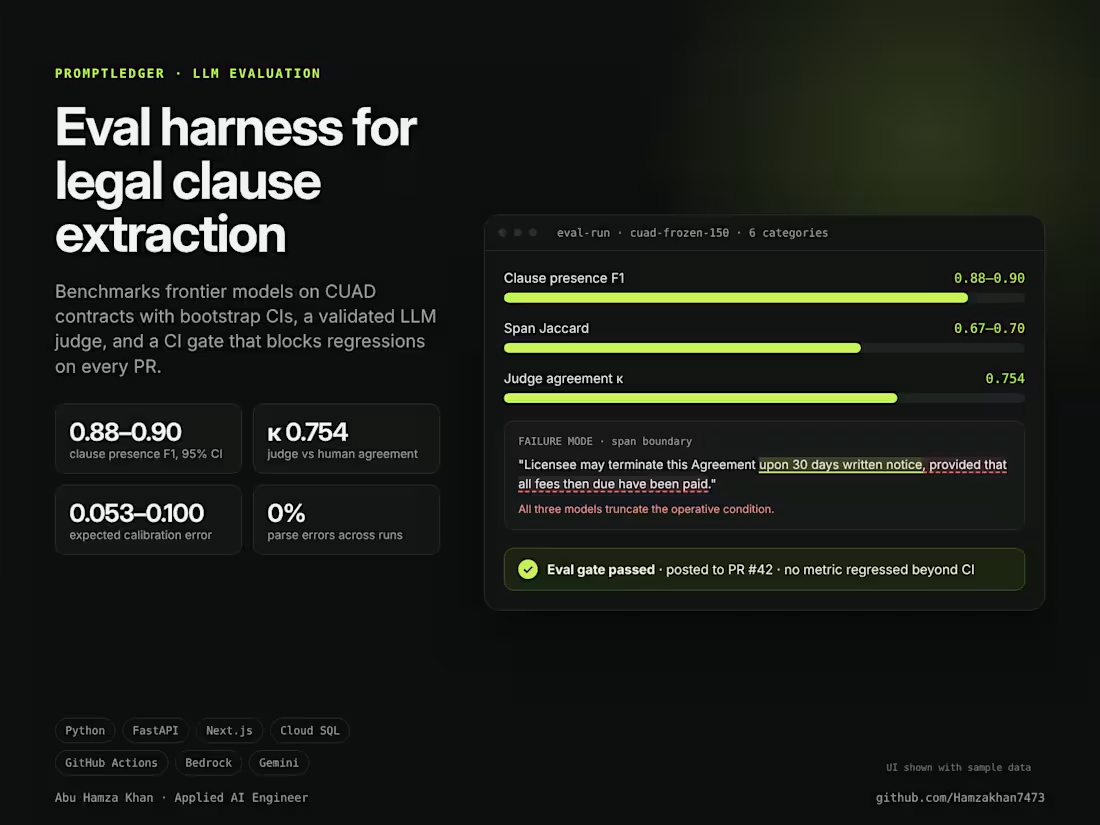
Proof: I built Taxora AI, a multi-agent tax copilot in production at 89% answer correctness on a human-reviewed eval. I also built a legal-AI eval harness that scored frontier models at 0.88–0.90 F1 with a validated LLM judge (κ 0.754).
Good fit: document extraction, internal knowledge assistants, workflow agents, and fixing an AI feature that’s unreliable today.
Abu hamza's other services
Contact for pricing
Duration1 week
Tags
AI Agents · RAG · LLM Evaluation · LangGraph · Python · FastAPI · Next.js · AI Automation · Document AI
Service provided by
Abu hamza Khan Jersey City, USA
Production AI Agent or RAG System, with Evals Built InAbu hamza Khan
Contact for pricing
Duration1 week
Tags
AI Agents · RAG · LLM Evaluation · LangGraph · Python · FastAPI · Next.js · AI Automation · Document AI
Most AI features break the week after launch. Nobody measured them, and the numbers come straight from the model.
I build AI agents and RAG systems that hold up in production:
Measured, not guessed. Every build ships with an eval set and a scorecard, so you know accuracy before your users do.
Numbers you can trust. The LLM interprets the request, and deterministic code does the math, pricing and calculations.
Safe to change. A CI gate re-runs the evals on every update, so a prompt tweak can’t quietly break things.
Shipped, not demoed. I deploy it with auth, logging and cost tracking, and hand over docs your team can maintain.
What you get: a working agent or RAG system on your data, deployed to your cloud (AWS or GCP), an eval report with accuracy and cost per request, and a 30-minute handover call.
Proof: I built Taxora AI, a multi-agent tax copilot in production at 89% answer correctness on a human-reviewed eval. I also built a legal-AI eval harness that scored frontier models at 0.88–0.90 F1 with a validated LLM judge (κ 0.754).
Good fit: document extraction, internal knowledge assistants, workflow agents, and fixing an AI feature that’s unreliable today.
Abu hamza's other services
Contact for pricing