Real-Time Object Detection, Tracking & OCR for Video & ImagesShakeel Ur Rehman
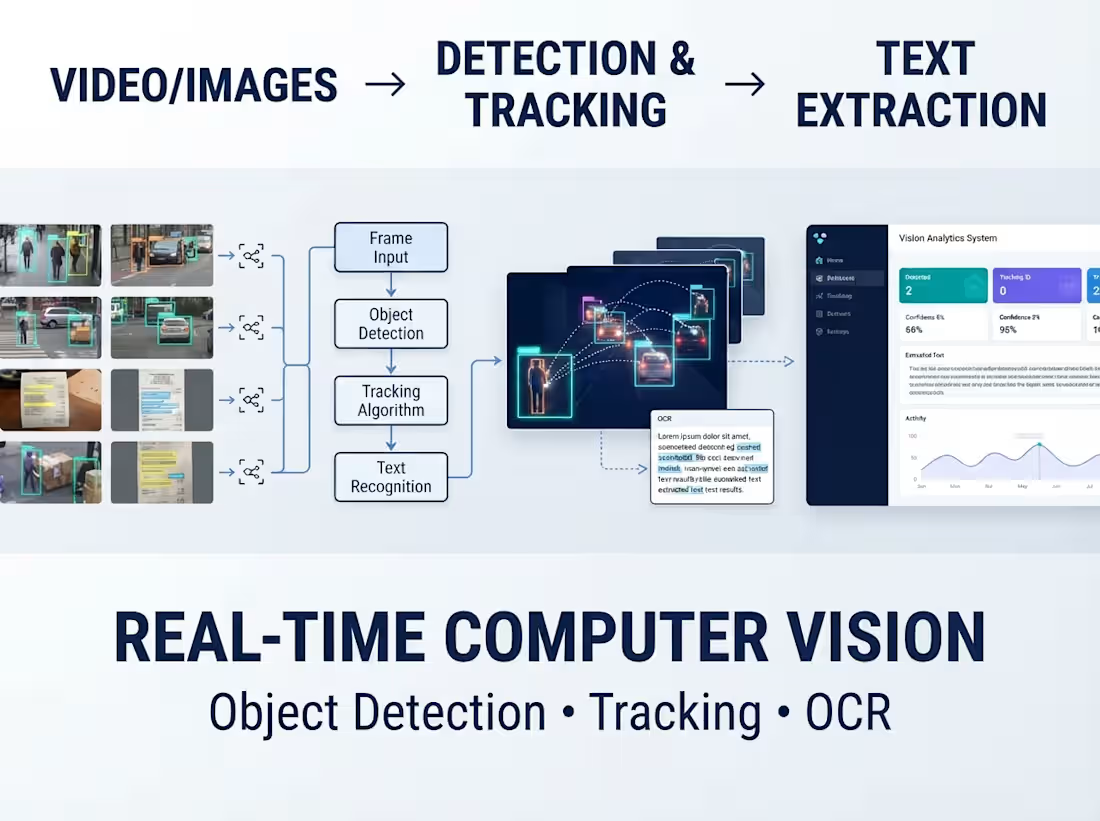
I build computer vision systems that turn raw video and images into automated, real-time decisions detecting and tracking objects across frames, and extracting text data from documents, receipts, or scanned images with high accuracy. Instead of manual monitoring or slow data entry, your system sees and reads the way a trained analyst would, continuously and at scale.
My approach starts with understanding what you need the system to detect, track, or extract, and the environment it will run in a security camera feed, a warehouse floor, a document pipeline, or a mobile app. From there, I select and train the right model for the job: YOLOv8/YOLO11 for real-time object detection, custom tracking algorithms (DeepSORT, ByteTrack) for following objects across video frames, and OCR pipelines (Tesseract, EasyOCR, or custom-trained models) for accurate text extraction from varied document formats.
For object detection and tracking, I optimize for both accuracy and inference speed, so the system performs reliably in production, whether that's live camera feeds or batch video processing. For OCR, I handle the full pipeline image preprocessing, text region detection, and post-processing to maintain accuracy even with low-quality scans, handwritten text, or complex layouts.
This service fits security and surveillance systems, retail inventory and foot-traffic analysis, warehouse and logistics automation, document digitization workflows, and any business looking to automate visual monitoring or data extraction. Every solution is delivered production-ready, with clean code, clear documentation, and support for deployment on edge devices, cloud, or existing infrastructure.
FAQs

Contact for pricing
Duration1 week
Tags
OCR
Python
Deep Learning
Image Processing
computer vision developer
Object Detection
Object Tracking
Video Analytics
YOLO
Service provided by
Shakeel Ur Rehman Faisalabad, Pakistan
Real-Time Object Detection, Tracking & OCR for Video & ImagesShakeel Ur Rehman
Contact for pricing
Duration1 week
Tags
OCR
Python
Deep Learning
Image Processing
computer vision developer
Object Detection
Object Tracking
Video Analytics
YOLO
I build computer vision systems that turn raw video and images into automated, real-time decisions detecting and tracking objects across frames, and extracting text data from documents, receipts, or scanned images with high accuracy. Instead of manual monitoring or slow data entry, your system sees and reads the way a trained analyst would, continuously and at scale.
My approach starts with understanding what you need the system to detect, track, or extract, and the environment it will run in a security camera feed, a warehouse floor, a document pipeline, or a mobile app. From there, I select and train the right model for the job: YOLOv8/YOLO11 for real-time object detection, custom tracking algorithms (DeepSORT, ByteTrack) for following objects across video frames, and OCR pipelines (Tesseract, EasyOCR, or custom-trained models) for accurate text extraction from varied document formats.
For object detection and tracking, I optimize for both accuracy and inference speed, so the system performs reliably in production, whether that's live camera feeds or batch video processing. For OCR, I handle the full pipeline image preprocessing, text region detection, and post-processing to maintain accuracy even with low-quality scans, handwritten text, or complex layouts.
This service fits security and surveillance systems, retail inventory and foot-traffic analysis, warehouse and logistics automation, document digitization workflows, and any business looking to automate visual monitoring or data extraction. Every solution is delivered production-ready, with clean code, clear documentation, and support for deployment on edge devices, cloud, or existing infrastructure.
FAQs
Contact for pricing