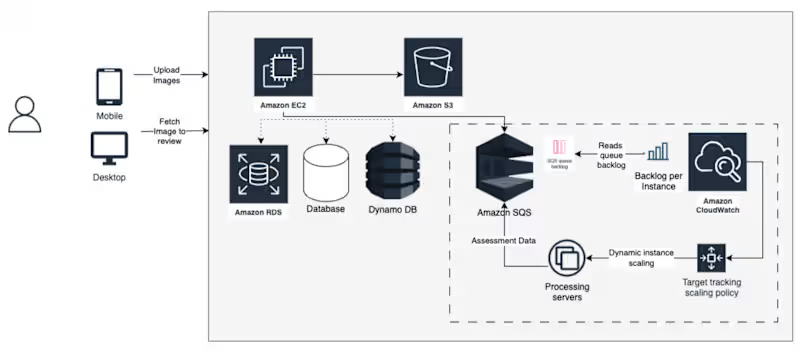
Cold start: 17 min → under 3 min. Shard loading: 16 min → 50 sec. Serving cost: ~1/6 of a managed SageMaker equivalent.
Performance-engineered a LLaVA vision-language deployment on AWS as part of a specialised strike team, with the full write-up published on LinkedIn (linked under Completed Work).
Reduced end-to-end cold start from ~17 minutes to under 3 (66%) via custom Deep Learning AMIs (−32% immediately), ephemeral-storage model caching with parallel aria2c downloads (checkpoint loading 16 min → 50 sec), and 4-bit NF4 quantization (shard loading 41s → 18s). Along the way, diagnosed a storage-path bug where checkpoint shards kept re-downloading despite being baked into the AMI.
0
50


We have been working with Startups and Enterprises as their MVP god and Customer reliant business integrations for a while. We are now open to Engagements such as this to drive your business forward.
We also have an AI Video Intelligence Product, VidForgeX, looking to rollout in the coming weeks. Exciting days ahead!!
As we are looking at the product release, we are also looking at Customer Engagements to contribute as Design and Engineering Partner
Send your consultation at https://www.raynxai.com/consultation
0
64

Designed and implemented a cloud-native API platform with automated CI/CD, security controls, and observability built in. The platform streamlined software delivery, improved developer productivity, and established consistent engineering standards. Teams were able to release features faster while maintaining high reliability and quality.
These descriptions are written in the style that typically performs well on Contra and consulting portfolios because they focus on business outcomes, scale, and impact, not just technologies.
0
49