The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

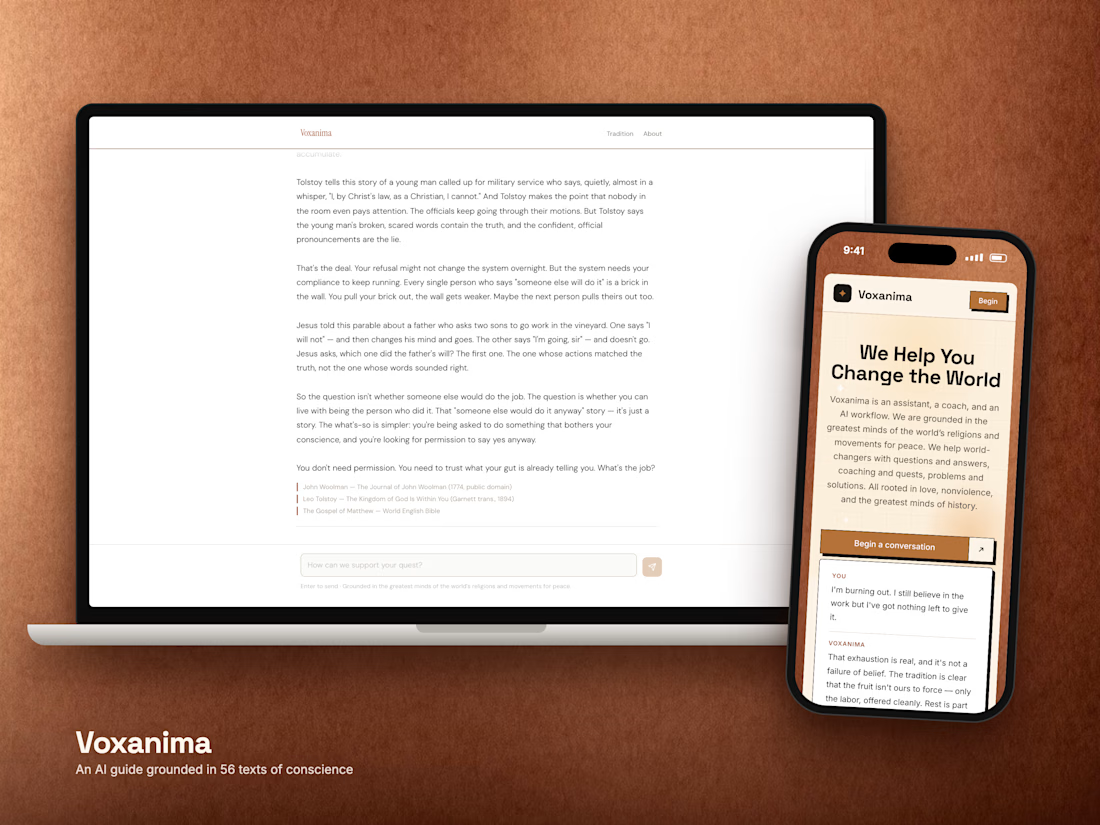
An AI guide grounded in 56 texts of conscience. It quotes only what it finds, shows only the sources it used, and finds the right one 94% of the time.
The brief
VoxAnima is a conversational guide for people facing a moral choice at work: the moment you see something wrong and have to decide whether to keep going. It speaks in the voice of its founder, an activist and author with 35 years in the work. It draws on a fixed library of nonviolence and wisdom literature: Gandhi, the Gospels, the Hebrew Bible, the Qur'an, the Dhammapada, Tolstoy, the Quakers, the Stoics and more.
One rule mattered more than anything else. Every claim had to come from a passage the system actually found, and the source line under each answer had to be true.
What I built
A searchable library of 56 texts, split into 1,600+ passages, stored in Postgres with pgvector and searched by meaning on every question.
Chunking that respects the texts. Scripture is split by whole verses, so no passage cuts a verse in half or crosses a chapter. Each passage carries its own reference, like Isaiah 58:1-14, so the answer can say exactly where a line came from.
A search cutoff measured, not guessed. The original spec's threshold was tuned for a different embedding model and returned nothing. I measured the real score range and set the cutoff from the data.
A balance rule. Scripture is about 60% of the library, so it used to crowd out every other voice. Each answer now takes at most 2 passages from any one source, which leaves room for Woolman, Tolstoy or the Buddha to speak.
Sources you can trust. The model numbers each passage it uses. The app shows a source line only for passages the answer actually drew on. A passage that was found but not used gets no byline.
A test set for search. 34 real questions with known answers, run before and after every change. The right source lands in the top 5 for 94% of them.
Fail loudly, never silently. When the database went down in production, the app had kept answering with no sources and nobody could tell. I made failures visible, added a daily health check, and the test suite now refuses to pass against a dead backend.
Results
94% of test questions find the right source in the top 5 (MRR 0.78)
Only cited passages get a byline: in the cover's live example, 5 passages were found, 3 were used, and 2 got no byline
The founder's voice comes from his own recorded answers, held as a reference set the model writes against
Stack
Next.js · Supabase (Postgres + pgvector) · Voyage embeddings · Claude via the Vercel AI SDK · Vercel




Splitting by whole verses is the right call. In a document assistant I built, quotes cut mid-word failed their own verification, so chunk and quote boundaries matter more than people expect. One check that helped: before showing an answer, confirm each quote really appears in...
The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started






Related posts


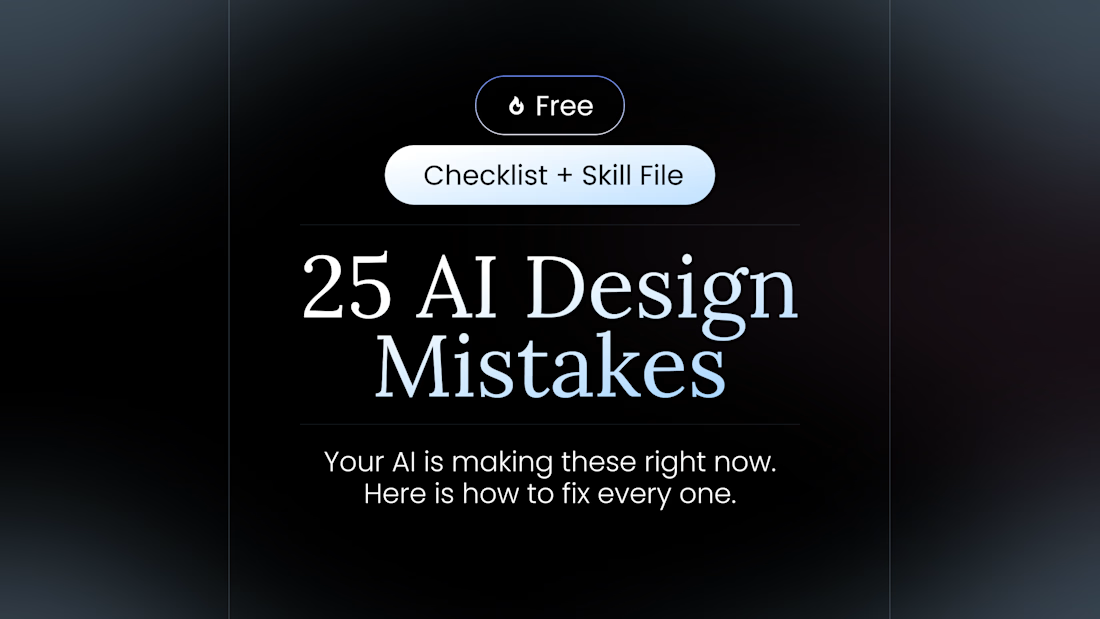
100+ people already use my free skill file to stop their AI from making the same 25 design mistakes.
Drop it into your project and your agent gets better at typography, spacing, color, and dark mode. Link in the comments.

Landing page for an AI-native terminal platform

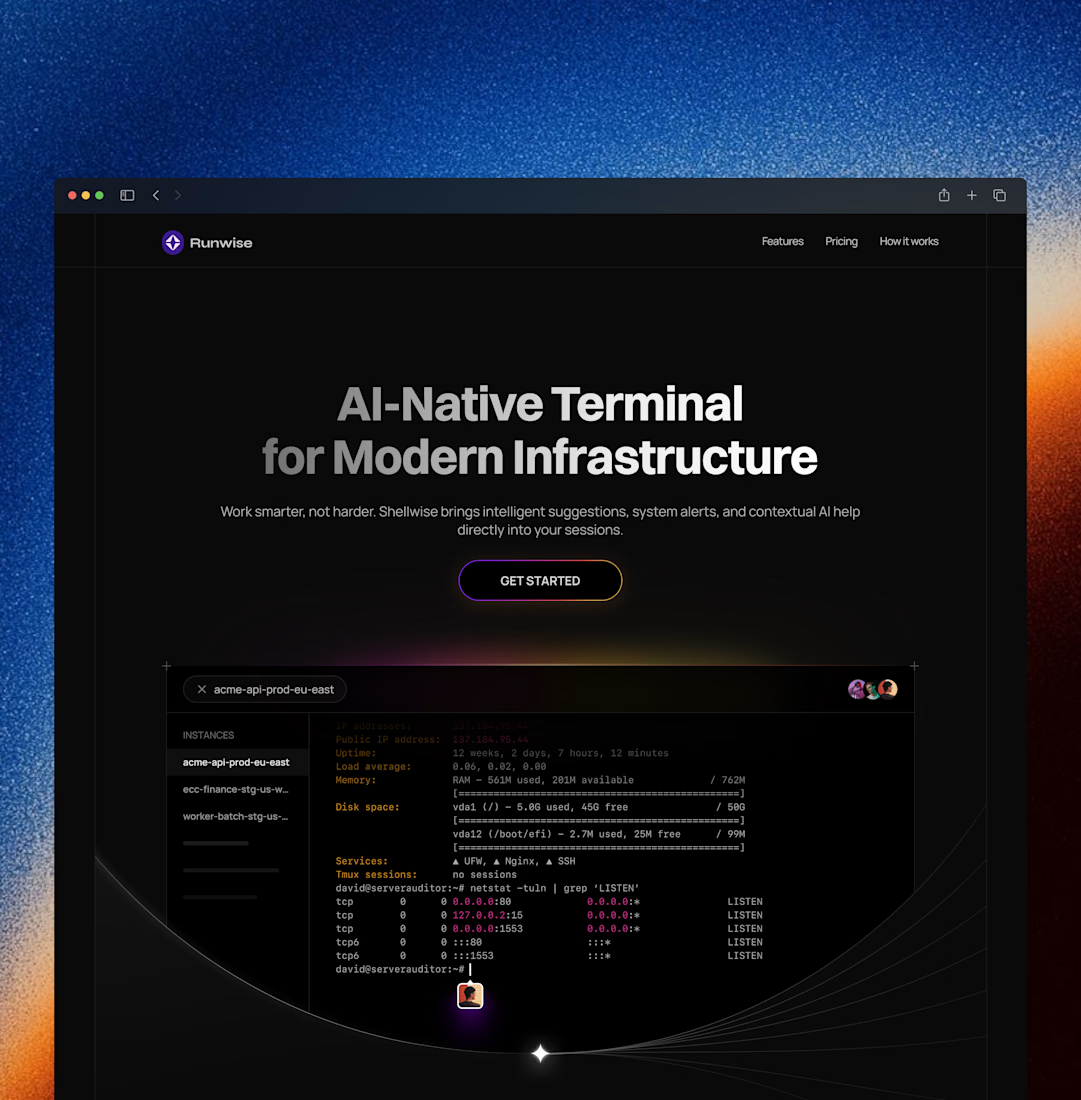
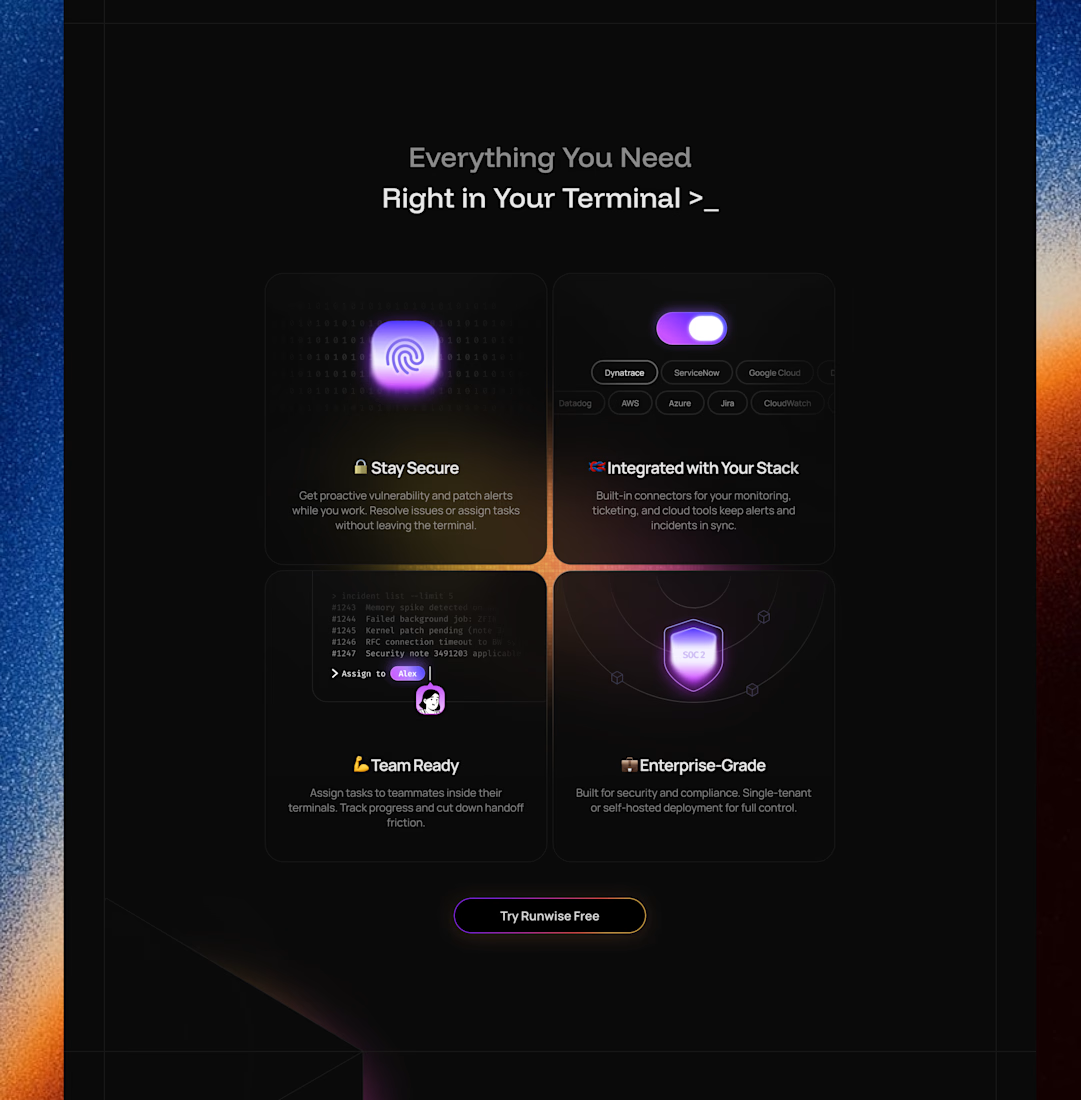
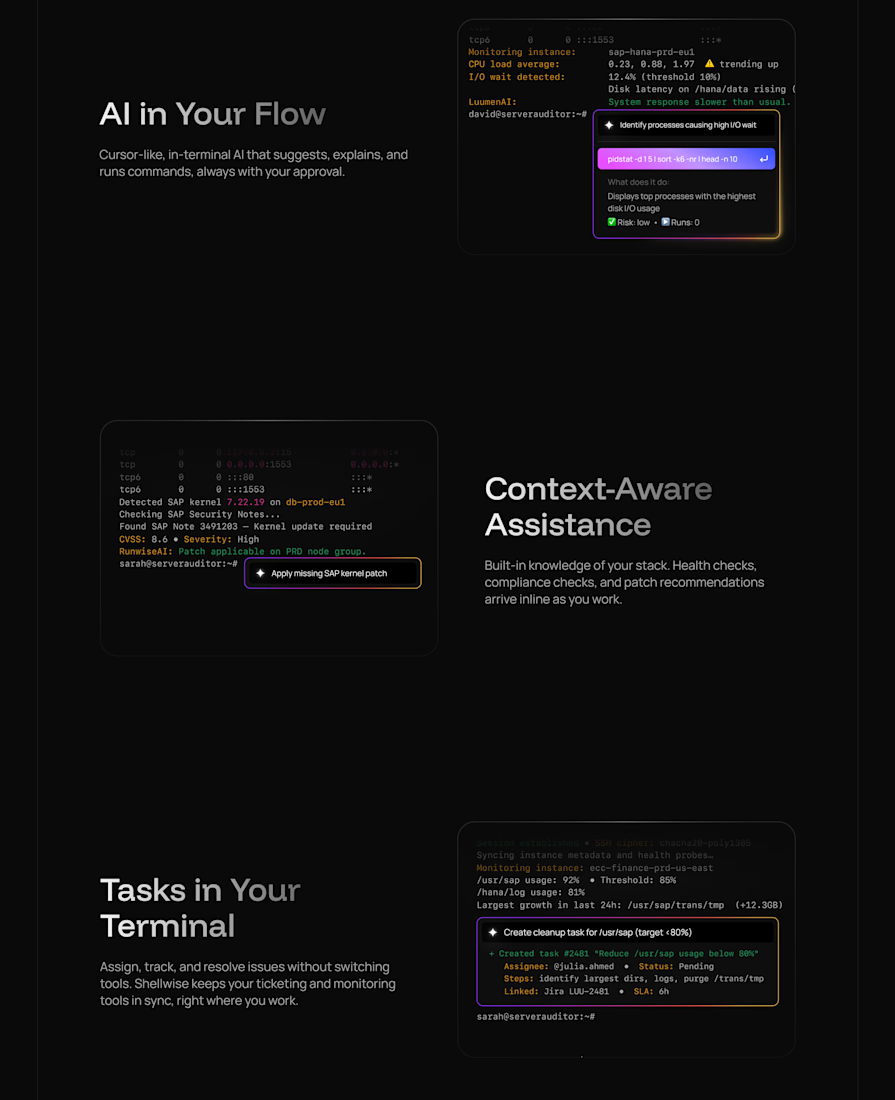

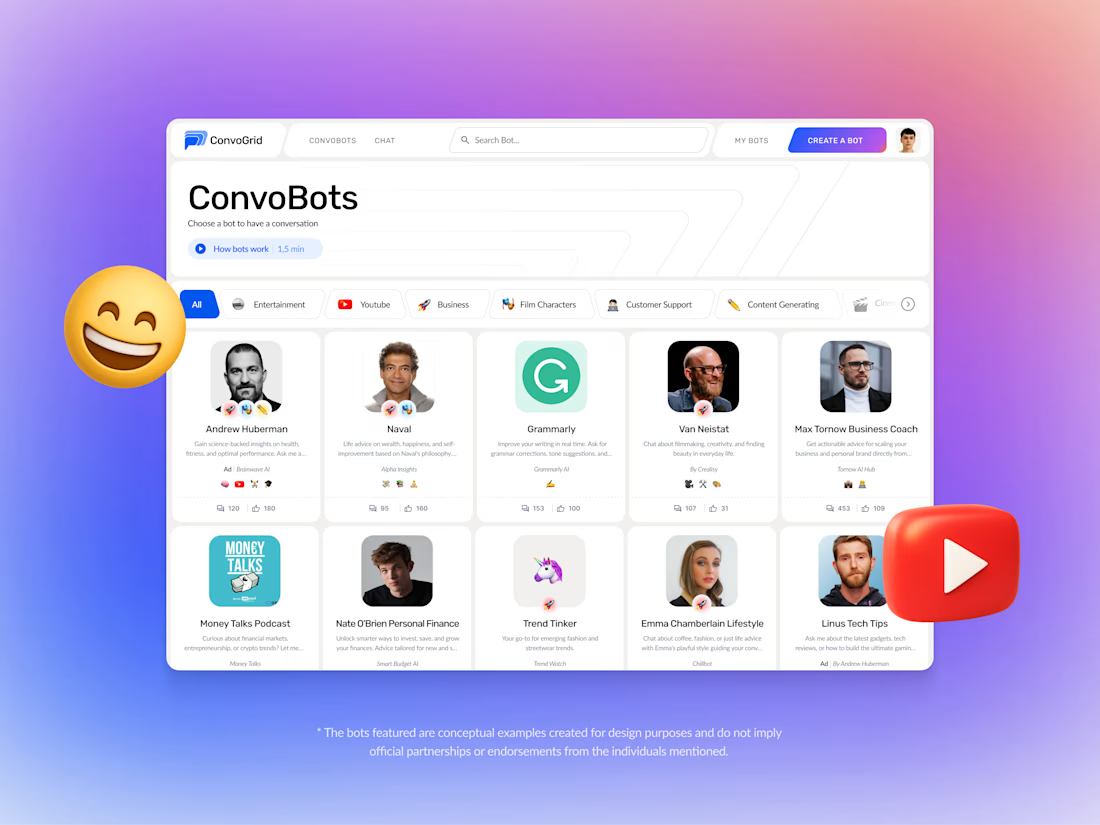
🚀 Introducing Convogrid — a new project in my portfolio.
Convogrid is a platform designed to make conversations and collaboration more structured and intuitive.
For this project, I worked through the design process from understanding the product and its core user needs to mapping user flows, exploring concepts, and crafting the final UI.
My focus was on simplifying complex interactions, creating a clear information hierarchy, and building a consistent interface that makes the overall experience easier to navigate.
Excited to share more projects and the thinking behind the design process!