The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

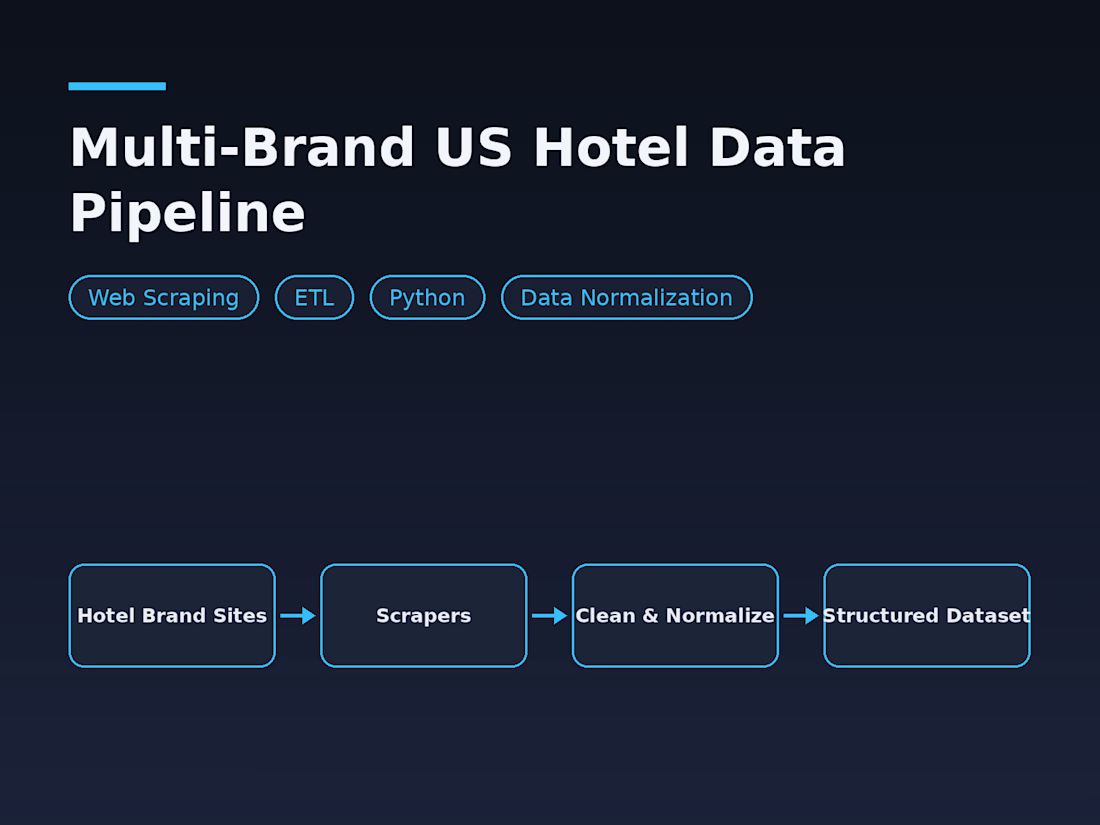
Built a data pipeline that tracks 2.4M+ hotel records across major US brands without duplicate rows or silent failures.
The problem: each brand exposes availability, rates, and property details differently, and pages change or rate-limit mid-run. A naive scraper either misses data silently or pollutes the database with duplicates when a failed run retries.
What I built:
• Scheduled collectors across multiple US hotel brands with per-host rate limits and proxy rotation
• Cross-brand entity resolution to match and deduplicate properties across sources
• Staging and completeness checks so partial runs never overwrite good data
• Idempotent upserts keyed on property and snapshot date so retries never duplicate rows
• Automated alerts when a source changes layout or field null rates spike
Result: 2.4M+ clean, structured records kept fresh on schedule.
Stack: Python, PostgreSQL, AWS S3, automated scheduling
If you're pulling data from sources that keep breaking or drifting, happy to take a look at your pipeline.
#DataEngineering #WebScraping #Python #Automation


The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started



Related posts

End-to-end retail analytics pipeline that turns raw, messy CSV exports into business decisions, built in Python and SQL and runnable with one command.
What it does:
Cleans and validates 6 relational tables, fixes 585 data-quality issues and logs every action
Loads a SQLite warehouse with keys, constraints and window-function SQL
Customer analytics: RFM segmentation, cohort retention, CAC / LTV by channel, product Pareto, market-basket analysis
Churn prediction model validated on future data (ROC-AUC 0.71, no data leakage)
6-month revenue forecast, best of 3 models by backtest (4.2% MAPE)
Auto-generated Excel report (live formulas, native charts) and an interactive Streamlit dashboard
18 automated tests




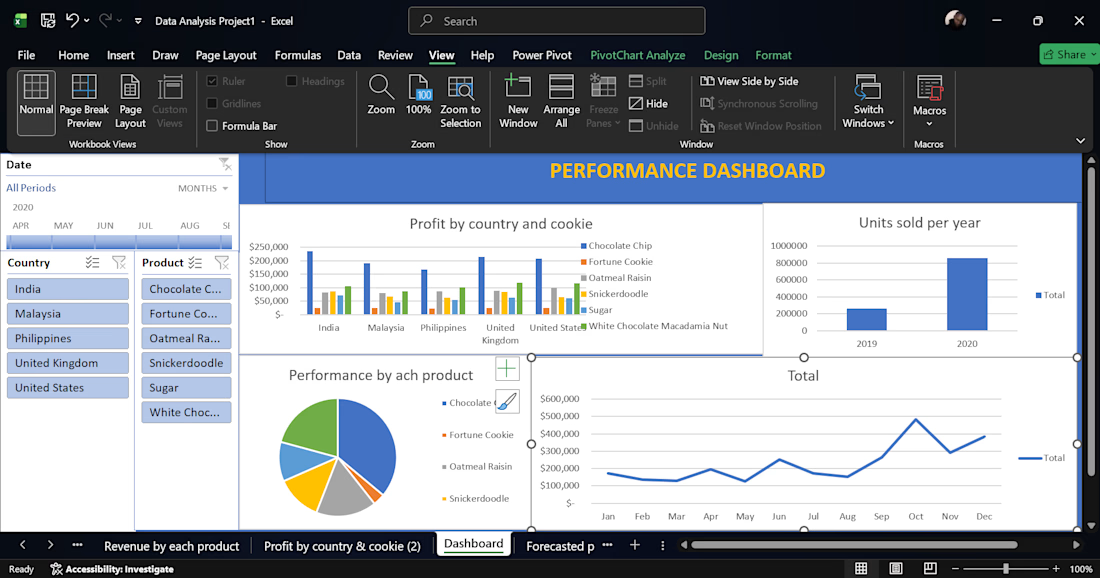
Hello Contra community! 👋
I'm Emmanuel, an aspiring Data Analyst passionate about turning raw data into meaningful insights.
I'm currently building my skills in:
Excel and Power BI for data visualization and reporting.
SQL for data querying and analysis.
Python (Pandas, Matplotlib and Scikit-learn) for data cleaning, analysis and machine learning.
I'm using practical projects to strengthen my skills and explore how data can help businesses make better decisions.
Looking forward to connecting, learning and collaborating with other professionals here!



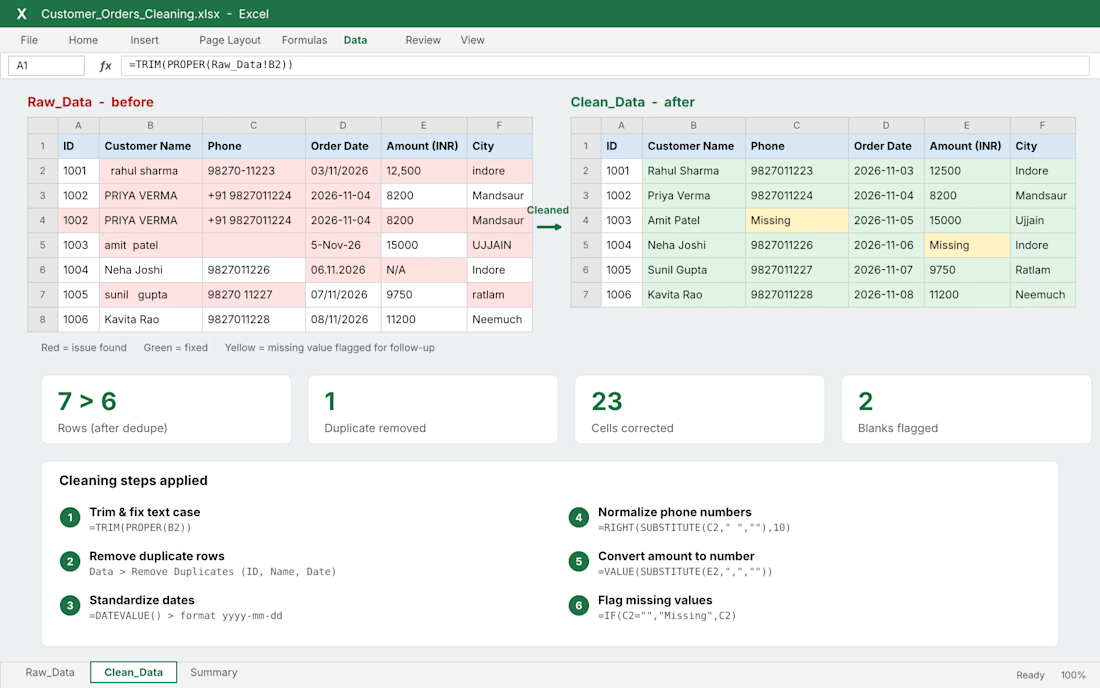
I took a raw customer orders sheet with extra spaces, mixed text cases, duplicate rows, five different date formats and inconsistent phone numbers. I cleaned it into a consistent table and flagged the missing values for follow-up instead of guessing. I used trim, proper, datevalue, substitute and Remove Duplicates.
#Excel #MicrosoftExcel #DataAnalysis #DataAnalytics #Spreadsheets #ExcelExpert #Freelance#DataCleaning #DataCleansing #DataPreparation #ExcelTips #DataQuality