The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

AI video generator service


The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started






Related posts

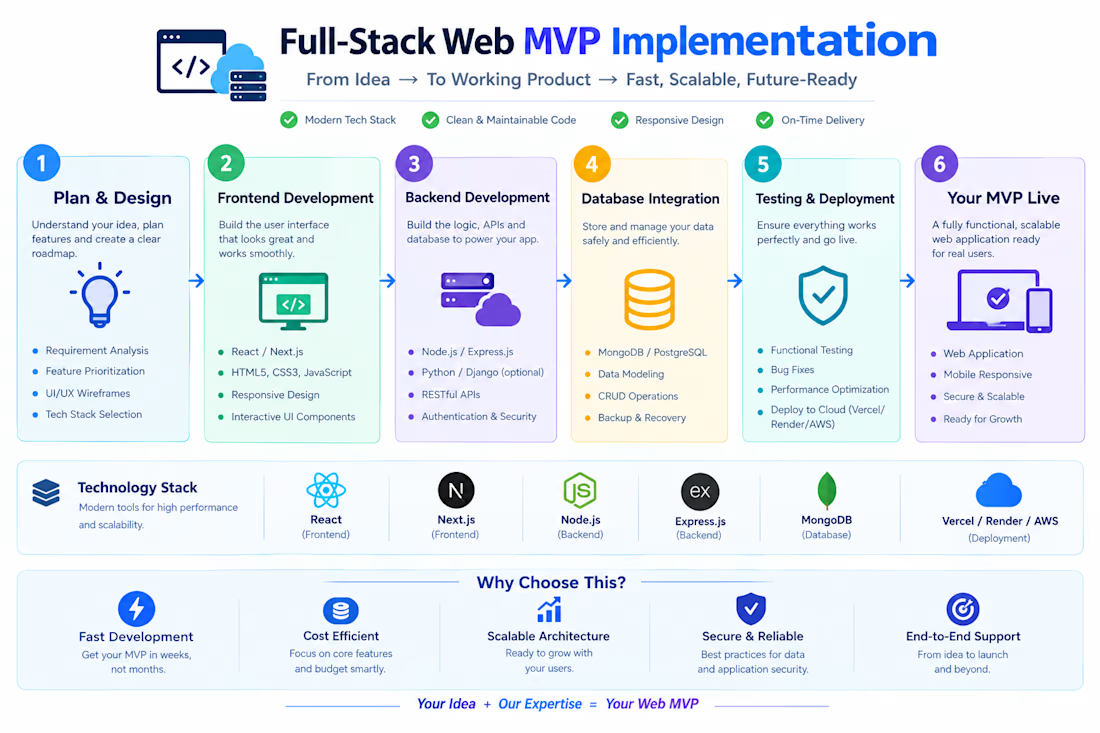
Built a highly responsive web application prototype focusing on smooth user interfaces and swift database connectivity. Optimized web performance to ensure rapid load times and cross-platform compatibility.



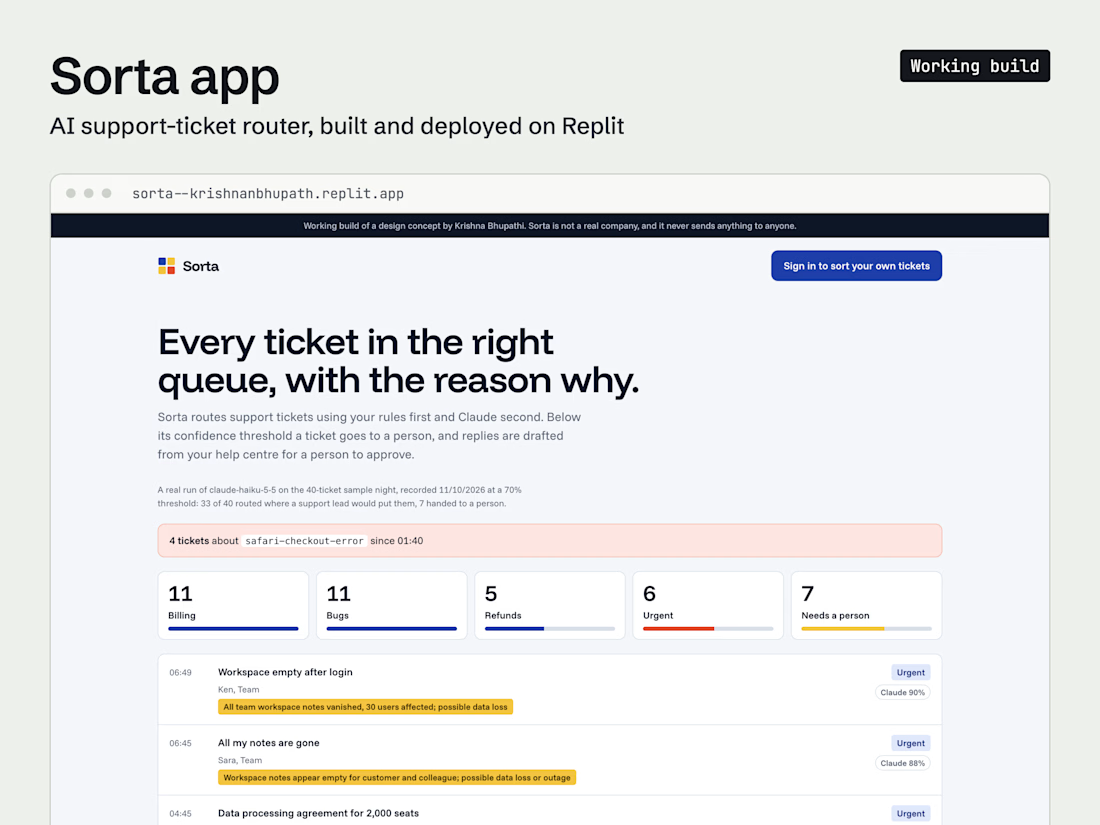
I built an AI support-ticket router on Replit, then tested it against the real model. Three things broke that no mock would have caught.
A silent failure. The first run sent 33 of 40 tickets to "needs a person". The newer Claude model rejects the temperature setting, and my code swallowed the error, so every call quietly failed. Now every failed call is logged.
The model thinks before it answers. With a tight token limit, some tickets got no answer at all and some draft replies stopped mid-sentence. Both have room now, and a cut-off draft is never saved.
One incident looked like four bugs. Four Safari checkout failures each got a different issue key, so the "3+ tickets, same problem" alert never fired. Sorting tickets in arrival order and asking for keys that name the problem rather than the customer turned them into one flagged incident.
If you're adding an LLM feature to your product, test it on real inputs early. The failures are rarely where you expect.
Live demo: https://sorta--krishnanbhupath.replit.app



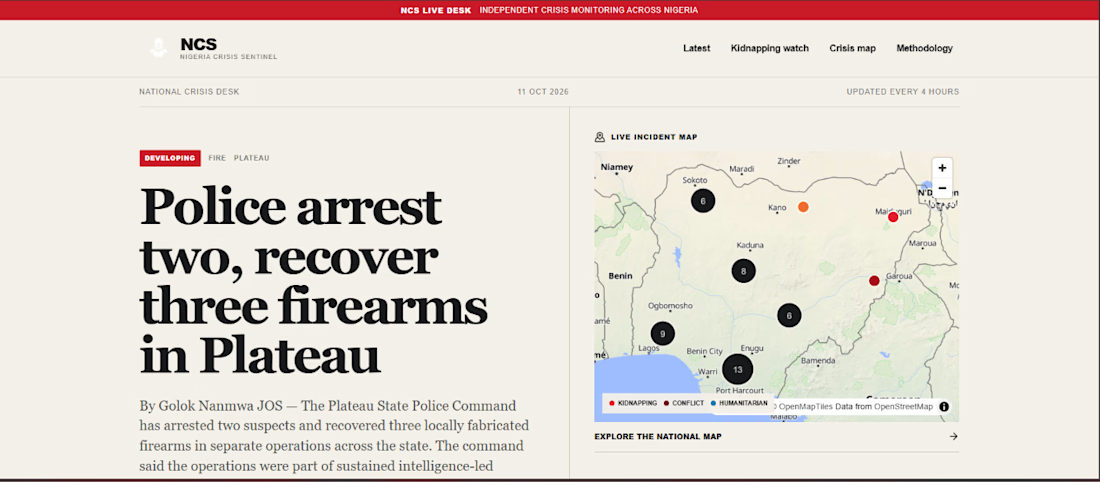
Automated pipeline that monitors news feeds every 4 hours, extracts location, category and impact, clusters reports into incidents with confidence scoring, and shows them on a live map.