The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

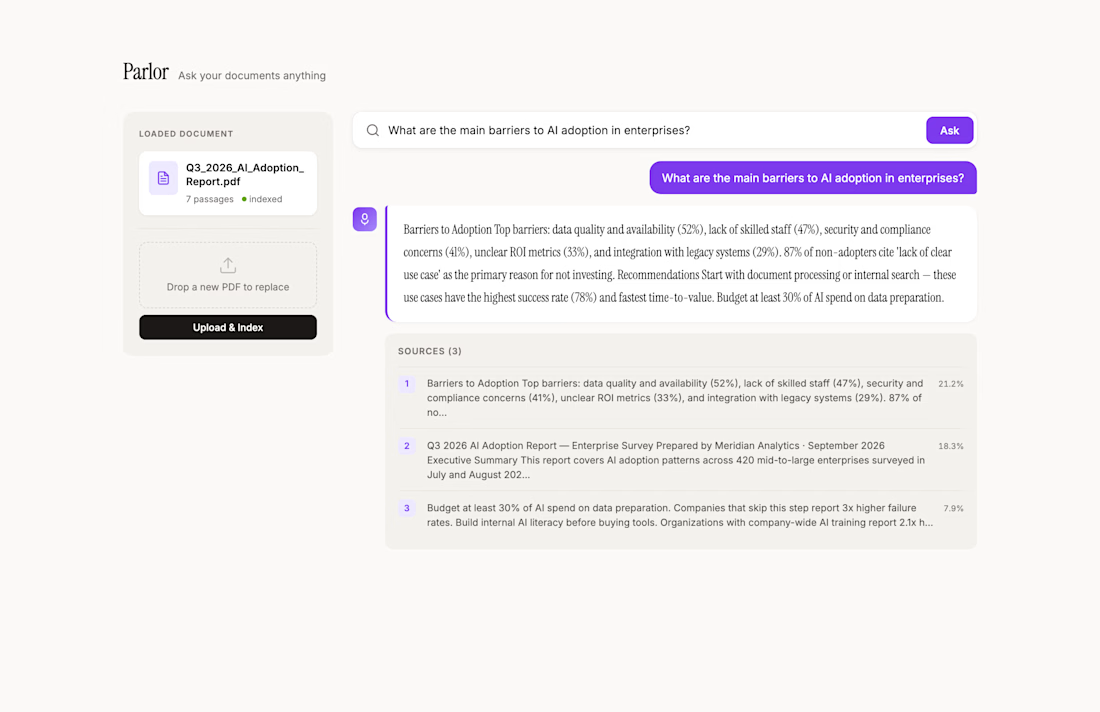
Document Q&A system that turns PDFs into searchable knowledge bases. Upload a report, ask a question in plain English, get an answer with numbered source citations and relevance scores. The retrieval layer chunks documents into overlapping passages (600 chars with 100-char overlap to avoid splitting context at boundaries), builds a TF-IDF vector index, and ranks results by cosine similarity. The answer is extracted from the highest-scoring passage with cross-reference to the original text. Built the conversational web UI with a chat-style interface. Python + FastAPI backend, scikit-learn for vectorization, PyPDF for text extraction.


The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started





Related posts


Top-notch design.

Building AI agents is easy. Building one you can trust with a real business workflow is harder.
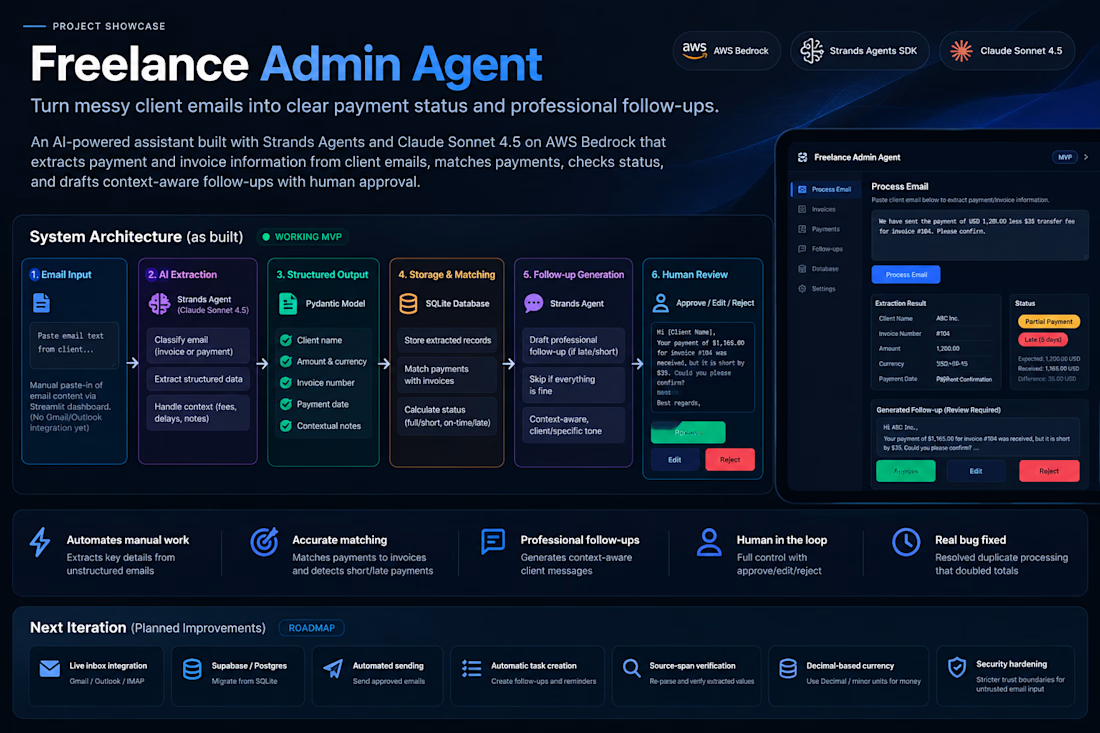
I built a Freelance Admin Agent to explore that problem using Strands Agents SDK and Claude Sonnet 4.5 on Amazon Bedrock.
The working MVP takes manually provided client emails and turns them into a structured payment workflow:
→ Classifies invoice and payment emails
→ Extracts client, invoice, amount, currency, dates and contextual details using structured output
→ Stores and matches records in SQLite
→ Uses deterministic logic to identify full/short and on-time/late payments
→ Uses a second agent to draft a contextual follow-up only when needed
→ Keeps the final decision with the human through Approve / Edit / Reject
One of the most valuable parts wasn't adding another AI feature. It was finding a real reliability issue during testing: reprocessing the same email could duplicate records and inflate payment totals.
I reproduced it through repeat testing, traced the database behavior, and fixed it.
That reinforced something I'm increasingly applying to my AI engineering work:
A useful AI product isn't just an LLM call. It needs clear boundaries between AI reasoning, structured data, deterministic business logic, persistence, testing, and human control.
The next iteration will focus on stronger production safeguards, including source-grounded financial extraction, precise currency handling, stricter trust boundaries for untrusted input, and eventually live inbox integrations.
I'm interested in building more systems like this for startups and teams with repetitive workflows that can genuinely benefit from AI agents and automation.
Stack: Python · Strands Agents SDK · Amazon Bedrock · Claude Sonnet 4.5 · Pydantic · SQLite · Streamlit

turning client emails into admin tasks is such a real freelancer pain, nice build 🔥

Challenge Submission – Lovable Challenge
Business Name: Clemxy Dentistory Genius
Business Type: Premium Dental Clinic
Location: Banana Island, Lagos, Nigeria
Business Quirks:
Solo dentist managing a busy practice
Limited administrative support
High volume of appointment inquiries
Frequent patient no-shows
Significant time spent on scheduling, reminders, and follow-ups
Problem Solved (One Line):
I built an AI-powered appointment concierge that automatically converts patient inquiries into confirmed bookings while eliminating the clinic's manual scheduling, reminder, and follow-up workload.
Project Built With Lovable:
https://pixel-perfect-display-2164.lovable.app/
Demo Video:
Attached – Patient journey walkthrough from inquiry to confirmed booking.
Build Process Video:
Attached – Behind-the-scenes walkthrough showing how the solution was designed and built in Lovable.
LinkedIn Post:
https://lnkd.in/p/etn23YDu
Solution Highlights
AI Receptionist
Real-time appointment booking
Automated confirmations
WhatsApp, SMS, and Email reminders
Self-service rescheduling
Lead recovery automation
Clinic performance dashboard
No-show reduction workflow
Built entirely in Lovable to demonstrate how AI can automate appointment-based businesses and help owners spend less time on administration and more time serving customers.
@Lovable #lovablechallenge #AI #Automation #HealthcareTech #DentalTech #NoCode #VibeCoding #BusinessAutomation #BuildInPublic #ClemxyTech