The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost


I am curious about how many people use Claude Code, Cursor, or Codex to complete client work. I have received a small number of such projects and would welcome further insights. Might I begin accepting assignments from this source as well?
The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started

Challenges
View all


Related posts

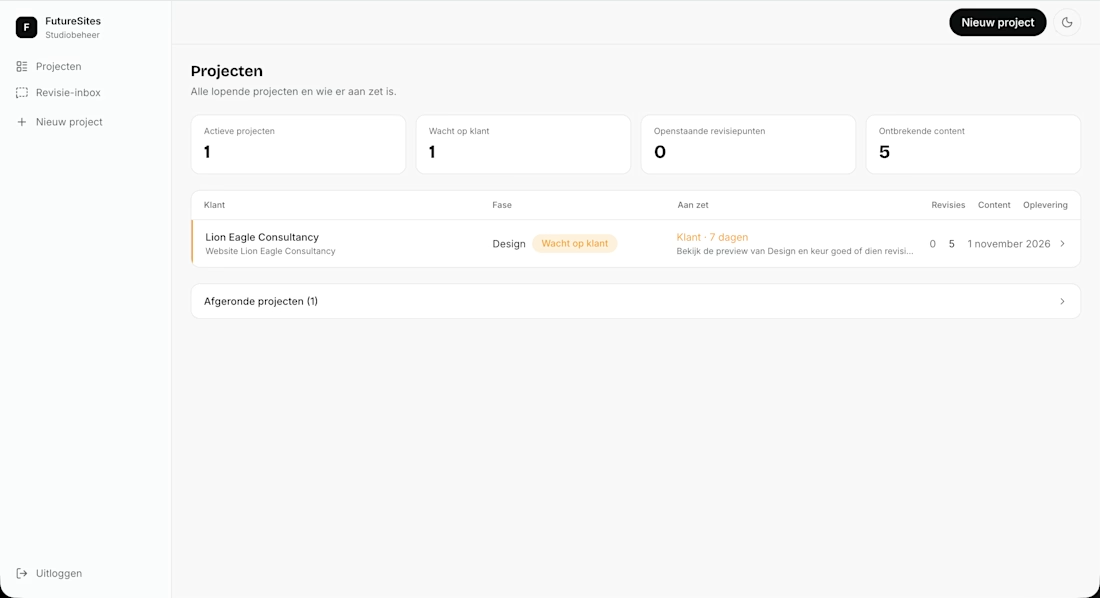
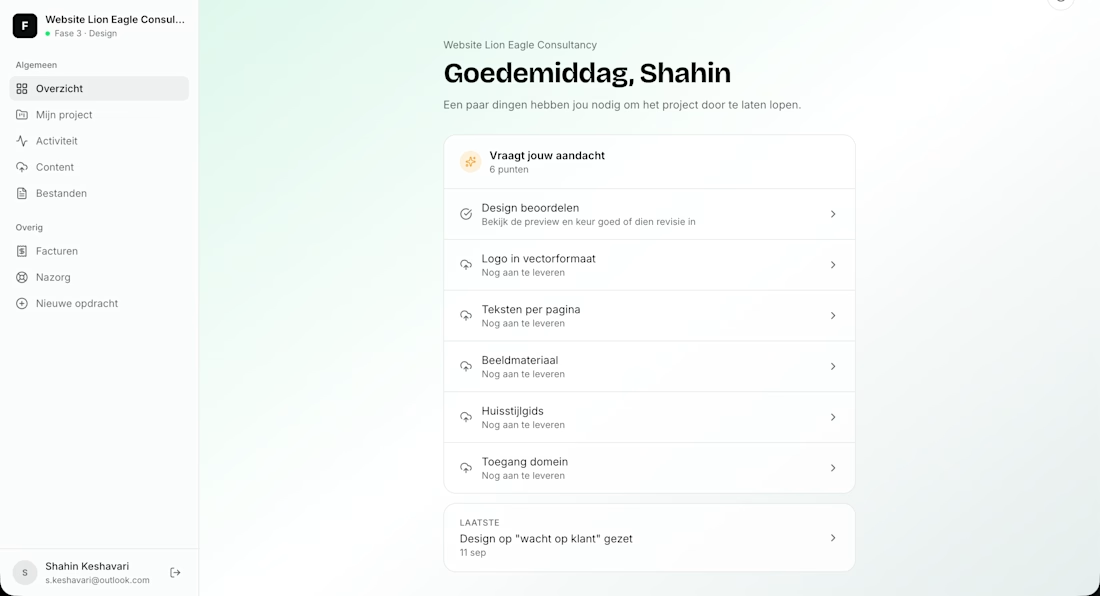
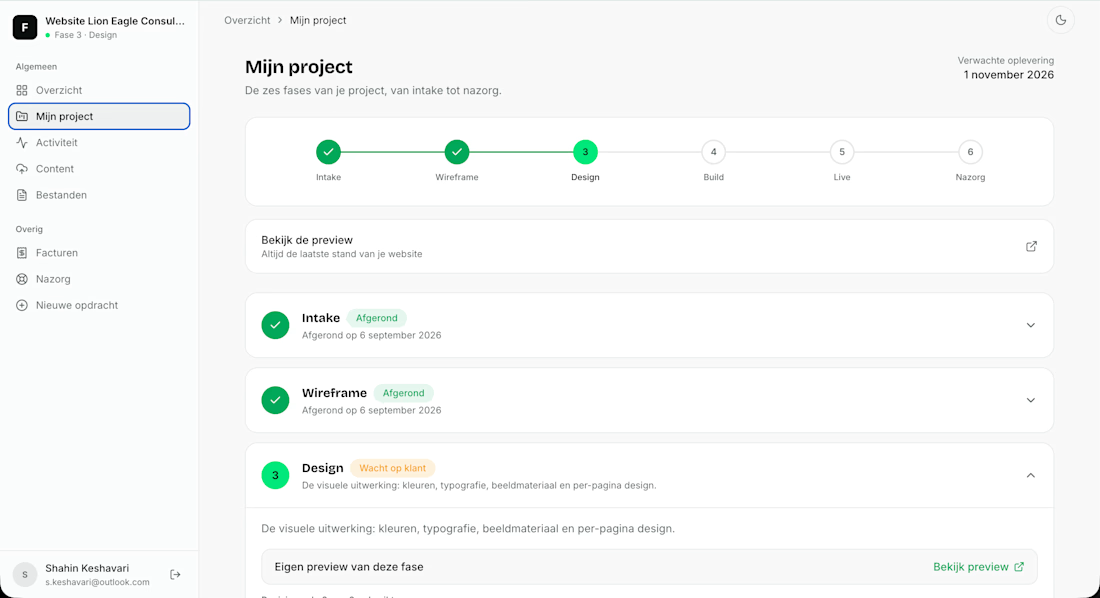
Building my own Dashboard with Claude Code. Deploying it with Vercel, Resend, Supabase.
Problem I had with last client is that it wasn't super clear where we were in the process. Or how much revision points she'd used.
There was no clear communication and more importantly, no visualization to make things crystal clear.
So I thought, I know how Claude Code works. Let's use it for a professional client dashboard.

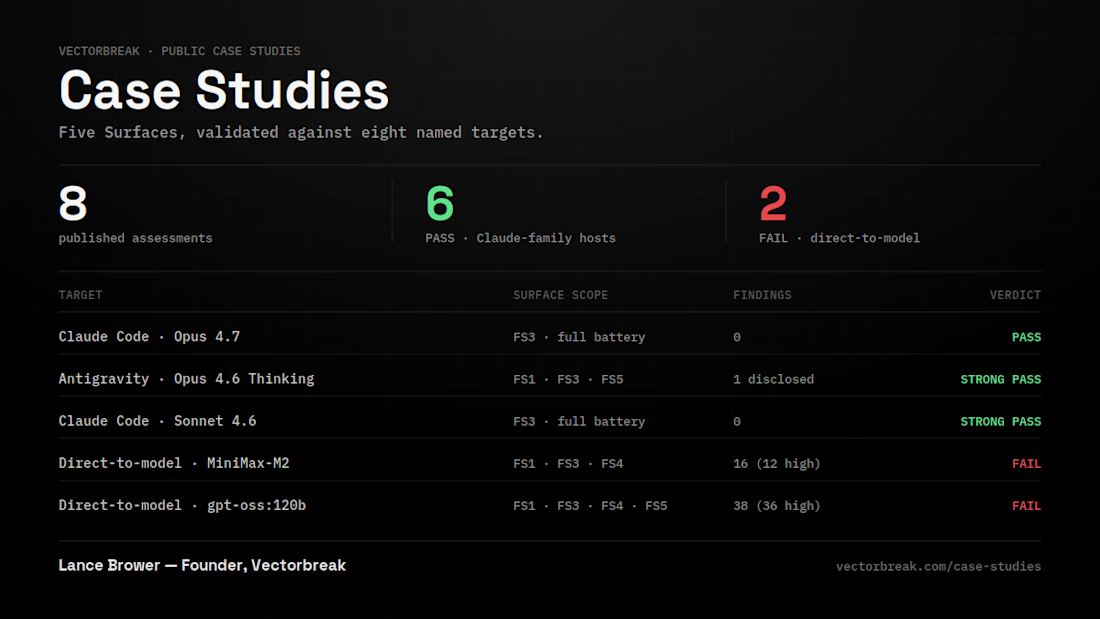
Ran the Five Surfaces methodology as a full red-team battery against
eight named AI targets. Six Claude-family hosts (Claude Code on
Opus 4.7, Sonnet 4.6, Haiku 4.5, and Antigravity on Opus 4.6 Thinking)
came back clean or with a single disclosed finding. Two direct-to-model
targets, MiniMax-M2 and gpt-oss:120b, failed with 16 and 38 findings
respectively, most rated high severity. Published as evidence-grade
case studies for insurance renewal, EU AI Act conformity, and
acquisition diligence use.


Starting the week with 3 client calls in a row.
2 active Framer + brand projects
1 new product design lead
Later this week I’m catching up with a former client who went from Seed to enterprise in 3 years. Could turn into my biggest project so far ✌️