The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

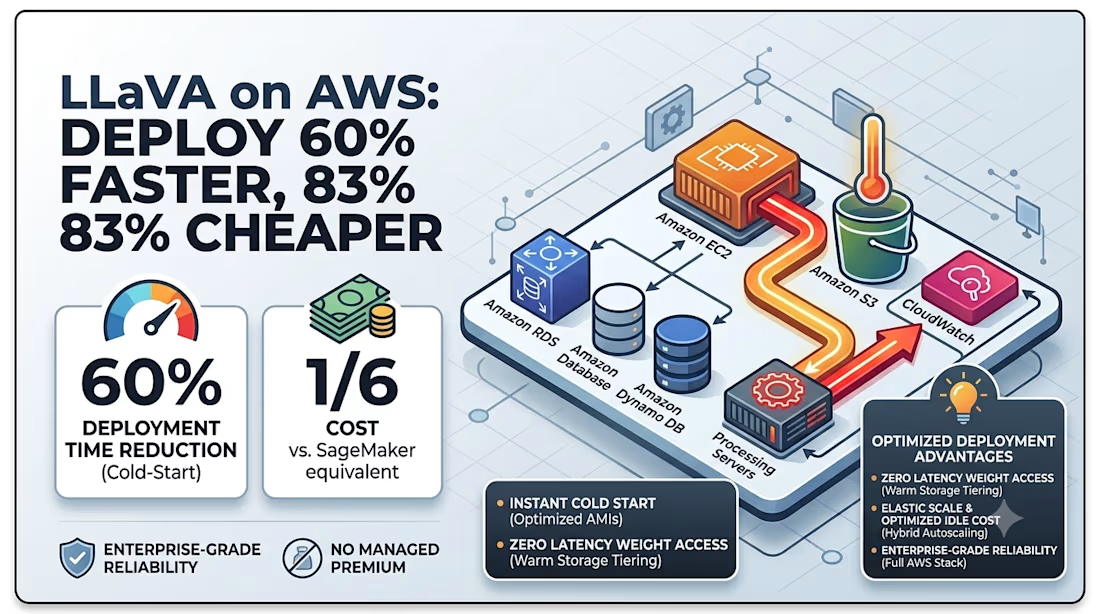
Cold start: 17 min → under 3 min. Shard loading: 16 min → 50 sec. Serving cost: ~1/6 of a managed SageMaker equivalent.
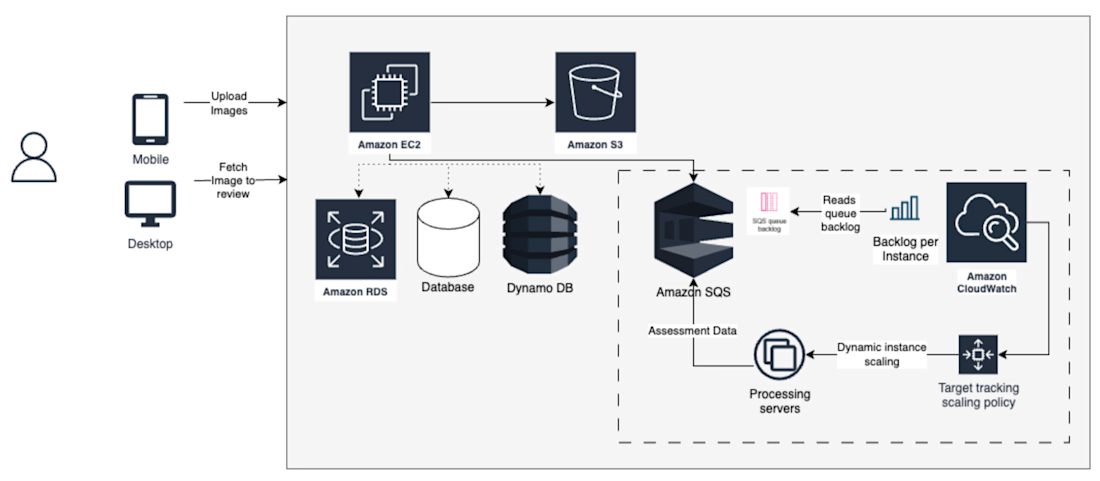
Performance-engineered a LLaVA vision-language deployment on AWS as part of a specialised strike team, with the full write-up published on LinkedIn (linked under Completed Work).
Reduced end-to-end cold start from ~17 minutes to under 3 (66%) via custom Deep Learning AMIs (−32% immediately), ephemeral-storage model caching with parallel aria2c downloads (checkpoint loading 16 min → 50 sec), and 4-bit NF4 quantization (shard loading 41s → 18s). Along the way, diagnosed a storage-path bug where checkpoint shards kept re-downloading despite being baked into the AMI.


The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Related posts

13:40: a finished Figma frame. 15:48: this, live on Vercel
Claude wrote every line of the code. I spent those two hours on the part clients actually pay for: looking at each version and saying what's off
17 commits, each one deployed. My notes went in as screenshots with red circles:
→ make the button edges look like ticket cutouts
→ replay the story chips every time you scroll past them
→ spacing 156, then 92, then back to 156
What made it fast was one Figma frame called "Ready for Dev". Every size, color and gap came from there, so nobody had to guess what the mockup meant
For a founder this means a real link on day one, and a fix you ask for at lunch is live by the afternoon


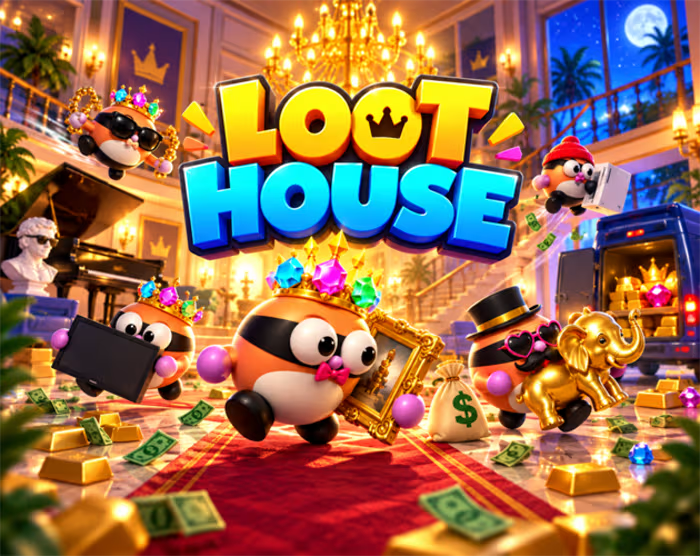
This is my 4th game that I have created but will be my 1st to be released in too weeks!! 🔥


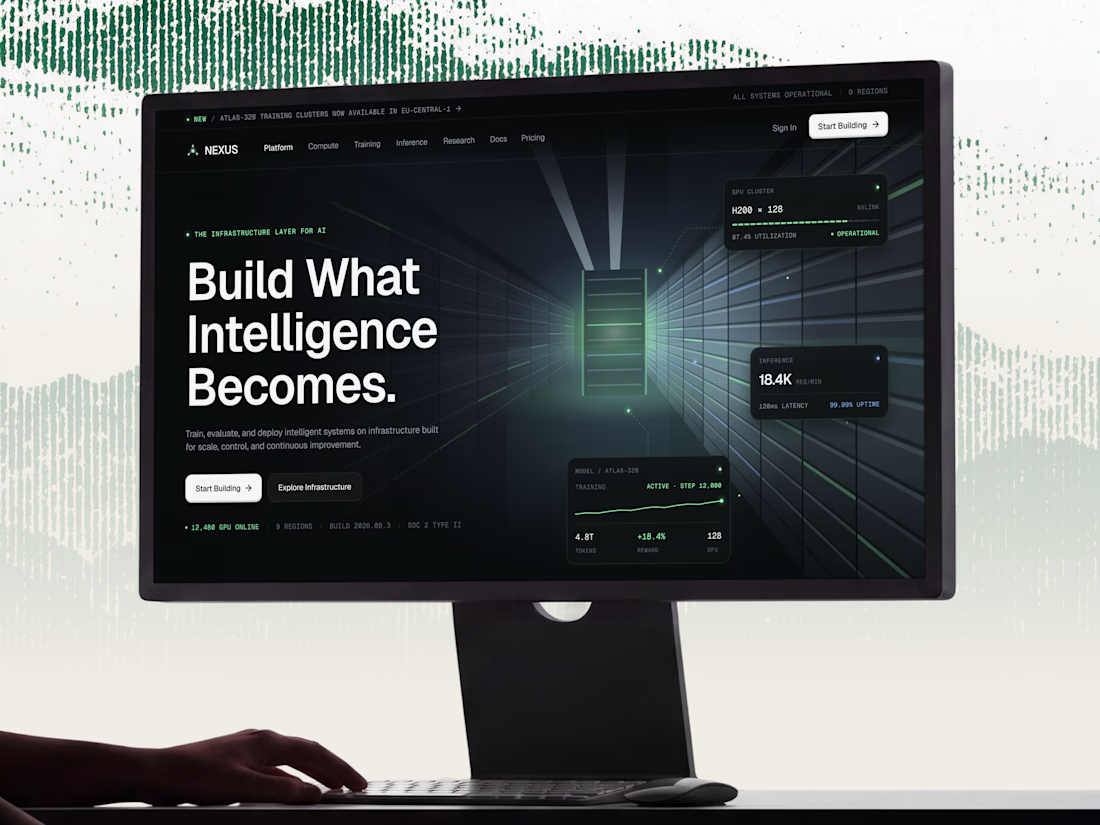
Nexus — AI Infrastructure & Compute Platform Landing Page
An enterprise-grade web dashboard ecosystem engineered for machine learning developers and AI engineering teams. The workspace provides complete observability over GPU compute allocations, training telemetry, serverless inference routing, and real-time model benchmarks.
Project Goal
The objective was to eliminate the friction of chaotic terminal logs and disconnected telemetry tools by building a unified, closed-loop AI infrastructure system. Every interface card was crafted to maximize visual scannability, streamline cluster-scale workflows, and deliver instant operational clarity without cognitive overload.
The full preview landing page is available to check directly inside the case study link! 👉🏻 Check it out