The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

Recent work: a Python scraping pipeline that collects multi-page data into a clean dataset, an exploratory analysis that turns messy tables into clear charts and takeaways, and an image annotation workflow with keypoint and bounding-box quality checks. The through-line is data quality — collecting it, cleaning it, labelling it, and documenting it so the next model or report can trust it. If you need help with scraping, analysis, or computer-vision datasets, send me a message.
The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started



Related posts

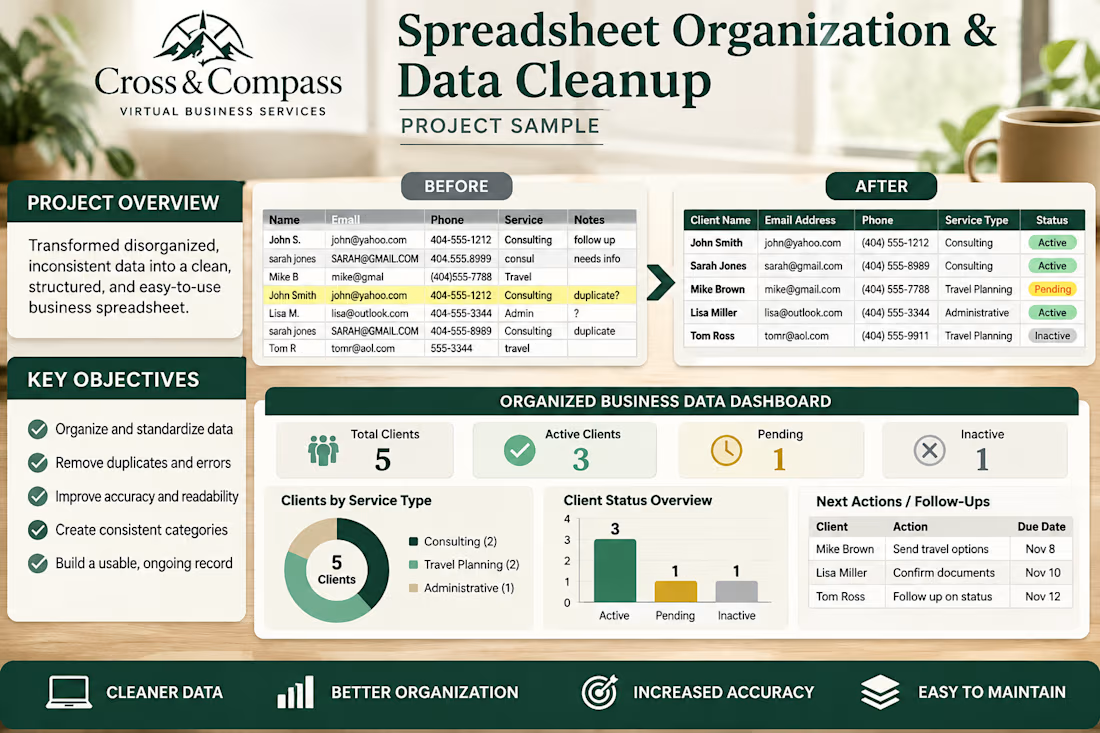
Business Spreadsheet Organization & Data Cleanup
Created a sample business data organization concept demonstrating how inconsistent, disorganized information can be transformed into a clean, structured, and easy-to-maintain spreadsheet system.
The project illustrates a before-and-after data cleanup process, including standardized client records, consistent formatting, duplicate identification, organized categories, and a clear business data dashboard.
Key features demonstrated:
-Organizing and standardizing client information
-Identifying duplicate and inconsistent records
-Improving spreadsheet readability and structure
-Creating consistent data categories
-Presenting business information in a dashboard format
-Organizing follow-up information and next actions
The objective is to help small businesses maintain cleaner records, improve accuracy, and make everyday information easier to manage.
This is a fictional sample portfolio concept created to demonstrate spreadsheet organization and business operations capabilities.


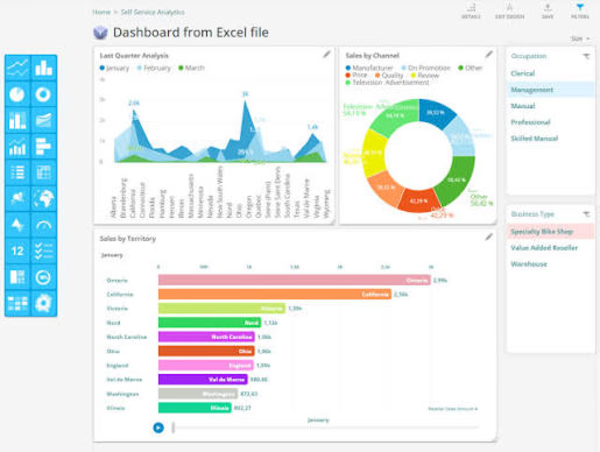
I can help you analyze data, organize information, identify patterns, and create clear, accurate reports.💯

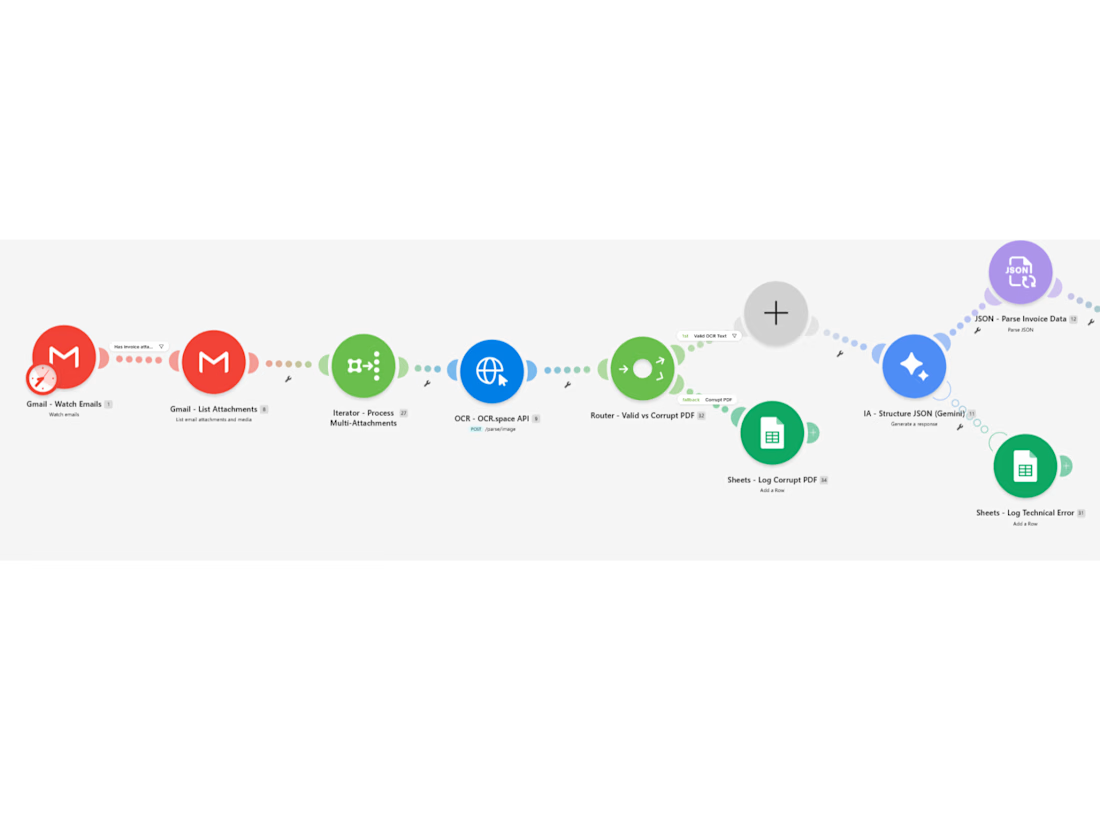
Automated Invoice Data Extraction using Make.com, OCR and AI