The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

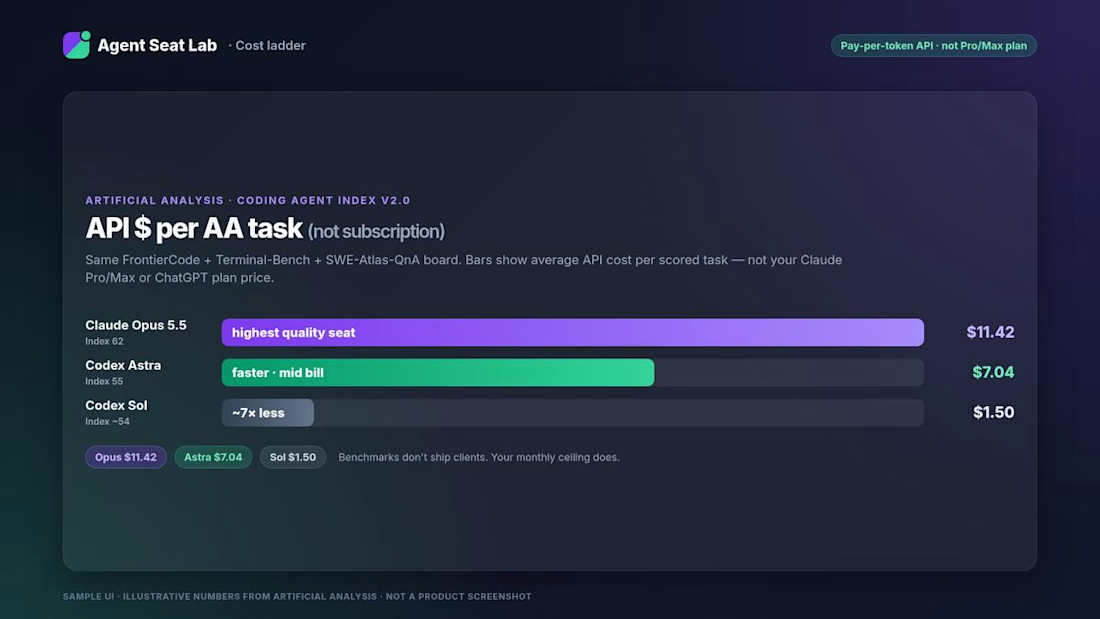
Claude Code scores higher. Codex costs ~7× less per task
I ship my own code with Claude Code. The question I keep getting from other freelancers isn't "which model is smarter?" — it's "which agent seat burns less money for the same week of client work?"
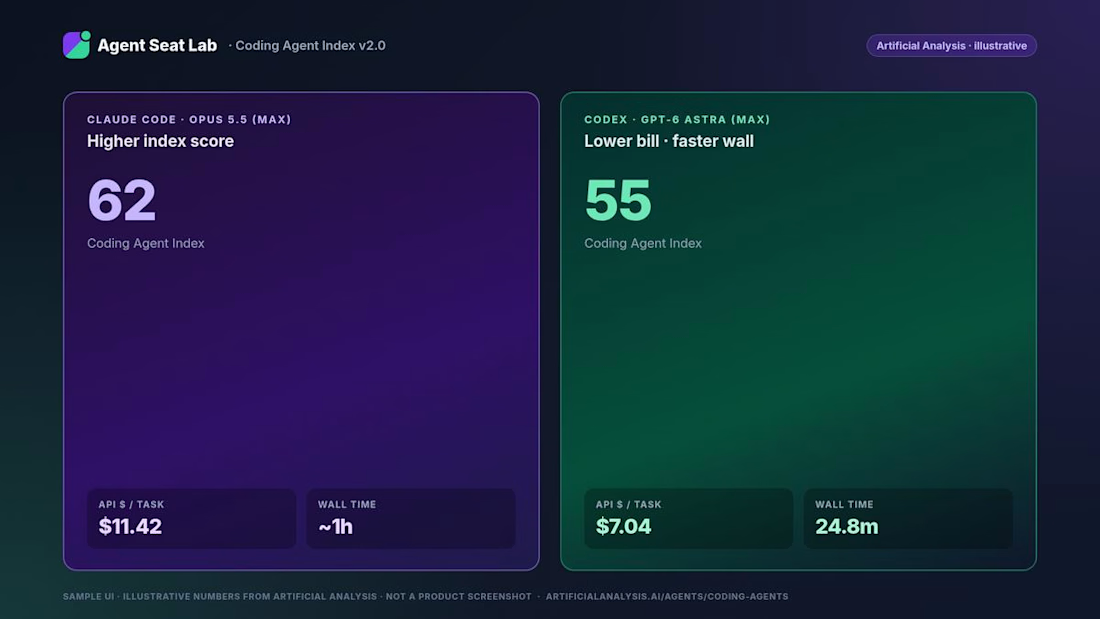
Artificial Analysis's Coding Agent Index v2.0 (FrontierCode + Terminal-Bench + SWE-Atlas-QnA) puts Claude Code with Claude Opus 5.5 (max) at 62, vs Codex with GPT-6 Astra (max) at 55. Same board, different bill: that Claude Code run averages $11.42 API cost and ~1 hour wall time per task; Codex Astra averages $7.04 and 24.8 minutes. Codex with GPT-6.1 Sol sits near 54 for about $1.50 per task. Those are pay-per-token API costs, not your Pro/Max or ChatGPT plan price: https://artificialanalysis.ai/agents/coding-agents/comparisons/claude-code-vs-codex
How I actually use that:
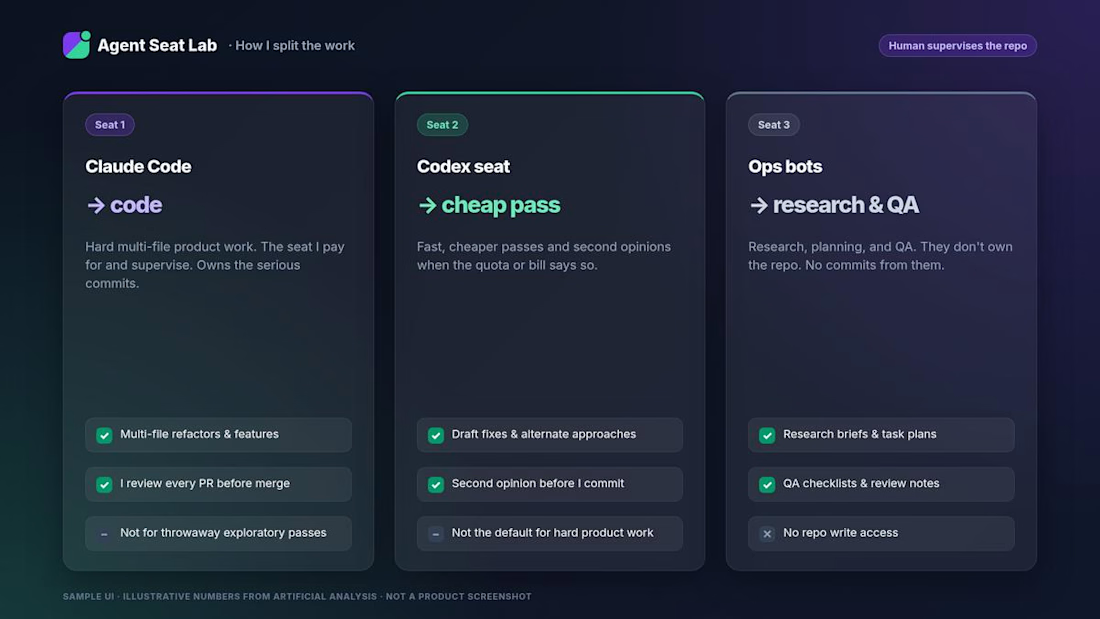
1. Hard multi-file product work → Claude Code (the seat I pay for and supervise).
2. Fast, cheaper passes and second opinions → a Codex-class seat when the quota or bill says so.
3. Research, planning, and QA → separate bots. They don't own the repo.
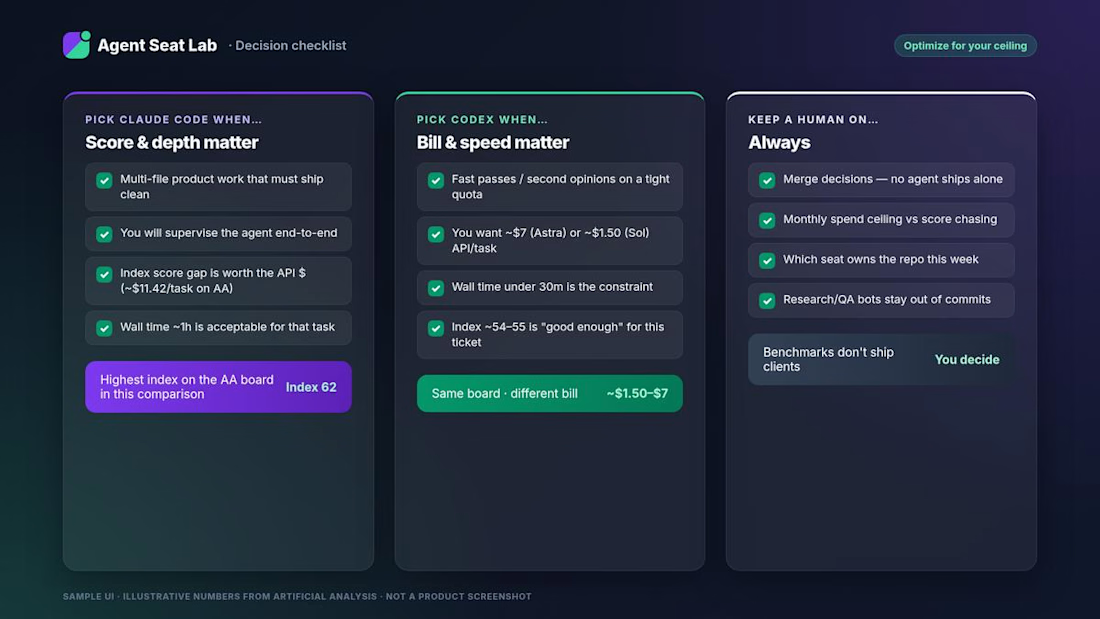
Benchmarks don't ship clients. Your monthly ceiling does.
When a coding agent burns tokens, do you optimize for score, wall time, or monthly bill first?
More at huzaifatahir.dev

The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started



Related posts

AI-Powered Physiotherapy Clinic Dashboard | Smart Appointment Scheduling
A modern AI-powered dashboard concept designed for physiotherapy clinics to simplify appointment scheduling, therapist management, and daily operations. The interface focuses on improving workflow efficiency with an intuitive calendar, smart booking experience, patient scheduling, and a clean visual system.
The design features an elegant and minimal UI, helping healthcare professionals manage appointments, therapists, and patient availability with ease. Every screen is crafted to deliver a fast, accessible, and user-friendly experience while maintaining a premium SaaS aesthetic.


so nice work

Designed an AI research workspace where the agent plans the work and fills a sheet with cited sources as it goes.
Same screen, two modes. Which one would you work in all day? 👀

13 voted
72%
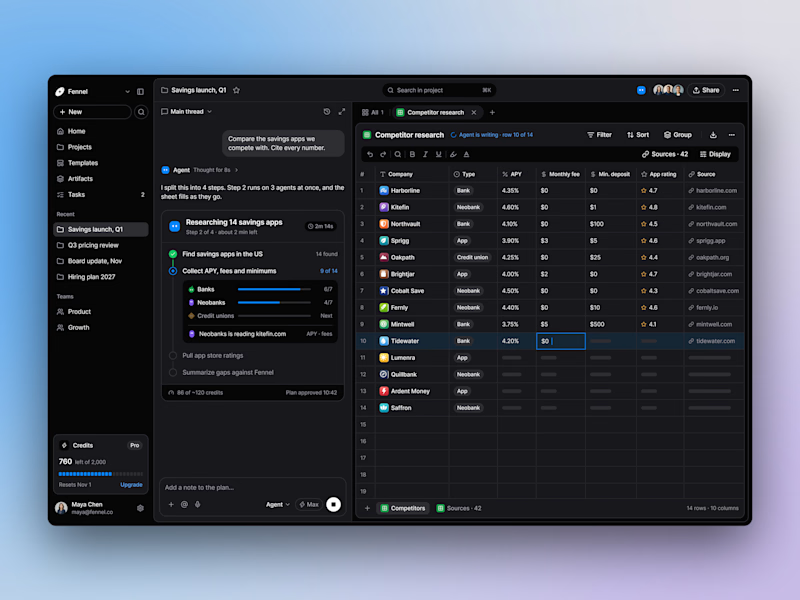
5 voted
28%
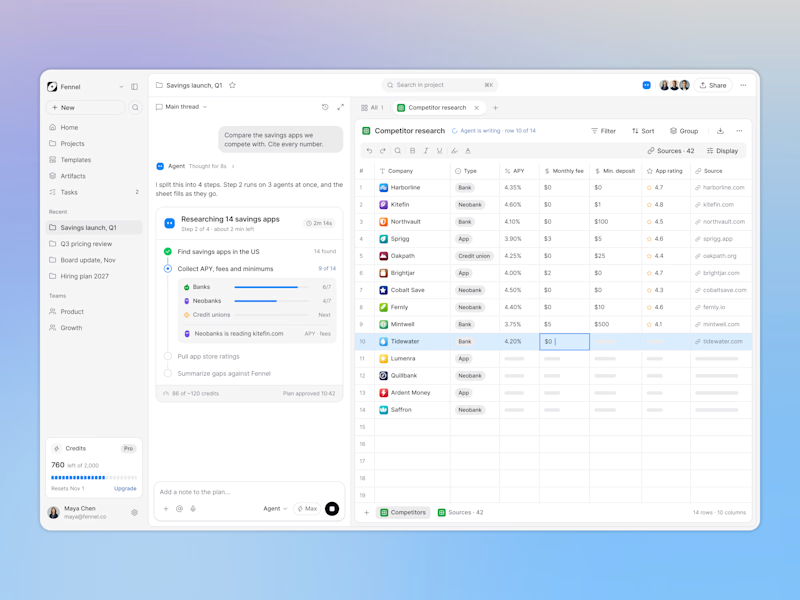
18 votes
Closed

Keeping the research plan and cited results side by side is a useful way to make the agent’s work easier to inspect. I’d lean toward light mode for reading the table in daylight. How do you distinguish a verified source from one that still needs review?


The movement flow so naturally, it feels effortless to watch.