The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost
I build scrapers that don't break when the target fights back.
Most scraping projects die the same way: script works locally, gets blocked in production, and suddenly you're burning through proxies with nothing to show for it. I've been there. So I built an engine that handles the anti-bot layer automatically.
The approach is simple: a fast light tier for normal sites, and a stealth browser tier that kicks in when Cloudflare, DataDome, or PerimeterX shows up. No manual switching. No CAPTCHA farms. The engine detects the challenge, escalates, clears it, and vaults the session so the next request doesn't have to start over.
Proof it works — tested live on my own hardware:
Google Search results: 33KB extracted via stealth browser, zero blocks
Hacker News: 34KB pulled in under 6 seconds on the light tier
Cloudflare's own diagnostic endpoint: 200 OK, challenge bypassed
The system is containerized, CI-tested, and built to run headless in production. I use it for my own data pipelines and I'm now taking on select client projects.
Typical engagements:
Competitor price monitoring across e-commerce catalogs
Real-time job board or real estate listing aggregation
SEO rank tracking at scale
Any structured data feed behind a WAF
What I need from you: 3 target URLs and a note on what data you need extracted. I'll return a sample dataset within 24 hours — no cost, no commitment. If the quality checks out, we discuss scope and pricing.
Not currently taking Facebook, LinkedIn, or Instagram scraping projects.


Here is the link to the completed work: https://github.com/mercury-systems/distributed-stealth-scraper
The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started





Related posts

This project focused on building and testing a practical AI security assessment lab for evaluating LLM defenses against prompt injection and jailbreak attacks.
I integrated Spikee by Reversec with a locally hosted cybersecurity model running through LM Studio, then added NVIDIA NeMo Guardrails to compare model behavior under three conditions: no guardrails, input filtering, and combined input/output protection.
The work included configuring the local model environment, building a custom FastAPI gateway, integrating NeMo Guardrails, troubleshooting model latency and timeout issues, creating a reusable Spikee target, and analyzing attack results using Spikee’s built-in reporting tools.
The project also explored different adversarial testing approaches, including prompt injection datasets, obfuscation, encoded attacks, Best-of-N testing, synthetic canary leakage tests, and structured benchmark comparisons.
The objective was to measure how much the guardrails reduced successful attacks while keeping the model, dataset, and testing conditions consistent.
Tools used: Spikee, NVIDIA NeMo Guardrails, LM Studio, Python, FastAPI, PowerShell, Parrot OS, local LLMs, JSONL datasets, and custom security testing scripts.
This project demonstrates a hands-on approach to LLM red teaming, AI safety testing, prompt-injection assessment, and guardrail validation for organizations deploying generative AI systems.


pretty cool tbh. testing the same attacks with different guardrail setups makes the results way more interesting.

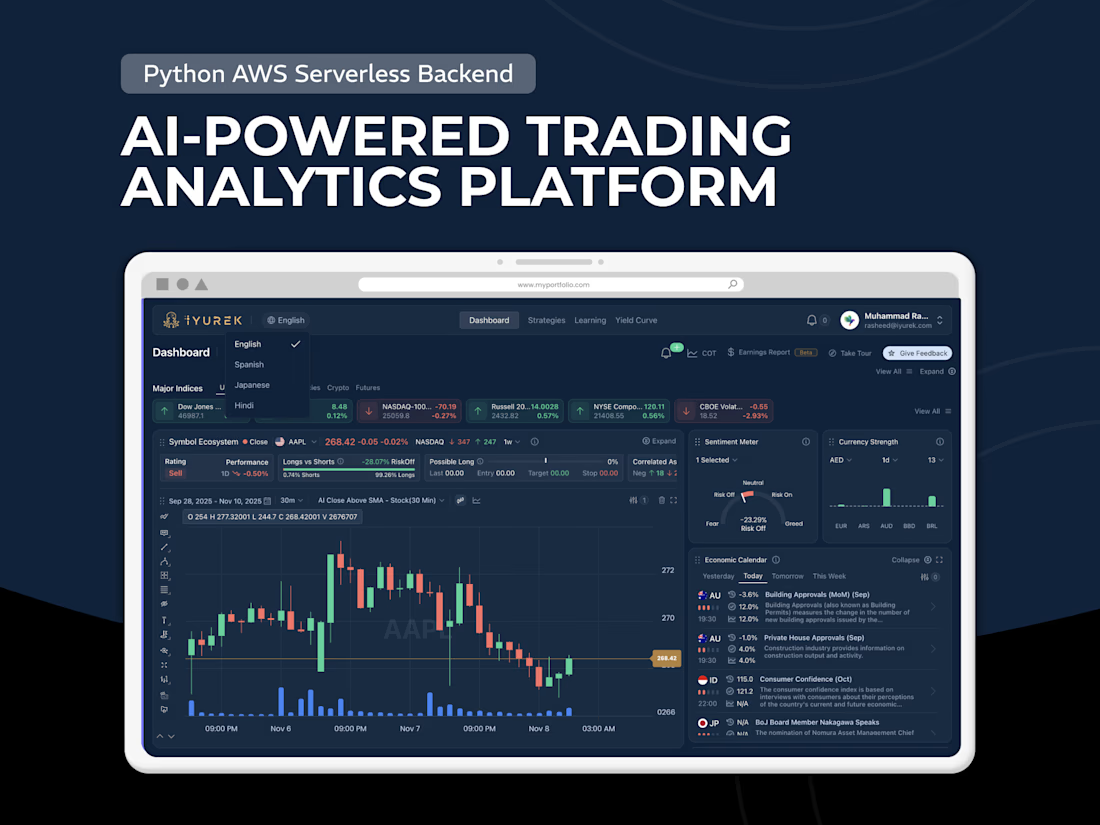
𝐀𝐈-𝐏𝐨𝐰𝐞𝐫𝐞𝐝 𝐓𝐫𝐚𝐝𝐢𝐧𝐠 𝐀𝐧𝐚𝐥𝐲𝐭𝐢𝐜𝐬 𝐏𝐥𝐚𝐭𝐟𝐨𝐫𝐦 | 𝐏𝐲𝐭𝐡𝐨𝐧, 𝐅𝐚𝐬𝐭𝐀𝐏𝐈 & 𝐋𝐋𝐌
𝐌𝐲 𝐫𝐨𝐥𝐞: Python Backend Engineer focused on AWS serverless architecture
𝐏𝐫𝐨𝐣𝐞𝐜𝐭 𝐝𝐞𝐬𝐜𝐫𝐢𝐩𝐭𝐢𝐨𝐧:
I built a serverless backend for an AI-driven trading platform handling real-time market data and analytics. I used AWS services like Lambda, API Gateway, RDS, and S3 to create a system that scales without manual infrastructure management. I designed pipelines for ingesting and processing live data to support trading signals and sentiment analysis. My focus was on keeping latency low, handling high concurrency, and ensuring the platform remained stable for global users.




What if anyone on your team could ask your data a question and get a live dashboard back in under a minute?
That was the brief. Business users were locked out of their own data. Every question waited on someone who could write SQL, data sat across disconnected systems, and security teams refused to send sensitive records to third-party AI tools.
So we flipped the model. Instead of moving enterprise data to an AI product, we moved the AI analytics product into the customer's AWS account.
What we built:
• Natural-language querying that turns plain-English questions into governed dashboards in under 60 seconds
• Federated queries across SQL and NoSQL sources through Trino
• AI query generation on AWS Bedrock Agents, with Bedrock Guardrails keeping model output in bounds
• Dashboards generated with Apache Superset, plus proactive anomaly and trend alerts
• A white-label React widget that embeds in any product
• Role-based access, row-level security and enterprise SSO enforced at every layer
The result:
Zero data egress. The whole platform deploys inside the customer's VPC and is live on AWS Marketplace.
Building AI features for a data-heavy or regulated product? Let's talk about doing it without your data leaving your cloud.
