The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

A system being “up” does not mean it is healthy.
Customers can experience slow responses, failed transactions, or inconsistent behavior while every server still appears online.
That is why observability matters.
I want a production system to answer simple questions quickly:
What failed?
When did it start?
Who was affected?
Where did the delay happen?
What changed before the problem appeared?
Logs, metrics, and traces are not just debugging tools. They reduce the time between discovering a problem and understanding it.
Good engineering is not only about building systems that work. It is also about making failures easy to detect, explain, and resolve.
The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started



Related posts

The fix for an agent that keeps getting your design system wrong isn't a better prompt.
It's putting the rules where the agent reads them.
In the repo. In skills. In checks it can run itself.
Writing a course about exactly this.

What sells it for me is the refusal telling the agent exactly where the token should go. A bare "no hex" error usually just sends it looping. Does guard.mjs run only as an agent hook, or in pre-commit too so it catches humans as well?

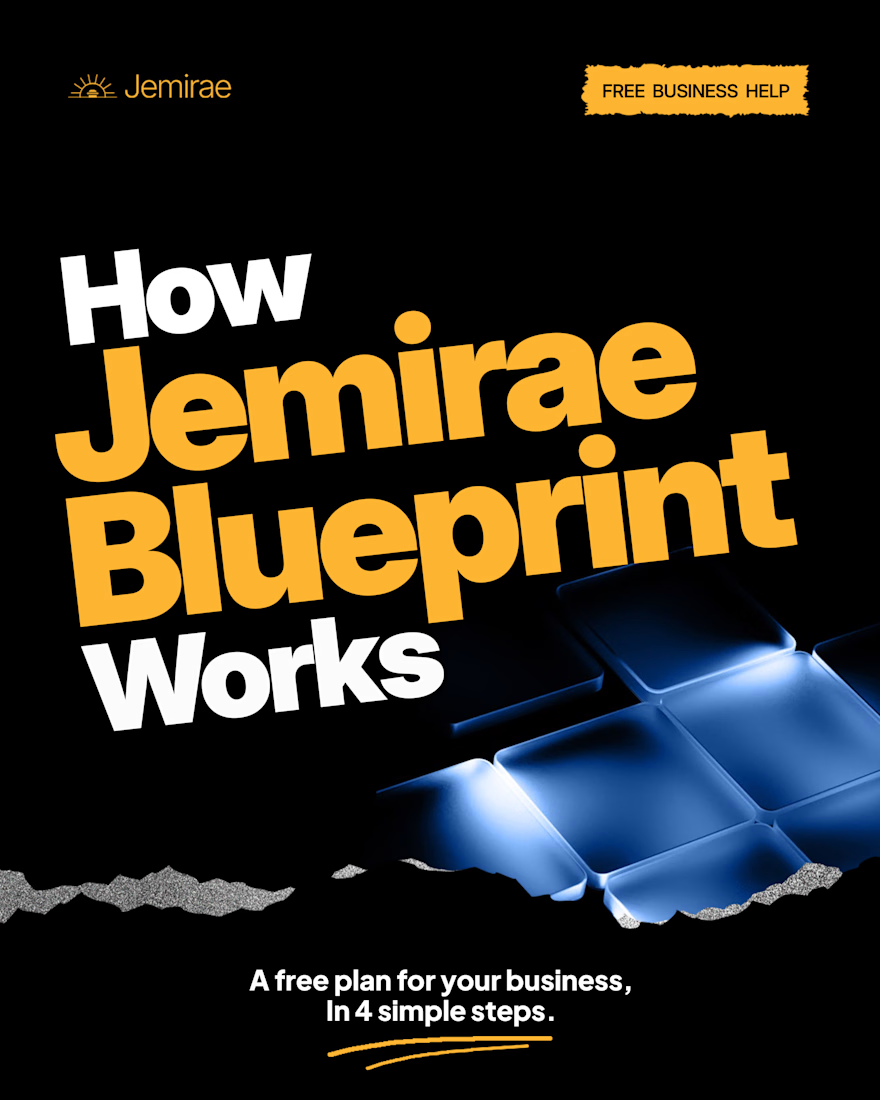
A free tool for anyone running a business and not sure what to fix first: Jemirae Blueprint.
Describe what is not working, in your own words. Get a clear diagnosis of what is holding you back and what to do first. Come back anytime, it stays free.
jemirae.com/blueprint
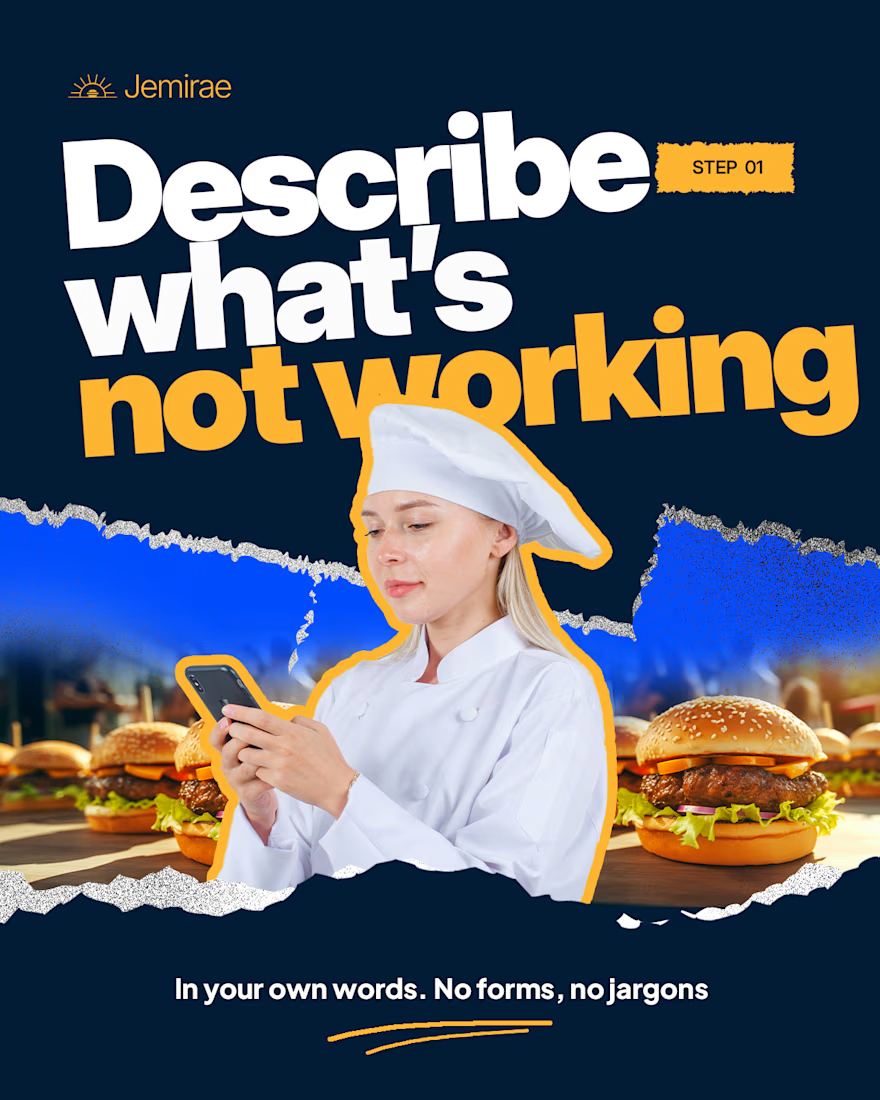

So needed. Most owners skip diagnosis and jump to "I need ads."
I audit Illinois restaurants and 80% think they need followers, but the real problem is they are invisible on Google Maps. Wrong diagnosis = wasted money.
Your approach — "describe it in your own words" — is perfect....

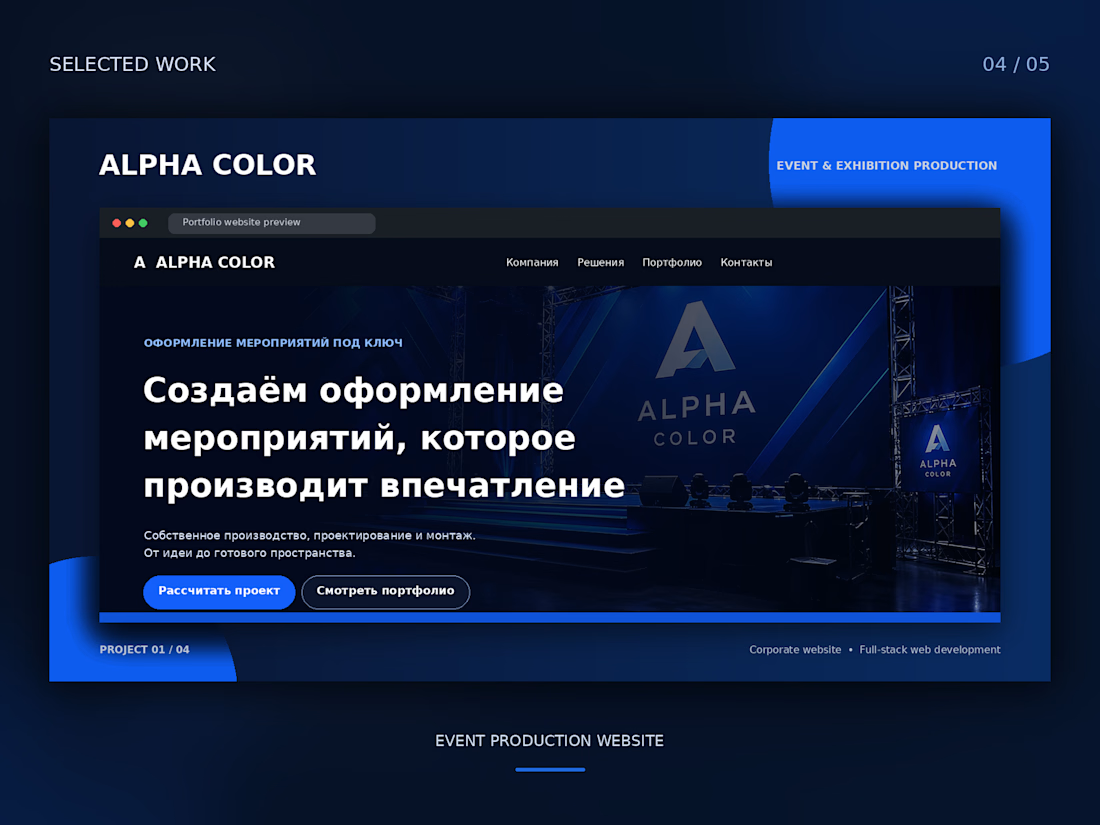
Developed a custom corporate website for an event production and creative services company.
The platform showcases event solutions, production capabilities, completed projects, and professional services through a modern dark-themed interface.
Implemented multiple service and portfolio pages, interactive elements, responsive navigation, and customer inquiry forms with server-side processing.
Built with PHP, HTML5, CSS3, and JavaScript, with a focus on responsive design, structured content, and a consistent visual identity.