The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

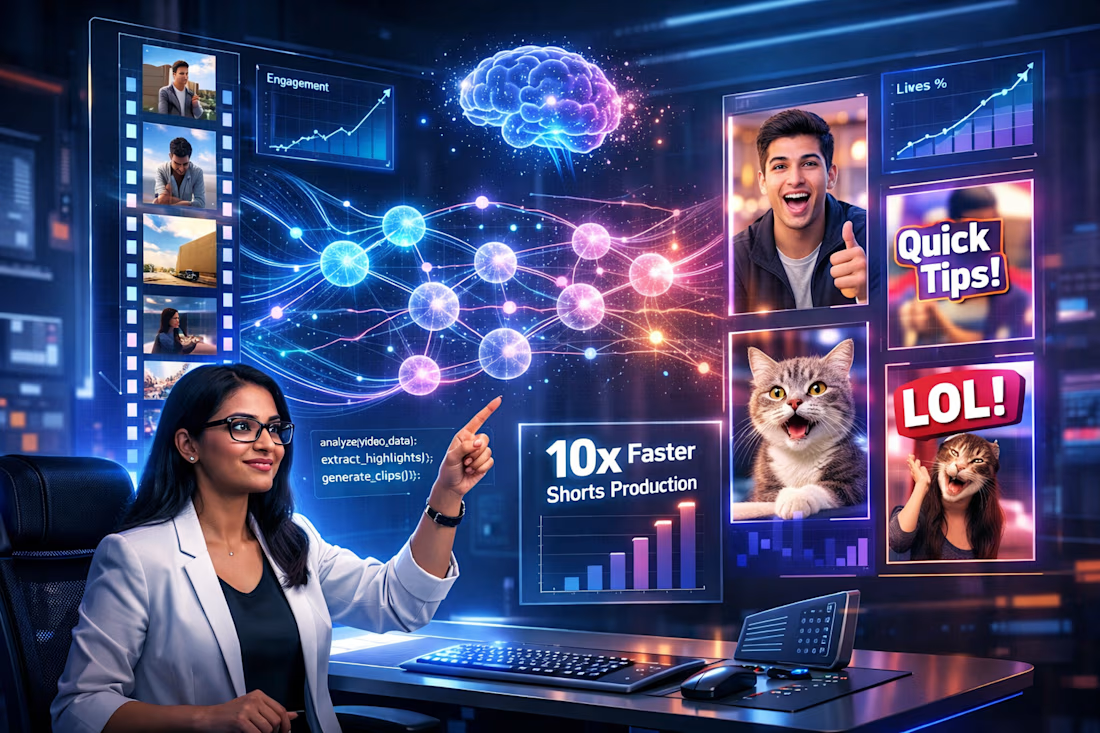
Multi-modal transformer-based model that fuses audio spectrograms, video frame embeddings, and contextual text transcripts to autonomously generate highlight clips from long-form videos. The architecture employs a Combiner module for joint spatio-temporal feature extraction from aligned audio-video chunks, followed by an autoregressive Transformer that models temporal dependencies across partitioned video segments, enabling context-aware detection of engaging moments like speech peaks, visual action shifts, and semantic relevance.
Achieves 72.2% F1-score for highlight detection—outperforming unimodal baselines by 7-10%—while reducing clip generation time by 10x and boosting viewer engagement metrics by 25% through precise 15-60 second excerpt selection


The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started







Related posts


I'm building midcode.
a tool that let's you turn code websites into no-code
super useful for AI-led sites where we want to edit things visually


A little motion from my work for Herb Agency. This is one of three vertical ads introducing their growth services.
The edit combines a talking head with animated graphics. Under 20 seconds to keep the message clear and the pacing moving.
How does the rhythm feel: just right, or would you let a few moments breathe?

nice

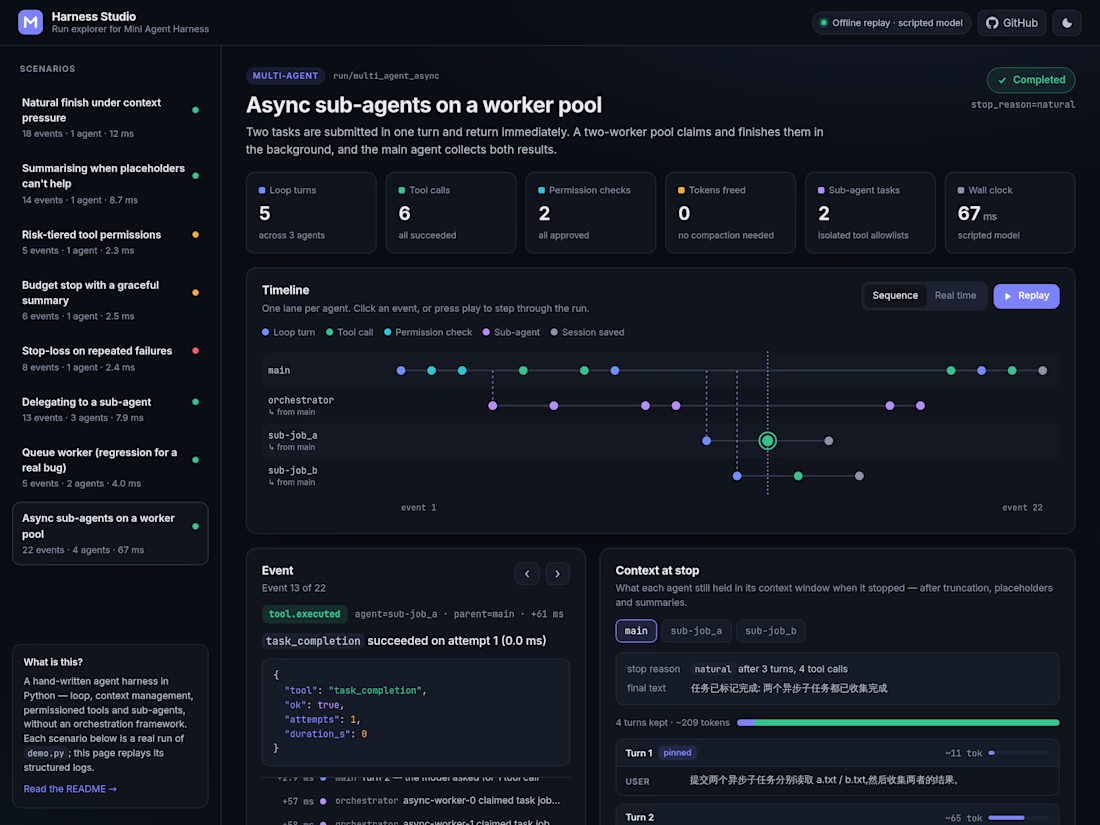
Most agent bugs are invisible: the agent loops, drops context or calls a tool it shouldn't, and all you see is a wrong answer. I wrote an agent harness from scratch in Python — loop control, context compaction, permissioned tools, sub-agents — and Harness Studio, a web app that replays every run: one lane per agent, each event explained, and the exact context each agent held when it stopped.