The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

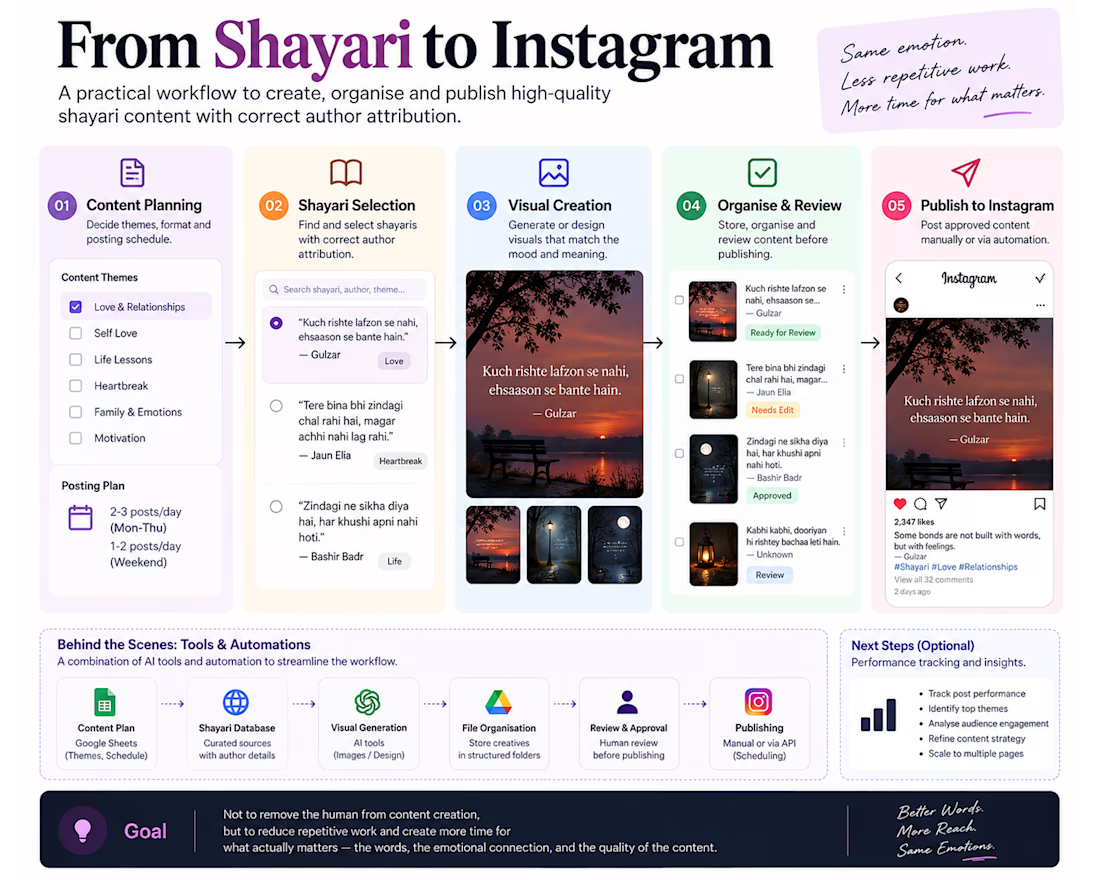
What if running an Instagram page became less about posting every day and more about building a system that does the repetitive work?
I'm testing this idea with a shayari and relationship-content page.
The workflow I've been building connects several steps:
→ Content planning
→ Selecting shayaris with the correct author attribution
→ Creating visuals that complement the words
→ Organising content for review
→ Human approval before publishing
The objective isn't to remove the human from content creation. It's to reduce repetitive work so more time can go into what actually matters: the words, the emotional connection, and the quality of the content.
But here's the interesting question.
If you were running multiple Instagram pages, would you automate the entire content pipeline—or deliberately keep some steps manual?
I'd love to hear from people who've experimented with this. What's the one part of running a content page you'd automate first, and what would you never trust automation to handle?
#InstagramAutomation #AIAutomation #ContentCreation


The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started

Challenges
View all


Related posts

A visitor has a question. A customer wants to book. Your team needs the details.
That’s where I see the real value of AI: helping people take the next step.
At UI Trax, I build websites, AI assistants, and workflows around everyday business needs:
💬 Customer questions and service guidance
📅 Booking journeys
🎯 Lead capture and organised enquiries
⚙️ Automation for repetitive tasks
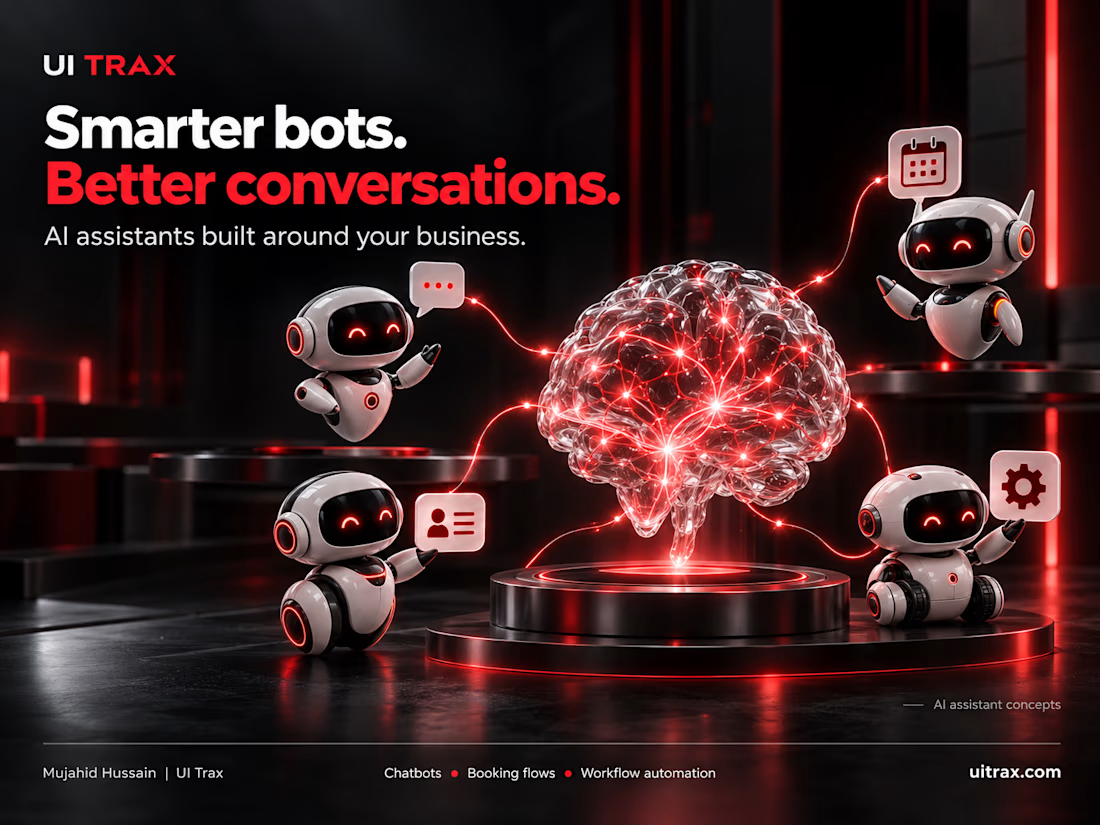
This visual brings those use cases together—different assistants, each with a clear purpose.
Meet one real example: Orion, our website AI assistant. Tell it about your business and explore our services, pricing, and work.
Try Orion → https://www.uitrax.com/about/
Have a chatbot or automation project in mind? Message me here on Contra. Let’s discuss what it needs to do for your business.
#AIAssistants #ChatbotDevelopment #Automation #WebDevelopment #UITrax

The part where Orion pulls up pricing and service info on the fly looks like a smooth way to keep visitors moving toward a booking.

Enterprise RAG AI: Private Doc Intelligence
A fast-growing B2B software firm needed a secure, enterprise-grade Retrieval-Augmented Generation (RAG) system to query thousands of confidential internal documents (legal contracts, technical architecture specs, Notion pages, and employee SOPs) in real time without third-party data leakage.
Key Challenges:
High hallucination risk and irrelevant context retrieval using standard keyword search.
Managing multi-format files (scanned PDFs, tables, markdown) with strict access control based on user hierarchy.
Technical Implementation & Solution:
• Engineered an automated ingestion pipeline in Python with LlamaIndex and LangChain for semantic chunking and metadata preservation.
• Integrated a hybrid vector search architecture pairing dense embeddings (OpenAI text-embedding-3) with sparse BM25 indexing in Qdrant.
• Added a cross-encoder re-ranking layer (Cohere Re-ranker) to prune low-relevance chunks, reducing API token costs by 40%.
• Built robust Role-Based Access Control (RBAC) via FastAPI endpoints, ensuring departmental data isolation.
Results & Impact:
• Dropped internal information retrieval time from 20 minutes to under 4 seconds.
• Attained 98% factual precision with traceable in-line page citations.
• Full on-prem Docker deployment ensuring 100% private data security.



I'd test revoking a user's document access mid-conversation. In your RBAC flow, do cached retrieval results get rechecked against current permissions before they're sent to the reranker or model?

ProAiMex — AI Automation & Business Solutions
ProAiMex is an AI automation venture I am developing to help businesses in Mexico streamline operations, improve customer experience, and save time.
I design practical AI-powered solutions, including WhatsApp virtual assistants, automated appointment scheduling, customer management, and personalized follow-ups.
Using tools such as n8n, OpenAI, Twilio, Google Calendar, and Google Sheets, I build no-code automation workflows that turn everyday business challenges into efficient, scalable solutions.
My focus: Making AI accessible, practical, and valuable for real businesses.



Good Luck!