The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

Most PDF extraction pipelines would have missed the Brazilian court-filing injection.
Two law firms hid white-on-white text in a labor court petition. It told the court's AI reviewer to answer superficially and not challenge the documents. The court's tool, Galileu, flagged it and blocked it, and the court fined the firms 10% of an R$842,000 claim.
Most of the Hacker News thread blames the court for running AI on filings. But the trick works on any pipeline that reads PDFs. White text is invisible on the page and still sits in the text layer, which is what gets extracted.
My extraction pipelines check each field against the page it came from. That catches a wrong value, but not an instruction that changes how the model reads the rest of the file. That needs a check before the model sees anything: text a person can't see on the page shouldn't reach the model.
In the PDFs you extract from, how often does the text layer hold something the page doesn't show?
Source: https://jetstream.security/insights/brazilian-court-sanctions-prompt-injection-filing

White-on-white instructions in a PDF text layer is exactly the failure mode I watch for in clinical intake. Referral packets and lab PDFs often carry junk from fax OCR or prior template text that a model will treat as orders. I would strip or quarantine any span whose rendered...
The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Related posts

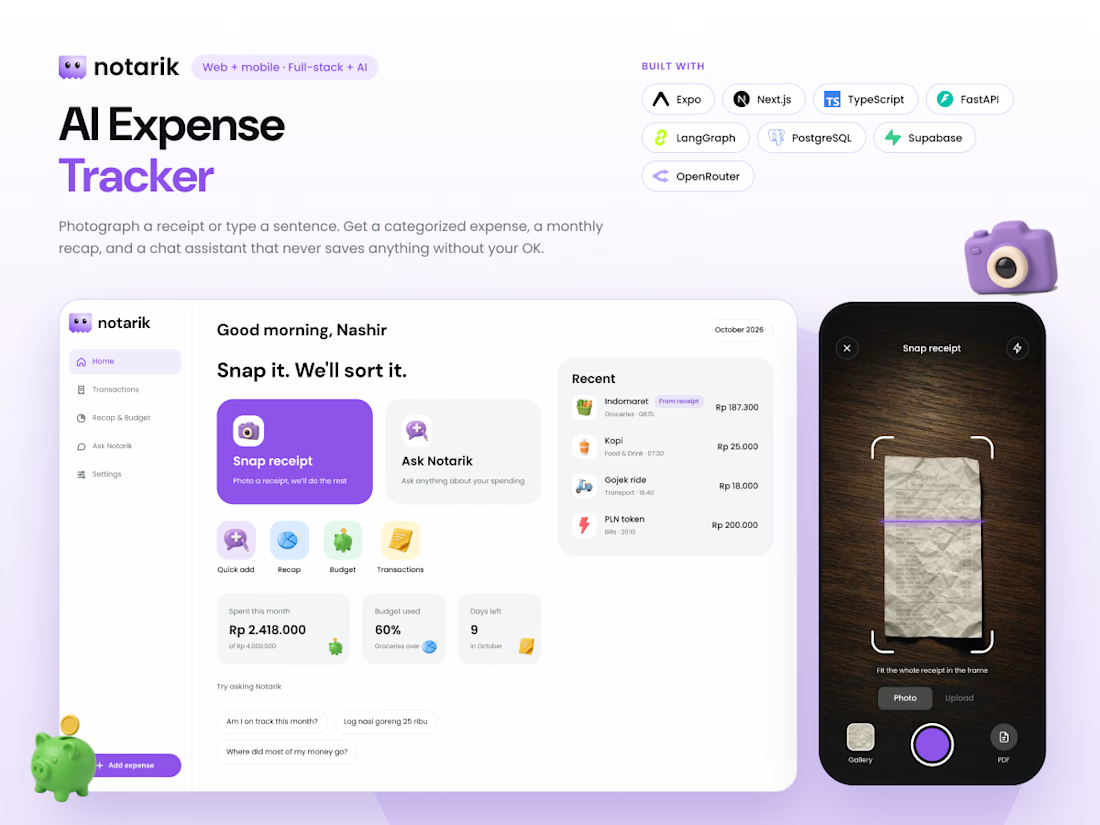
Most AI apps work like this: the model decides, the app saves, and the user finds out later that the numbers are wrong. 😬
For Notarik, I set one rule. The AI can only propose. Nothing gets saved until the user confirms. ✅
🧾 What it does
Take a photo of a receipt, or type "lunch 45k at the warung". You get a categorized expense, a monthly recap, and a chat assistant you can ask things like "where did my money go this month?":
🔒 The parts I care about most
• Receipt totals are checked by plain code, not by the model. If the math doesn't add up, it gets flagged.
• Money is stored as whole numbers (IDR), never decimals, so there are no rounding bugs.
• Every user's data is locked at the database level with Postgres row-level security. Even if the app has a bug, it can't show someone else's records.
• Text on a receipt is treated as untrusted. If a receipt says "ignore your instructions", it's just text.
• The agents have tests, so when I change a prompt I can see right away if it got worse.
🛠 Built with Next.js, React Native, Python (FastAPI), LangGraph and PostgreSQL. One person, web and mobile, from design to API.
🤝 If you're building something where an AI touches real money, records or user data, this is the kind of work I like: agents that are useful and also safe to put in front of users.
👉 Try it live: https://notarik-app.nashir.tech
Want to talk about yours? Send me a message.



Smart call keeping the confirmation.

AI can build a Webflow page in minutes. Keeping it on-brand is the hard part.
Pages drift for four reasons:
- No variables, so the AI guesses colors and sizes
- Loose class names, so it keeps making new classes
- No section library, so every page is a new layout
- No written rules for the AI to follow
If you don't have a solid foundation, whatever you do, you'll end up with a lot of clutter.
Wrote an article about it:
https://www.wicked-genius.com/articles/webflow-ai
wicked-genius.com
Webflow AI: how to build on-brand pages with AI
What Webflow’s AI tools can do for a marketing team today, why AI pages drift off-brand, and the four layers that keep them consistent.

Variables and strict class naming are exactly what keep Webflow builds clean, AI or not. Giving the AI a section library and written rules sounds like the only way to stop the drift.


Motion Design without AI, what do you think?
This is a short self-promo video showcasing our approach to motion design and how I help brands present their products in a more engaging way.
It’s always a good reminder that we should invest in our own brands just as much as we do in our clients.


Proof that human taste and frame by frame intention still beat generative video every single time. Did you plan the entire script upfront in Figma?