The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

AskRAG — RAG-Based Codebase Q&A Tool
Built a retrieval-augmented generation (RAG) tool that lets developers ask natural-language questions about any codebase and get accurate, context-aware answers. Designed and built the full backend using FastAPI, with FAISS for vector storage and all-MiniLM-L6-v2 embeddings for semantic search. Integrated Gemini 2.5 Flash for response generation, PostgreSQL/Supabase for data persistence, and GitHub OAuth for secure repo access. Also built the React/Vite frontend and resolved a critical authentication bug involving JWT cookie handling. A working prototype demonstrating practical LLM application design — from embedding pipelines to secure auth flows.
Project link: https://github.com/khadijayy/askrag


The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started





Related posts


what does this tool does?

no-code.supply is open.
I've been quietly building landing page templates. Six are out today, each with its own brand, its own type pairing and one interaction it's built around:
→ Aurel: a skincare brand with a WebGL serum drop that bulges toward your cursor
→ Ferro Type: a type foundry where the hero word bends its weight and width under the pointer
→ Meridian Expeditions: contour maps that redraw themselves as you switch routes
→ Oda: an architecture studio whose timber cabin draws itself, with a live sun study
→ Relay: a dev tool where the editor types a workflow and the run graph executes it live
→ Signal: a mission-control SaaS with a live infrastructure graph that contains threats as they flare
Built to be edited with AI. Every template ships with a README, a DESIGN.md and an AGENTS.md, so Claude, Cursor or whatever assistant you use changes it the way it was built, not the way it guesses.
Pricing, per template:
• HTML: $29
• React: $59
• Bundle (HTML + React): $79
Or get All-Access for $169: all six templates, both editions, plus every future drop. Nine more are on the way, at no extra cost.
No page builder, no lock-in, no third-party requests.
If you build sites for clients, I'd love to hear which one you'd use first.


Ferro Type is the one I would open first. Bending a variable font under the pointer re-lays out the text every frame, which is a much bigger bill than it looks, and stepping the weight in a few fixed increments is usually what keeps it smooth on a laptop that is not plugged in....
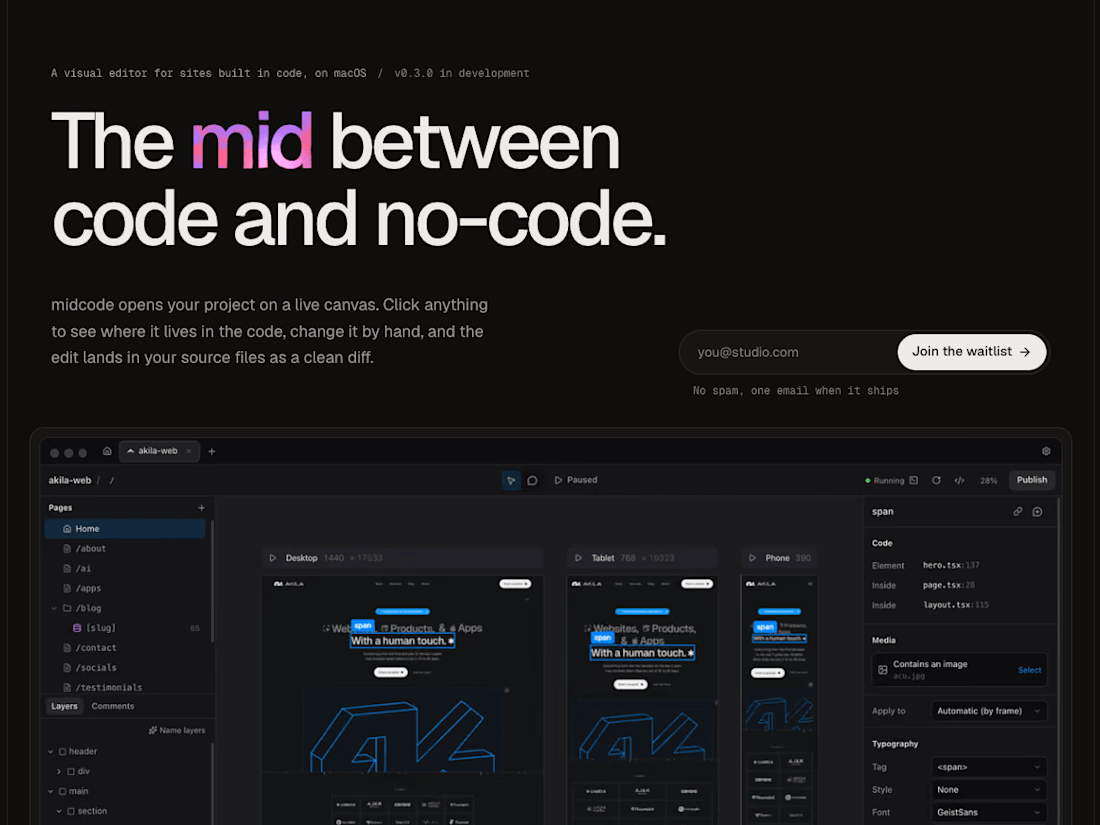
let me walk you through midcode.app