The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

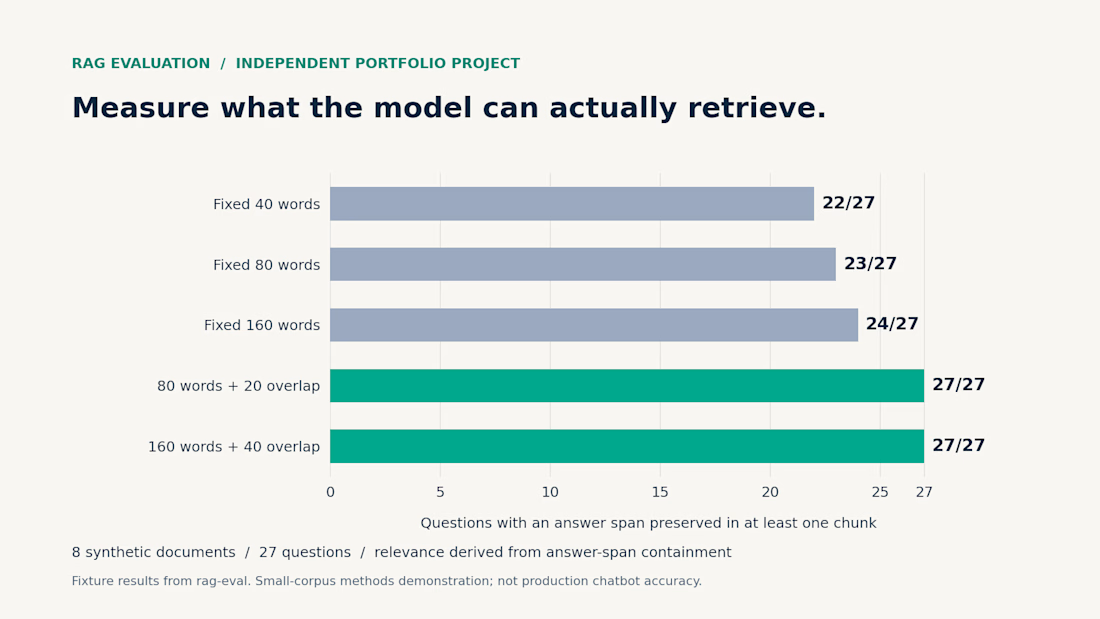
RAG Eval: measure retrieval before trusting an AI answer
Independent Python evaluation harness comparing BM25, TF-IDF, hybrid retrieval, and document chunking on a small synthetic corpus of eight documents and 27 questions. Relevance is derived from answer-span containment and recomputed for each chunking strategy. Fixed-size chunks without overlap make three to five questions unanswerable; overlap preserves all 27 answer spans in the included fixture. The project includes 18 tests and reports ranking metrics, cut-off saturation, and limitations. This demonstrates reproducible evaluation methods, not production chatbot accuracy.

The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started





Related posts


Messy Data In. Clearer Decisions Out. 📊
Over the past year, I've noticed most businesses don't struggle because they lack data — they struggle because that data never turns into a decision.
That's the gap I work in:
→ Cleaning and analyze data with Python & R
→ Turning findings into investor-ready pitch decks
→ Polishing the final write-up so nothing gets lost in translation
If your team has data sitting in spreadsheets with no story attached, or a pitch deck that needs to actually land — that's exactly where I can help.
Open to projects. Let's talk 👇



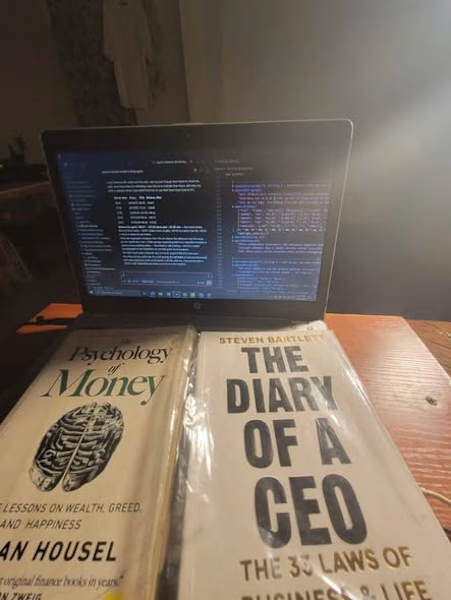
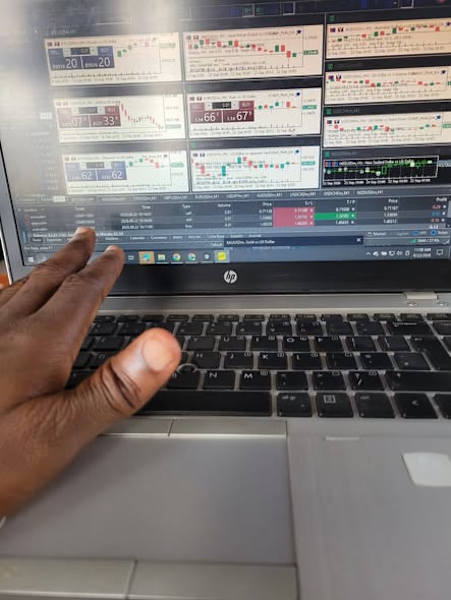
Another late night. Building a quant trading system an agentic model where different AI agents handle research, testing and risk, and none of them is allowed to place a trade on its own.
The hardest part so far? Being honest when the results say "not yet." Most strategies I've tested failed once real costs were included. That's exactly what testing is for.
Keeping The Psychology of Money and The Diary of a CEO close while I figure it out. What are you reading these days?

Curious how you’ve separated the agents from execution. When you say none can place a trade on its own, is that enforced through a separate execution service with fixed risk checks, human approval or both? I’d love to understand where the agent's decision-making ends and the hard rules take over.

If you're paying for Claude, Cursor, or Codex and you're still pasting the same vague prompt into every new chat, the model isn't your bottleneck.
Here's the tell: you type some version of "we don't do it that way" more than once a week. That correction is real engineering knowledge. Right now it lives in your head and dies when the conversation ends.
Two things fix that.
Knowledge is the context you make available; your architecture, your business rules, your API docs, your constraints, and the reasons behind the decisions you already argued about once.
Skills are the recurring work written down once: the steps, not the explanation.
Adding an API endpoint, concretely. Knowledge tells the agent how auth works, what the data model looks like, and why the team picked the conventions it did. The skill tells it what to do: read the two closest existing endpoints, follow the same validation pattern, update the API contract, run the tests that cover it.
You still review the diff. You still own the decision. You've just stopped re-explaining your own codebase five times a week.
Start with one task you repeat. Write the steps. Supply the context. Then check the thing that actually matters: did the rework go down, or does it only feel more organized?
A subscription buys access. Getting useful work out of it is engineering.

The "we don't do it that way" test is a great way to put it. Every correction you repeat should end up in a rules file, not in the next chat. Making that a habit changed how I work with agents too.