The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

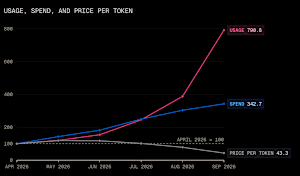
An 80% token price cut barely changes what a document pipeline costs to run.
Max Woolf's post lists every cut since June and asks why. GPT-5.6 Luna went down 80% in July, and Opus 5.5 launched at $4 and $20 per million tokens. The Hacker News thread is about IPOs and open-weight models, not about the apps already in production.
I build extraction pipelines for 200-page loan files and for tickets in any layout, and the LLM call was never the slow or the risky step. Most of the engineering goes into retrieving the right ten pages out of two hundred, then checking each extracted field against the page it came from. A wrong number in a loan file costs far more than the tokens that produced it, and that check costs the same at any token price.
What the cuts do change is the budget for a second opinion. Sending the hard pages through a bigger model, or through the same model twice, used to be a trade-off and is now cheap enough to be the default.
If you run extraction in production, what share of the bill is the model call?

The article: https://minimaxir.com/2026/10/cheap-llms and the thread: https://news.ycombinator.com/item?id=50236102
minimaxir.com
OpenAI and Anthropic cut their LLM prices by up to 80% within a few months. Why?
What is “the true cost of a token”?

The 80% token cut barely moving pipeline cost matches what I see in clinic document work too. Pulling the right pages and verifying each extracted field against its source still dwarfs the model call. Cheaper tokens do make a second-model check on low-confidence fields...
The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started



Related posts

SaaS MVP Scope & Cost Estimator | Lead Qualification & Intake System
The Challenge: Early-stage SaaS founders and product agencies often waste weeks navigating manual inquiry cycles and discovery calls just to map out MVP requirements and sprint budgets.
The Solution: I designed and built an interactive MVP Scoping Engine. This system enables founders to select required platform features—such as multi-tenant authentication, recurring subscription billing, AI API integrations, and admin role permissions—and receive real-time cost and timeline estimates instantly.
Key Features:
Dynamic real-time pricing and sprint timeline calculator
Categorized feature selector (Auth, Core Plumbing, AI, Admin Ops)
Automated MVP Production Brief generation for instant lead qualification


Turning the first discovery call into a 60 second flow is a smart idea. In my experience founders tend to tick every feature so the estimate jumps. A short note next to each option on how it changes the timeline could keep the scope realistic. How close have the price ranges been to real quotes so far?

I run a SaaS business. As founders we're often too immersed into our product and can overlook what real people need to hear. A few hurtful patterns that keep showing up in websites, and how to fix them:
Focusing on the features, not the value:
❌ “Automated bank reconciliation engine”
✅ “Close the books on the 2nd, not the 12th.”
Features matter to someone already comparing options. Everyone else needs to recognize their own problem first, then see it solved.
Big words that could belong to any company:
❌ “Seamless. Powerful. Built to scale.”
✅ “Payroll for 40 people in ten minutes, not an afternoon"
Unverifiable claims:
❌ “Trusted by leading clinics”
✅ “No-shows down 30% across 200 clinics”
What’s the vaguest headline spotted this week? Drop it below 👇
One I keep seeing on AI tools is "Supercharge your workflow with AI." It says nothing. Something like "Turn a 40 minute sales call into a follow up email in 2 minutes" does far more work. Your before and after examples make the point very clear.

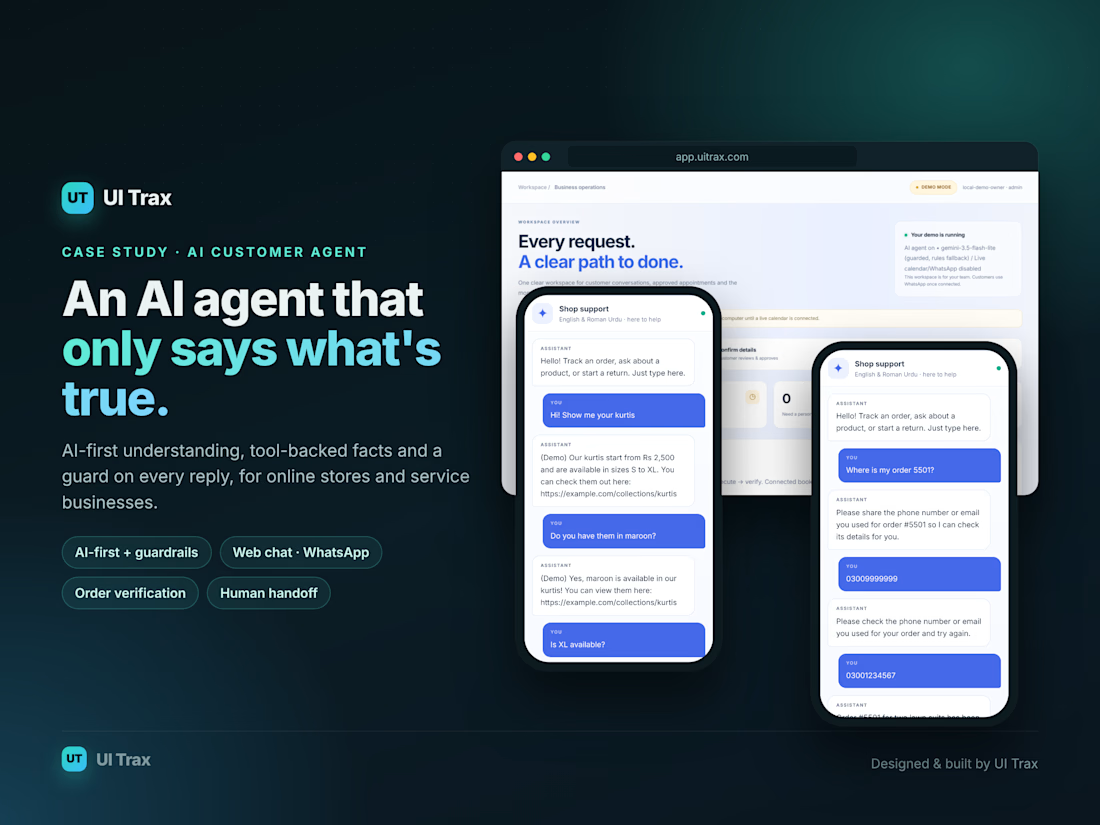
Worth a read if you're building AI support for e-commerce.
UI Trax gets the hard parts right: answers grounded in real store data, order lookups only after verification, a guard on every reply, and a clean handoff to humans with an AI summary.
Reliable AI agents come from architecture, not just prompts. This case study shows it.
#AIAgents #Ecommerce #CustomerSupport #AI
Check it out
The verification step before an order lookup caught my attention. For patient intake, I would similarly verify identity before retrieving records and limit the handoff summary to what staff need. I would also flag uncertainty rather than presenting an unverified summary as fact.