The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost


Annotated CT scan medical imaging datasets used to train AI models for healthcare diagnostics and medical image analysis.
The project involved identifying and labeling anatomical regions within CT scan images using bounding boxes and segmentation techniques to support machine learning model training.
Key tasks included:
• Medical image annotation and region labeling
• Bounding box annotation for anatomical structures
• Dataset preparation for AI model training
• Quality control and annotation validation
This work supports the development of AI systems used in healthcare diagnostics, medical imaging analysis, and clinical decision support systems.


The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Related posts

My Recraft ai submission

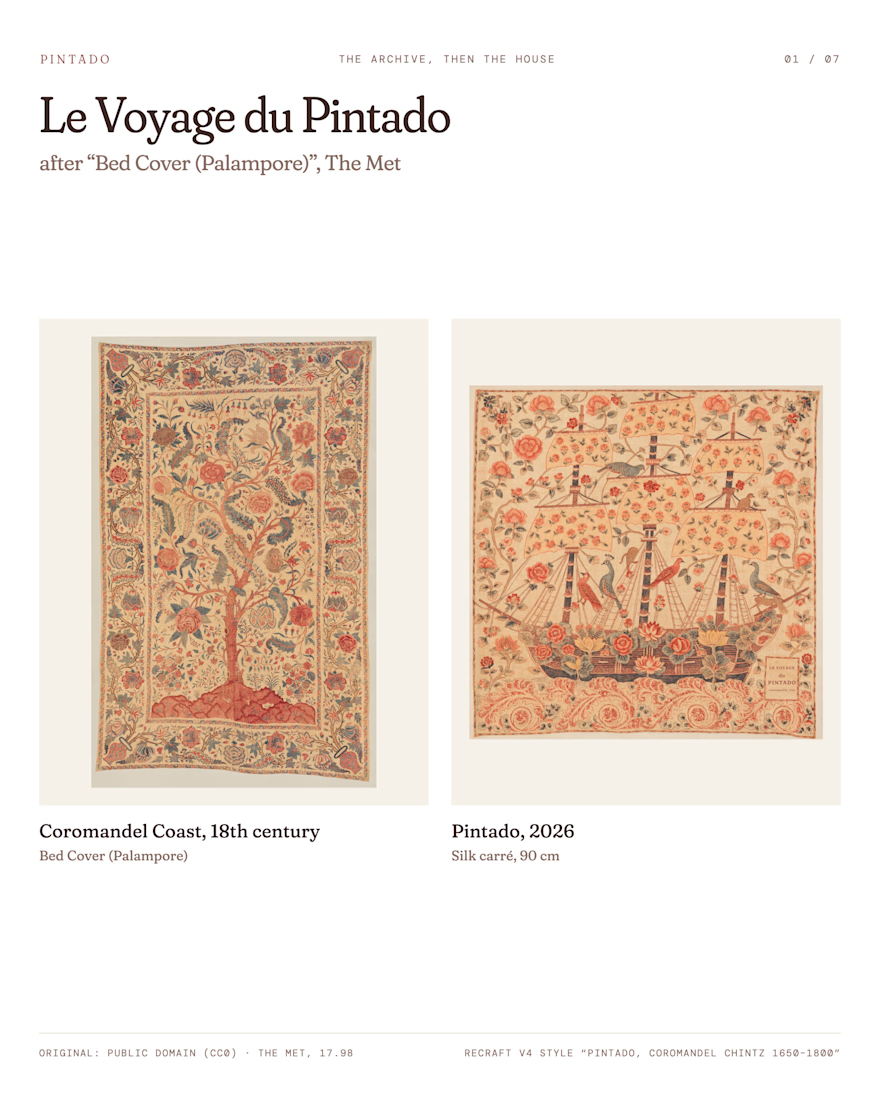
PINTADO: the cloth Europe banned for being too beautiful, reborn as a luxury house.
Between 1650 and 1800, painters on India's Coromandel Coast drew cotton by hand and dyed it in madder and indigo. France banned it in 1686. I trained a Recraft Style on these cloths and asked what...

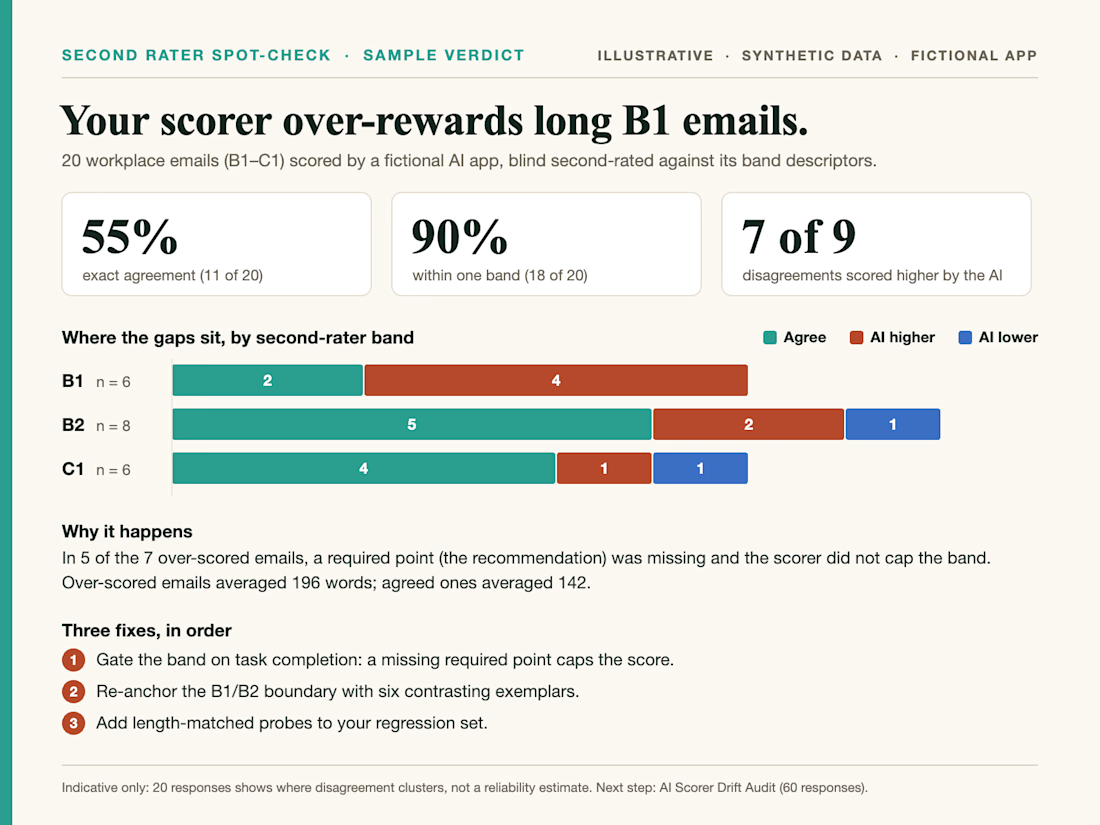
Second Rater notes #1: an AI scorer can agree with examiners on average and still be wrong in one predictable place.
In this illustrative Spot-Check (fictional app, synthetic data), the scorer matched a blind second rater on 11 of 20 workplace emails. Seven of the nine disagreements went the same way: the AI scored higher, mostly at B1, where long, fluent emails skipped a required recommendation and still earned B2.
The fix is not a new model. It is a task-completion gate, a re-anchored B1/B2 boundary and length-matched probes in the regression set.
Full one-page verdict: https://contra.com/p/cYkPrW62-second-rater-spot-check-sample-verdict-synthetic-data
If you run an AI tutor or scorer and want to know where yours drifts, the Second Rater Spot-Check takes five days.

ScanFit AI is a mobile-first web application built with React, TypeScript, and Tailwind CSS that identifies gym equipment in 3 seconds and generates instant setup guides.


"Hey everyone! Really appreciate the feedback on ScanFit . I built this mobile-first web app using React, TypeScript, and Tailwind CSS to solve a real everyday problem on the gym floor—instant equipment identification and setup guides in seconds! Let me know what features you'd like to see added next!"