The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost
Know it all, with your own company brain.
Introducing Theia. Built with the team on HydraDB to bring high-precision, graph-native intelligence to your enterprise data.
It addresses the fundamental failure modes of traditional vector RAG by unifying dense semantic vector search with graph-native identity resolution, reified topic ontology, and temporal conflict supersession.
You can check it out here: Github: Theia


We couldn't do more because of deadline, the system should be working.
Visual and all, it's all thanks to our GOAT Designer @Vibhansh Alok
The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started

Challenges
View all


Related posts

Enterprise RAG AI: Private Doc Intelligence
A fast-growing B2B software firm needed a secure, enterprise-grade Retrieval-Augmented Generation (RAG) system to query thousands of confidential internal documents (legal contracts, technical architecture specs, Notion pages, and employee SOPs) in real time without third-party data leakage.
Key Challenges:
High hallucination risk and irrelevant context retrieval using standard keyword search.
Managing multi-format files (scanned PDFs, tables, markdown) with strict access control based on user hierarchy.
Technical Implementation & Solution:
• Engineered an automated ingestion pipeline in Python with LlamaIndex and LangChain for semantic chunking and metadata preservation.
• Integrated a hybrid vector search architecture pairing dense embeddings (OpenAI text-embedding-3) with sparse BM25 indexing in Qdrant.
• Added a cross-encoder re-ranking layer (Cohere Re-ranker) to prune low-relevance chunks, reducing API token costs by 40%.
• Built robust Role-Based Access Control (RBAC) via FastAPI endpoints, ensuring departmental data isolation.
Results & Impact:
• Dropped internal information retrieval time from 20 minutes to under 4 seconds.
• Attained 98% factual precision with traceable in-line page citations.
• Full on-prem Docker deployment ensuring 100% private data security.



I'd test revoking a user's document access mid-conversation. In your RBAC flow, do cached retrieval results get rechecked against current permissions before they're sent to the reranker or model?

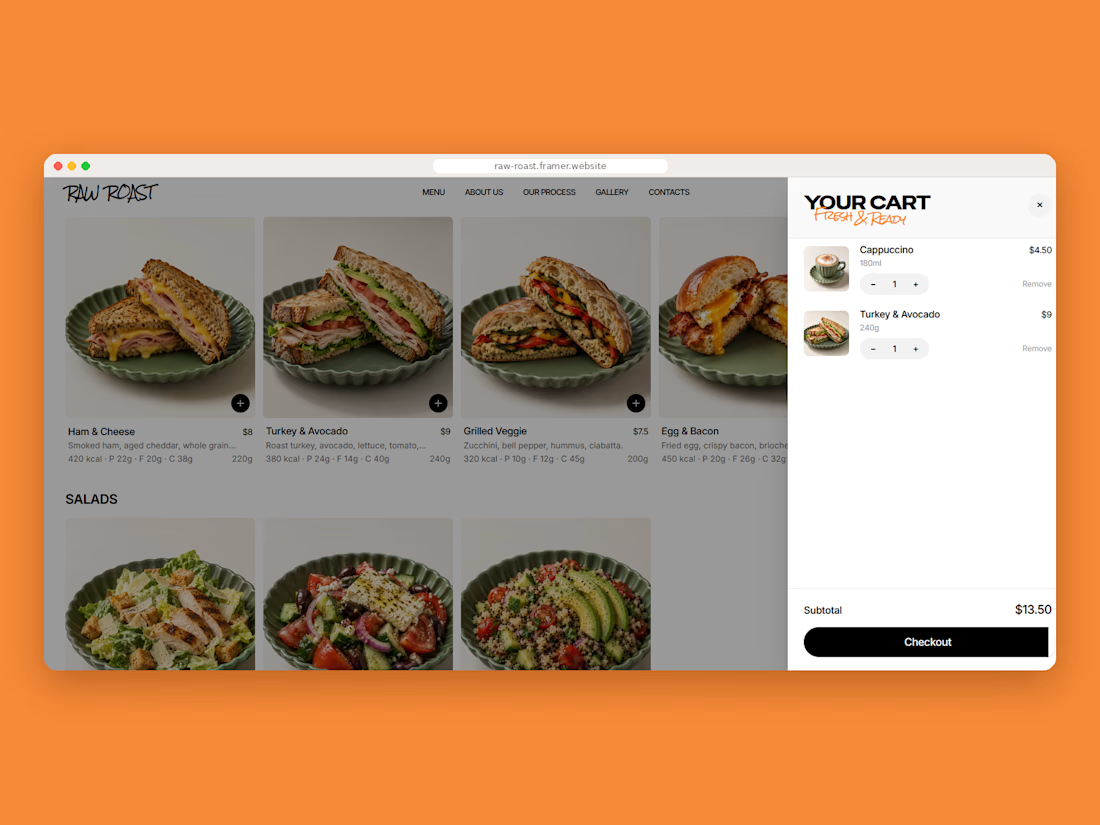
I published my first Framer template. It’s free.
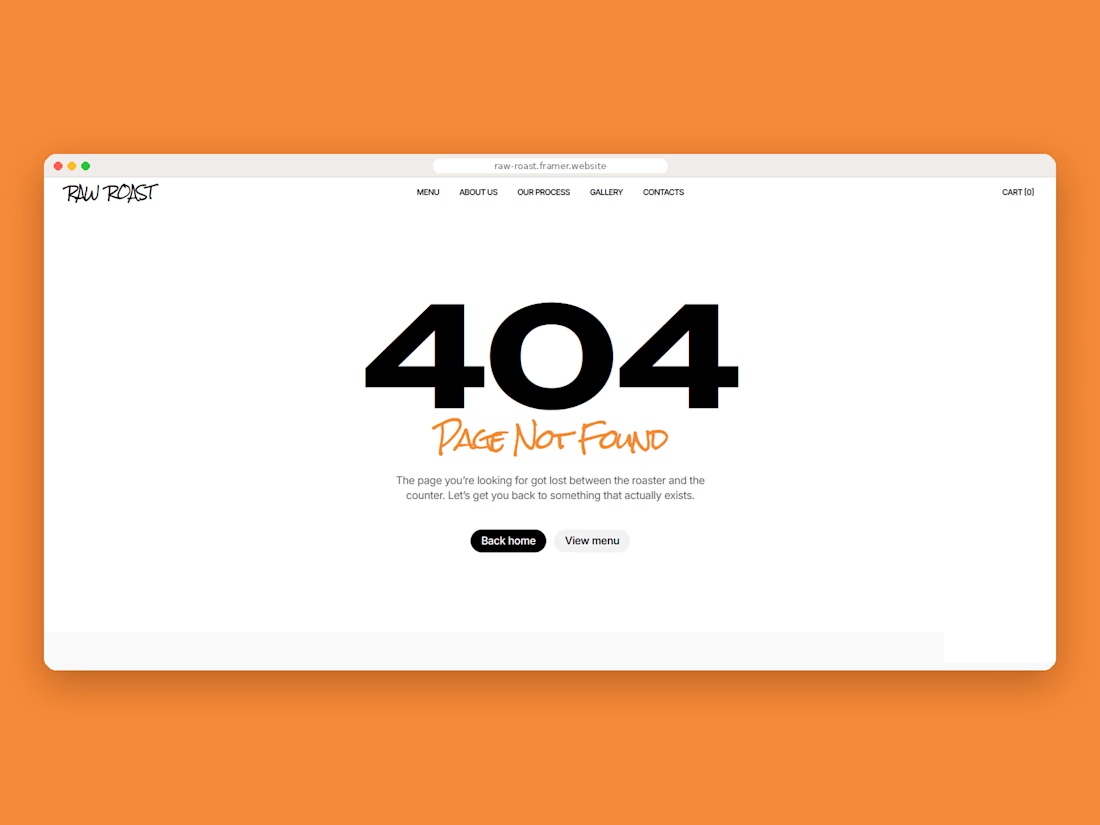
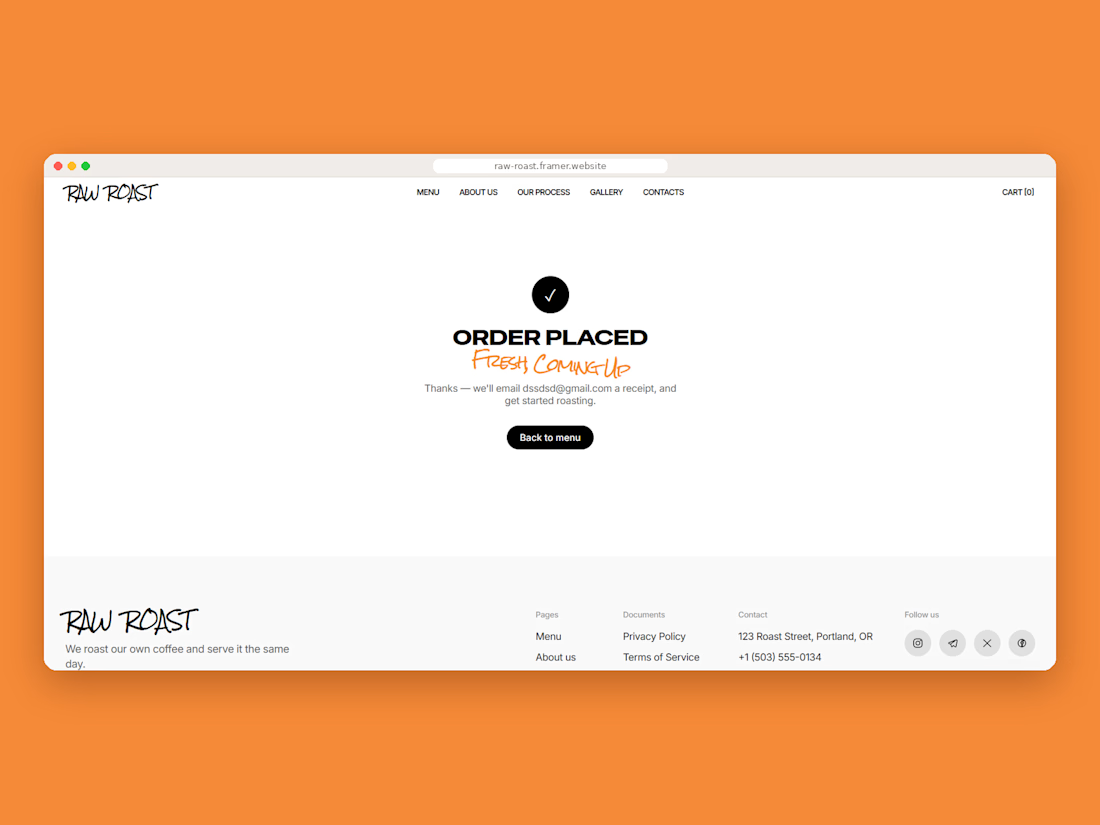
Raw Roast is a site for a coffee shop that roasts its own beans. The style is street-like: big hand-drawn lettering and black-and-white doodles.
What’s in it:
Home, About, Our Process, Gallery, CMS-based menu, Item page, Cart, 404, 401 and legal pages, Desktop, tablet and phone layout.
Links
Template in Framer: https://www.framer.com/marketplace/templates/raw-roast/
Live preview: https://raw-roast.framer.website/
Feel free to use it and change it for your own shop. If you do, I’d be glad to see the result.😍



Crisp, clean, and effective.

My Ai avatar and video demo. I am loving my Ai skills . Ai makes my work faster and seamless.