The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

Showcasing how recent video engines can transform old photos into cinematic memories.
Even more impressive, the restoration can be done on sources with high level of tear and damage.


This is AI at its best. Bringing precious memories back to life and letting us relive those moments in a whole new way.

The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started


Challenges
View all


Related posts

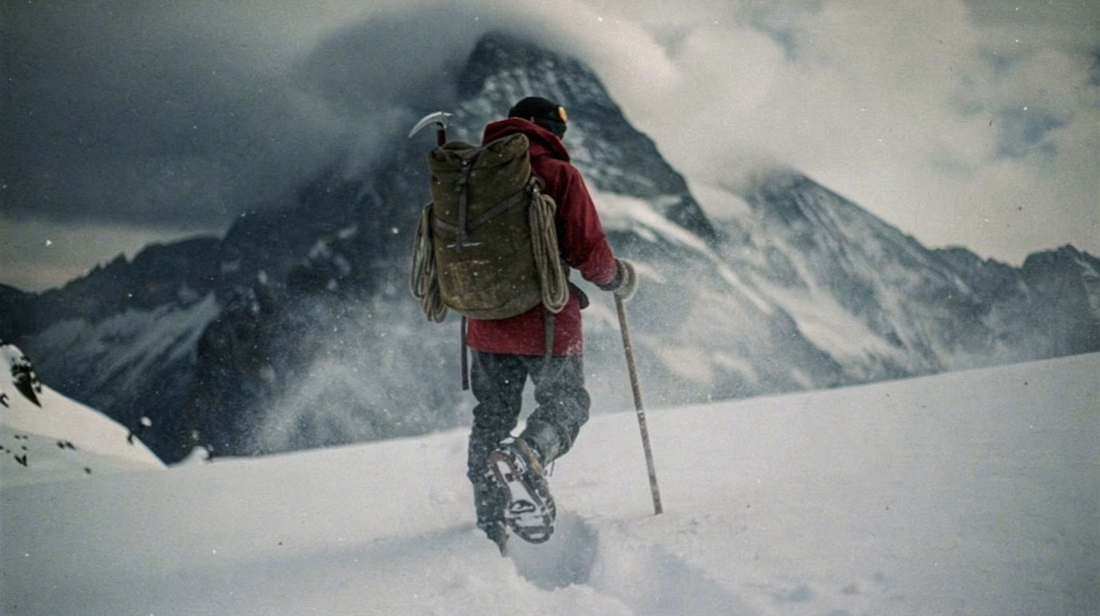
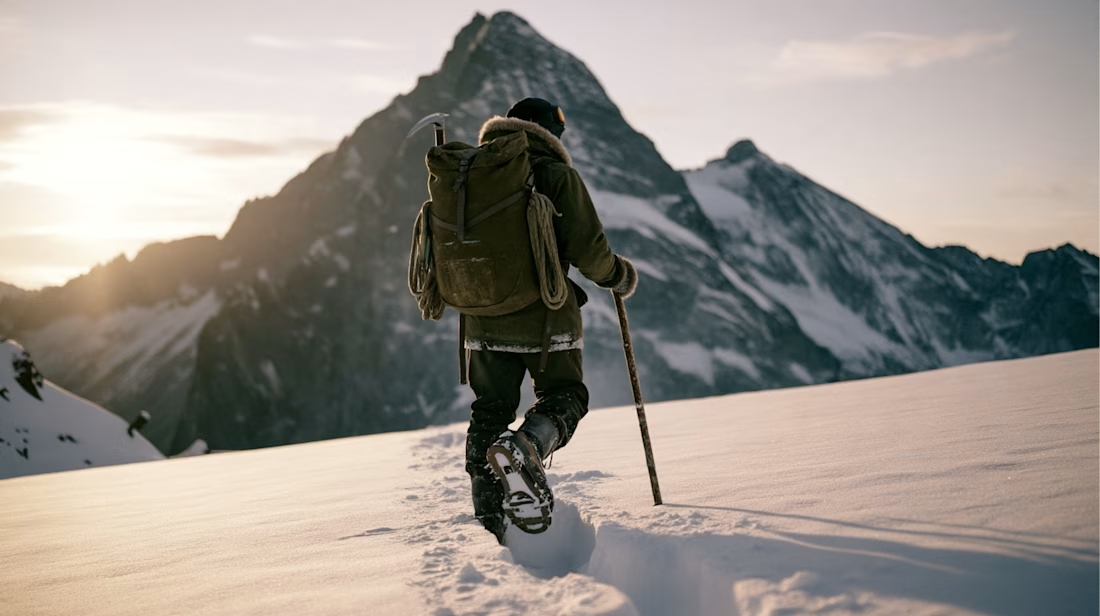
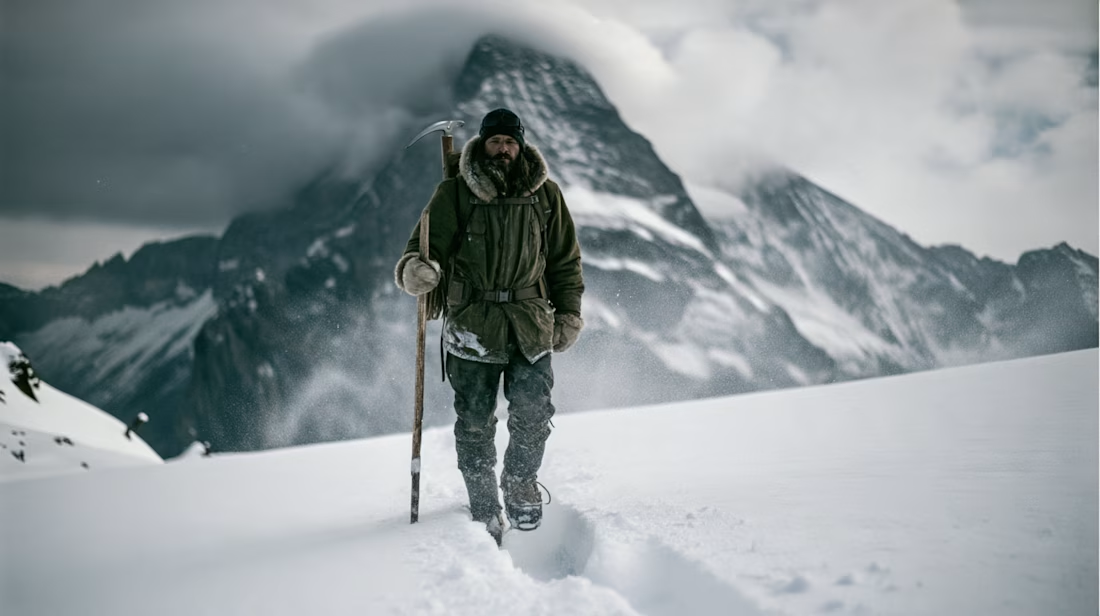
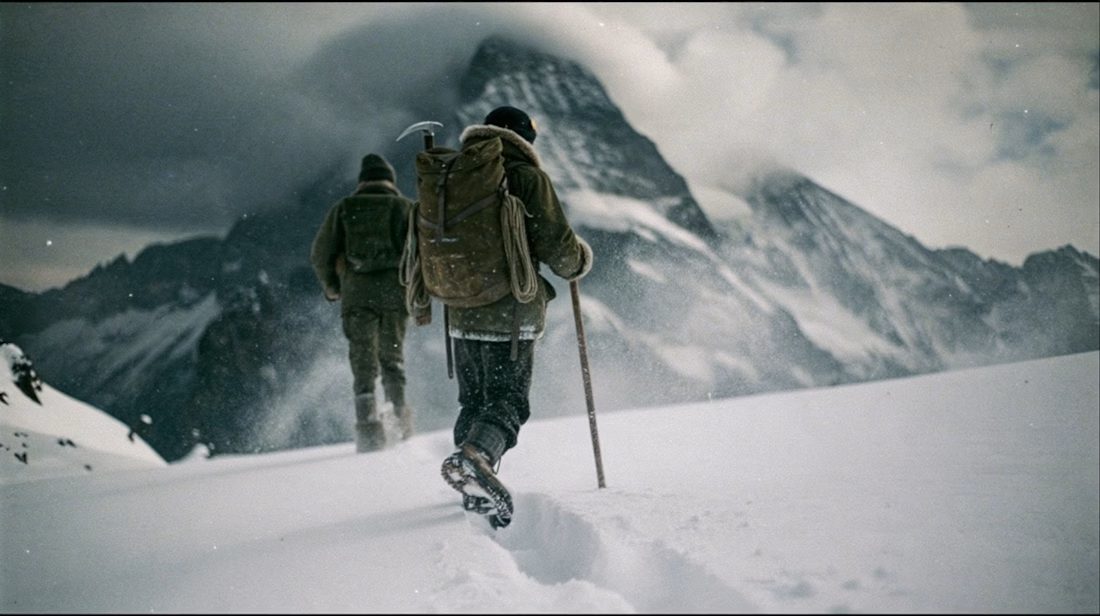
What happens when you take a hero frame from an AI-generated video and push it back into an image edit model?
This weekend I took a still from a recent Seedance 2.5 piece I made —depicting a solo mountaineer in a harsh alpine environment — and ran it through Midjourney's new v8.2 edit model to see how far I could iterate on a single frame without regenerating from scratch.
Tested wardrobe swaps, environment shifts, and style transfers.
Video walkthrough of the process coming in a separate post.


This looks cool

Recent design project. The cube was created in Midjourney, refined and cleaned up in Photoshop (yeah), video generated in Google Flow. Interface and icon animations made with Figma. I hope it works okay for iPhone Duo too.
I still can’t seem to master the whole “design in one prompt” thing. What am I doing wrong? /s


Creative approach

Loved seeing what Vision Engine can create. Designed this final CTA section using Vision Engine, the results turned out beautifully! ✨
Hope you like it :)

