The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

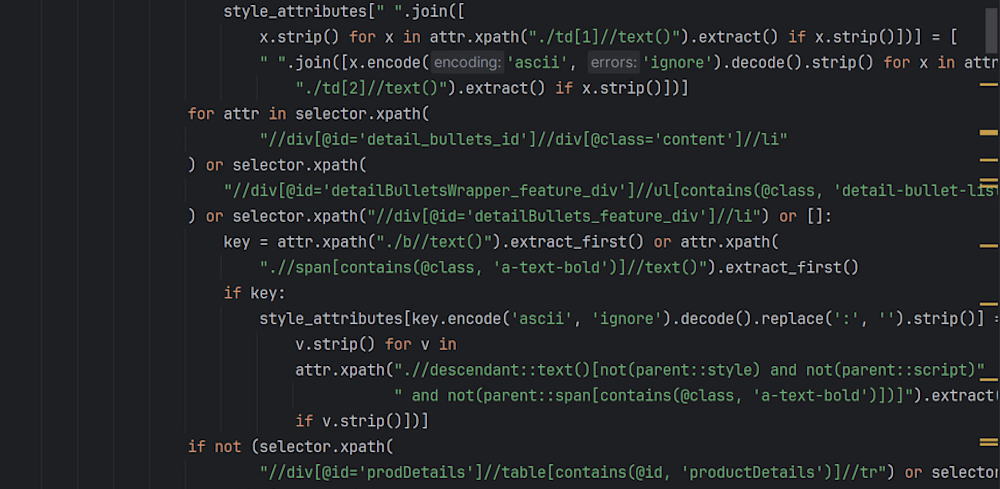
Built a Python-based web scraping system that automates the extraction of book data from a multi-page online catalog.
The scraper efficiently navigates paginated pages, collects product links, extracts structured information, and exports clean datasets in both CSV and JSON formats.
Key Features:
• Automatic pagination handling • Category-based filtering • Keyword search functionality • Retry mechanisms for failed requests • Robust error handling • Structured data export for analysis and integration
Extracted Data:
• Book title • Price • Rating • Availability status • Product description • Category • Product URL
Tech Stack:
Python | Requests | BeautifulSoup | CSV | JSON
This project strengthened my understanding of web scraping architecture, data extraction pipelines, HTML parsing, and building resilient automation systems.
#Python #WebScraping #DataExtraction #Automation #BeautifulSoup #Requests #DataEngineering #SoftwareDevelopment #OpenToWork #FreelanceDeveloper


The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started

Challenges
View all


Related posts

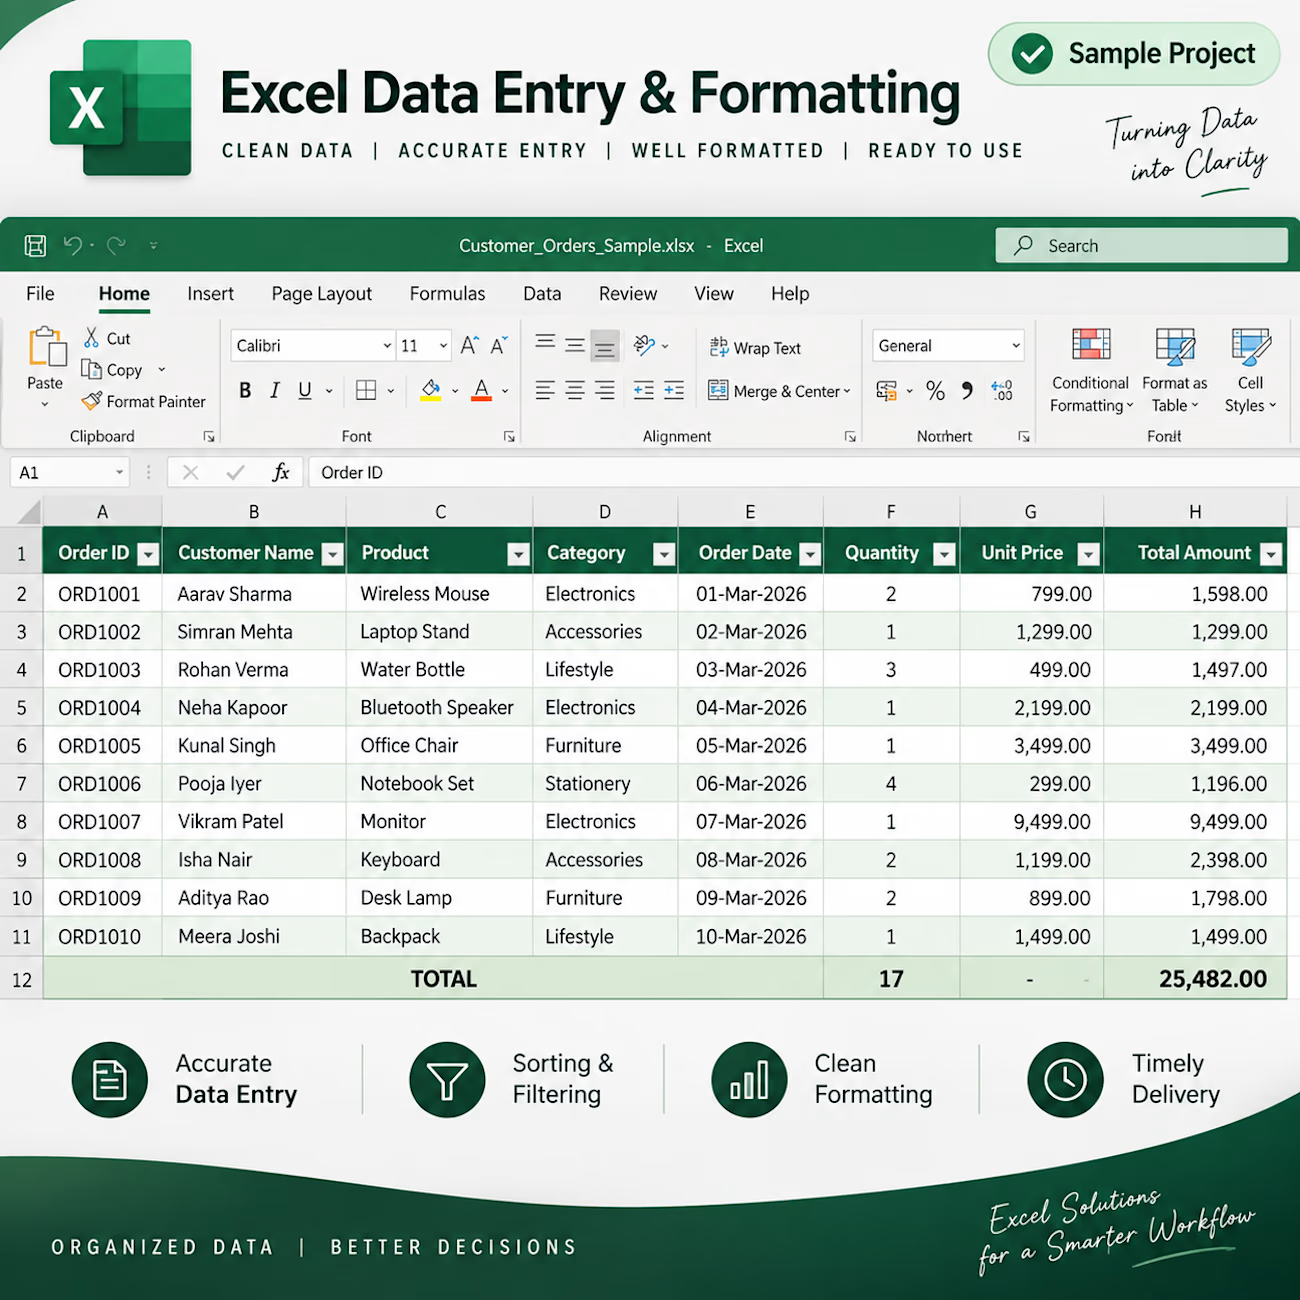
Excel Data Entry & Formatting
Description: Accurate data entry, formatting, sorting, filtering and spreadsheet organization using Microsoft Excel.



Excel ERP System | Sales, Purchase & Inventory Management
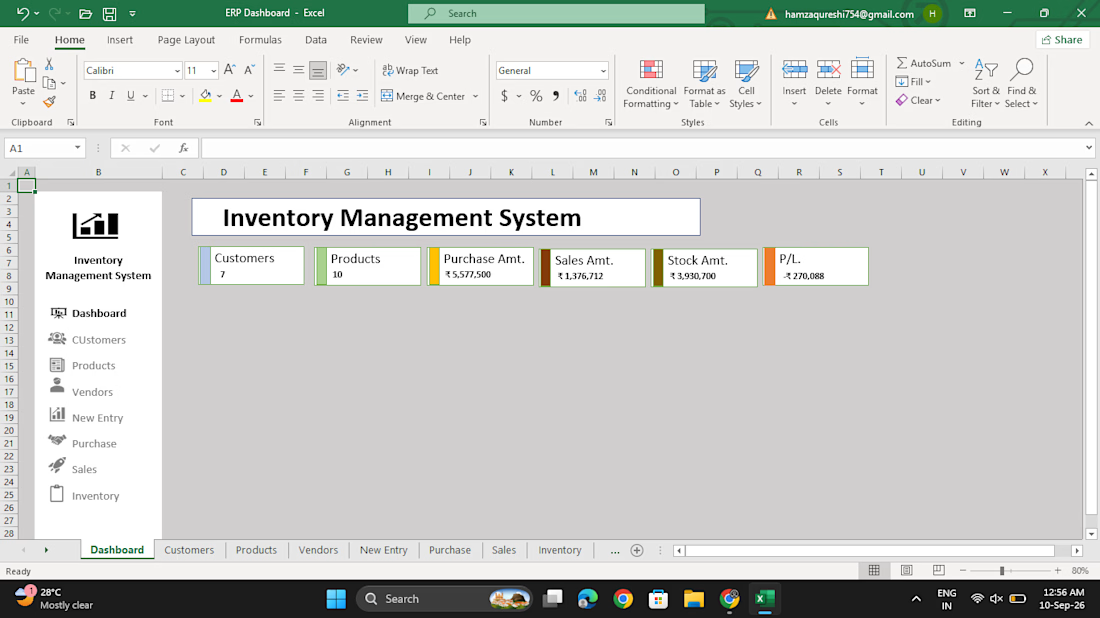
Built a practical Excel-based ERP system to manage customers, products, vendors, purchases, sales, and inventory.
The system automatically tracks purchased and sold quantities, current stock, stock value, sales, purchases, and profit/loss using Excel formulas and Pivot Tables.
Key skills: Excel, VLOOKUP, SUMIF, Pivot Tables, Inventory Management and Business Reporting.:


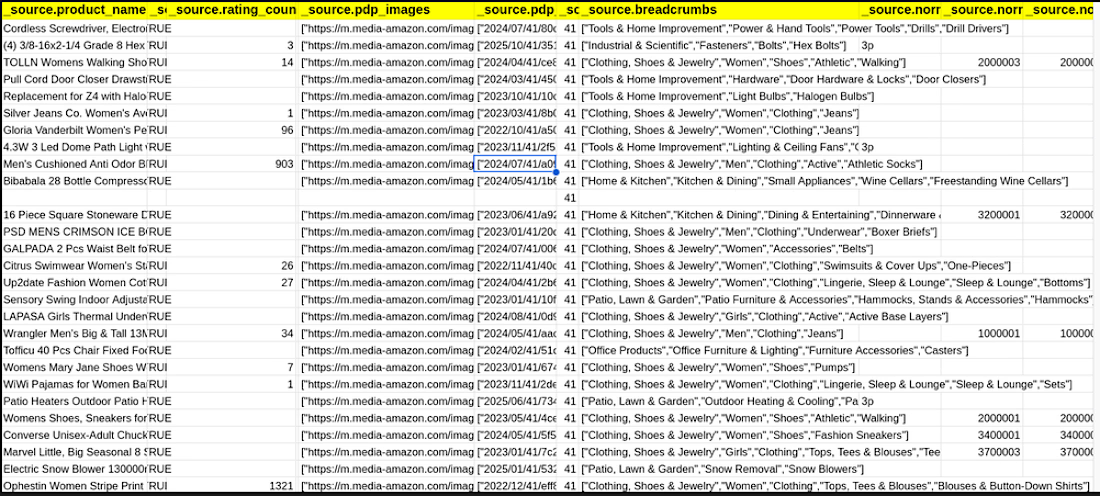
I developed a scalable web scraping solution to extract product data from Amazon based on search keywords and categories. 🔹 Data Extracted: Product Name Price Ratings Number of Reviews Product URL Availability 🔹 Features: Pagination handling (scraping multiple pages) Clean structured output (CSV/Excel) High accuracy and duplicate handling 🔹 Tech Used: Python Scrapy / BeautifulSoup This data can be used for: ✔ Price monitoring ✔ Competitor analysis ✔ Market research I can customize the scraper for any category or large-scale data extraction - https://github.com/shreya-2nov/Sample-Crawlers/blob/main/amazon.py