The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

Hello Builders,
I’ve been working on a RAG project that required a large corpus of legal texts comprising statutes, court rulings, etc.
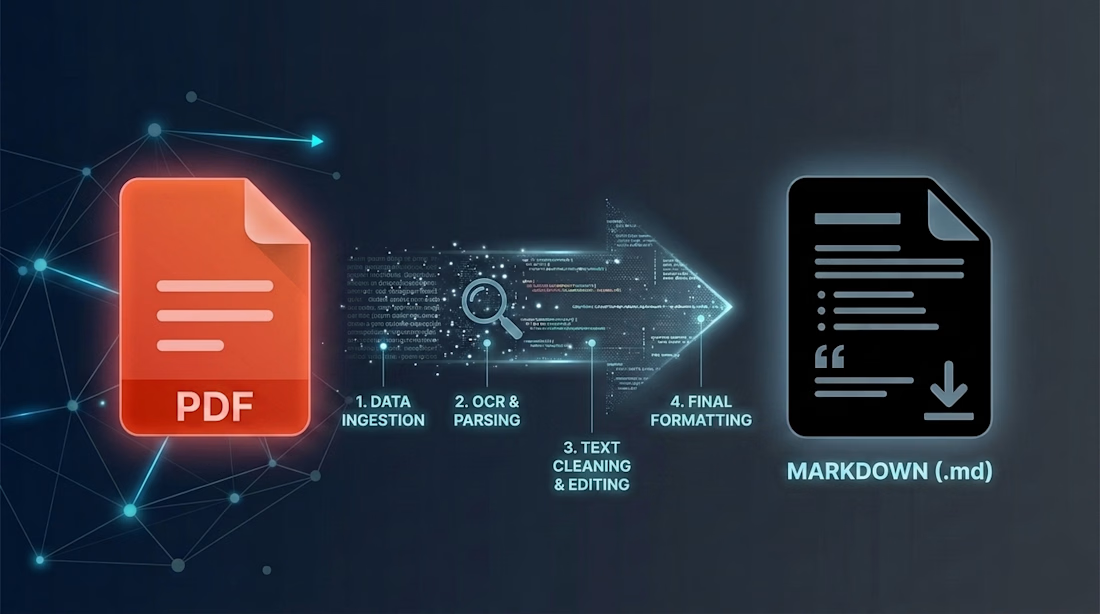
One thing I’ve noticed is that even top-notch OCR/parsers don’t always produce pristine, RAG-ready data. 💯
For high-accuracy retrieval, I’ve found that human QA is valuable for preserving document structure in Markdown/JSON with proper headers, line breaks, indentation, citations, etc., even when using regex/Python scripts.
If you’re building with a legal or other complex corpus, I’m available to help as your expert-in-the-loop.
Happy to connect! 😊
The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started



Related posts


Messy Data In. Clearer Decisions Out. 📊
Over the past year, I've noticed most businesses don't struggle because they lack data — they struggle because that data never turns into a decision.
That's the gap I work in:
→ Cleaning and analyze data with Python & R
→ Turning findings into investor-ready pitch decks
→ Polishing the final write-up so nothing gets lost in translation
If your team has data sitting in spreadsheets with no story attached, or a pitch deck that needs to actually land — that's exactly where I can help.
Open to projects. Let's talk 👇



AI-Powered Document API (RAG) — deployed on Render
FastAPI, PostgreSQL, OpenAI API, React, Docker, GitHub Actions
• Built a RAG backend: PDF ingestion, overlapping chunking, embedding-based retrieval, and OpenAI answers grounded in retrieved chunks, behind JWT auth with response caching.
• Debugged a chain of Render build and runtime failures (memory limits, dependency conflicts, ephemeral disk) and replaced a local FAISS index with PostgreSQL-stored embeddings and NumPy cosine similarity.