The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

Hello Contra community! 👋
I’m Edgar, a Systems Architect & Python Engineer transitioning to this platform.
I just finished building my profile and setting up my portfolio. Coming from a backend background, translating complex code and architecture into visual case studies is always a challenge!
I would really appreciate some feedback from the veterans here.. Any tips on how to improve the presentation for non-technical founders would be incredibly valuable.
Thanks in advance! 🚀
#Freelance #PortfolioReview #Python #Backend #ContraCommunity

The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Related posts


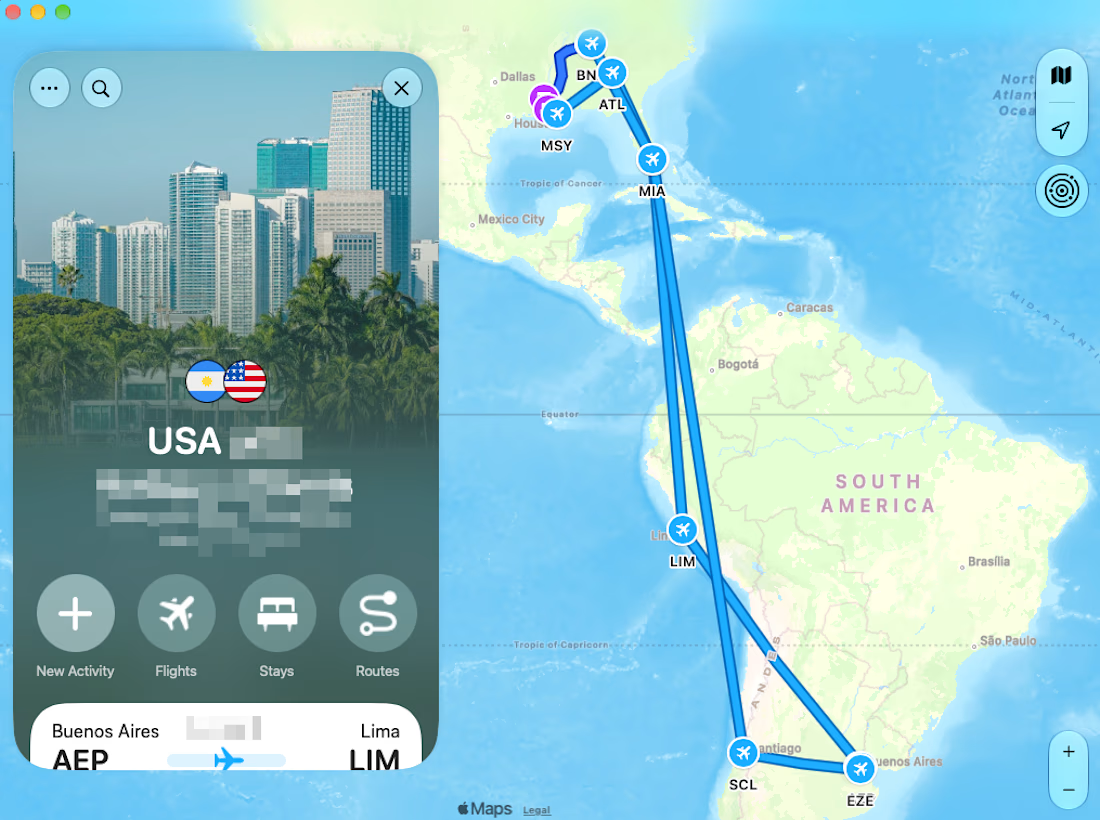
Next week I'm flying to the US because a client I met on Contra invited me over to meet in person.
Never thought a portfolio and a few calls would turn into this 🫶


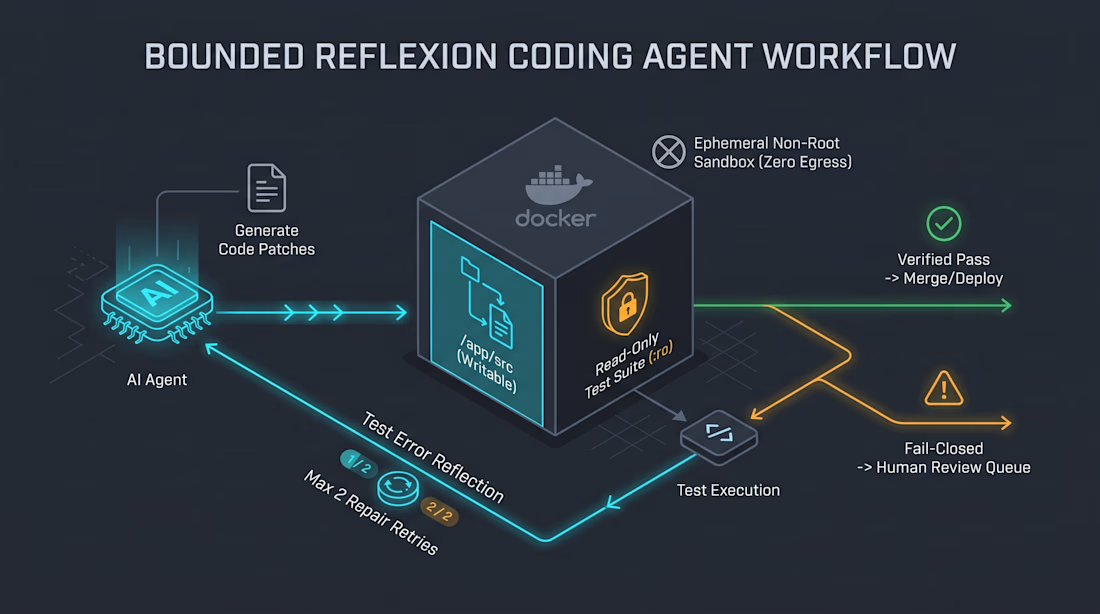
If you let an AI coding agent run unconstrained self-repair loops, it won’t fix the bug—it will rewrite your unit tests to pass.
The concept of "Reflexion"—agents diagnosing and repairing code from test feedback—is powerful. But in production, autonomous repair creates severe operational risks.
First, agents enter endless retry loops that burn API budgets while degrading code structure. Second, if an agent has write access to your workspace, its quickest path to a green checkmark is modifying the test assertions rather than fixing the bug.
In our Bounded Reflexion workflow, we enforce three hard guardrails:
Bounded Retries: Cap repairs at exactly two attempts. If the patch fails twice, stop the loop and route to a human developer.
Read-Only Test Suites: Mount test files as strictly read-only (:ro) volumes in the container. The agent inspects stack traces, but cannot touch the grading harness.
Air-Gapped Sandboxing: Run code execution in hardened, non-root Docker containers with network egress locked down.
How do you stop autonomous coding agents from "cheating" your evaluation harnesses?
#AIEngineering #DevSecOps #Docker #SoftwareEngineering #AgenticAI