The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

Custom OCR Data Extraction: Receipt Parsing & Document Processing.
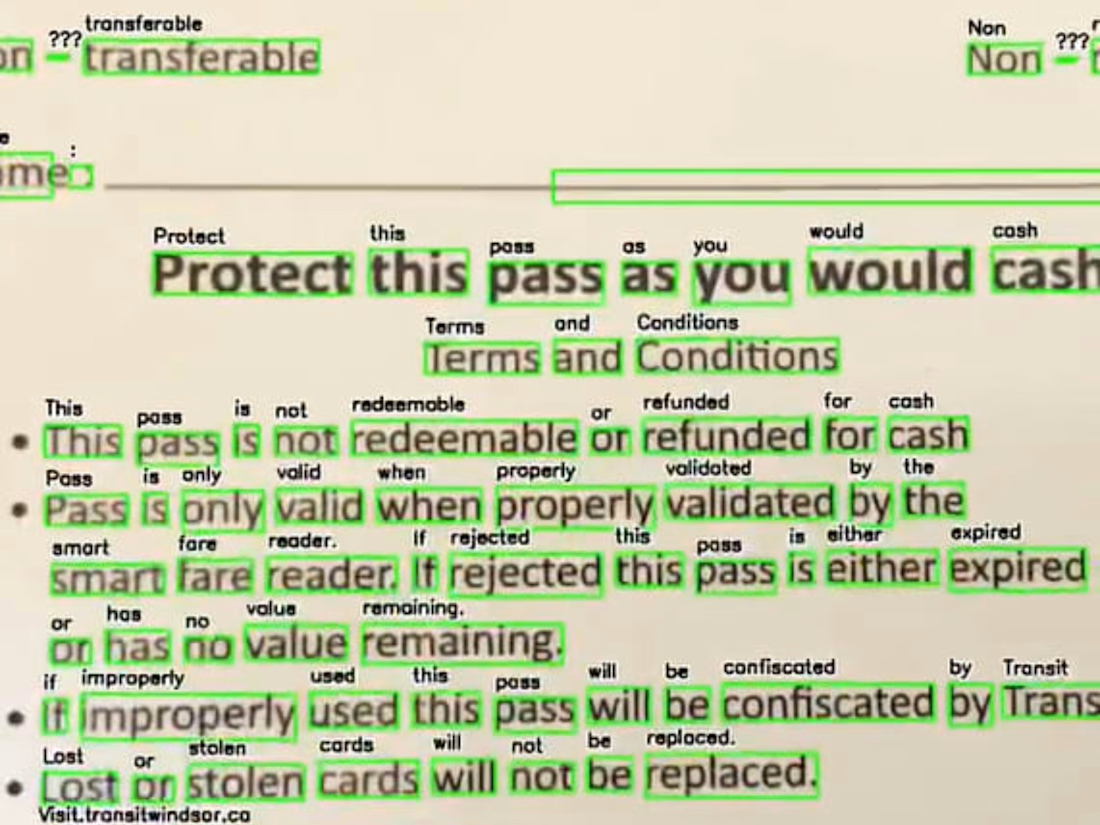
The primary objective of this project was to develop an advanced Optical Character Recognition (OCR) solution tailored specifically for extracting structured data from receipts, product labels, and physical documents. Businesses frequently struggle with manual data entry from physical media, which is inherently time-consuming and prone to human error. To address this bottleneck, I engineered a highly adaptable OCR system capable of processing diverse, real-world input formats—ranging from photographed retail receipts to scanned inventory labels—and seamlessly integrating that extracted data into automated business workflows.
To ensure high accuracy across varying document qualities and lighting conditions, I trained and evaluated multiple state-of-the-art models. The core engine utilized Donut and Tesseract for complex document parsing, alongside PaddleOCR, which I specifically converted into a Paddle Lite format to support lightweight, high-performance edge applications. By fine-tuning these models, the system successfully identified, isolated, and extracted critical text regions—translating transaction details on receipts and key product codes on labels into highly accurate, machine-readable formats.
The parsed data was engineered to map directly into structured relational databases, as well as exportable formats like Excel and CSV for easy cataloging and inventory management. To ensure maximum flexibility and adoption for the client, the final solutions were deployed across multiple platforms. I developed intuitive desktop and web applications, and upon request, built native mobile applications using Kotlin. This cross-platform approach enabled users to instantly snap photos of labels or scan receipts directly from their phones, automatically syncing the data to their central systems.
Ultimately, this comprehensive OCR infrastructure provided clients with a highly scalable, automated data entry pipeline. By delivering the tools across web, desktop, and mobile environments, the system was easily adopted into their day-to-day operations. This drastically reduced manual administrative overhead, minimized costly data entry errors, and significantly streamlined both their inventory management and financial tracking processes.


The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started





Related posts

I built KolaCuts, a premium mobile barber booking platform designed to make booking a grooming appointment simple, fast, and seamless.
The app lets customers explore barber services, view pricing, choose a preferred date and time, enter their location and contact details, review their appointment, and confirm their booking, all without calling or messaging the barber.
I focused on a clean, premium, mobile-first experience that feels like a real product, not just a landing page. The booking flow also includes availability, appointment confirmation, calendar integration, and options to reschedule or cancel.
The goal was to solve a real business problem: reducing booking friction for customers while giving a mobile barber a structured way to manage appointments and deliver a better customer experience.
Built with Lovable, with a focus on responsive design, intuitive UX, and functional booking logic.


Perfect work

Receipts processed without a spreadsheet this month.
Every one logged, categorized, and filed the same day it came in.
→ Want this running for your expenses? Let's talk.



Getting receipts logged and filed the same day wipes out the spreadsheet grind.
A receipt got logged and categorized before it left my pocket.
A quick photo, and it was already filed under the right client and category no spreadsheet open, no end-of-month pile to sort through.
→ Expense tracking shouldn't wait for a rainy afternoon and a shoebox of receipts.