The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

Built evalflow — an open-source pytest-style quality gate for LLMs. Catches prompt regressions before production by diffing live outputs against a saved baseline. Live on PyPI. github.com/emartai/evalflow


The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started



Related posts

End-to-end retail analytics pipeline that turns raw, messy CSV exports into business decisions, built in Python and SQL and runnable with one command.
What it does:
Cleans and validates 6 relational tables, fixes 585 data-quality issues and logs every action
Loads a SQLite warehouse with keys, constraints and window-function SQL
Customer analytics: RFM segmentation, cohort retention, CAC / LTV by channel, product Pareto, market-basket analysis
Churn prediction model validated on future data (ROC-AUC 0.71, no data leakage)
6-month revenue forecast, best of 3 models by backtest (4.2% MAPE)
Auto-generated Excel report (live formulas, native charts) and an interactive Streamlit dashboard
18 automated tests




The fix for an agent that keeps getting your design system wrong isn't a better prompt.
It's putting the rules where the agent reads them.
In the repo. In skills. In checks it can run itself.
Writing a course about exactly this.

What sells it for me is the refusal telling the agent exactly where the token should go. A bare "no hex" error usually just sends it looping. Does guard.mjs run only as an agent hook, or in pre-commit too so it catches humans as well?

Hello Contra community! 👋
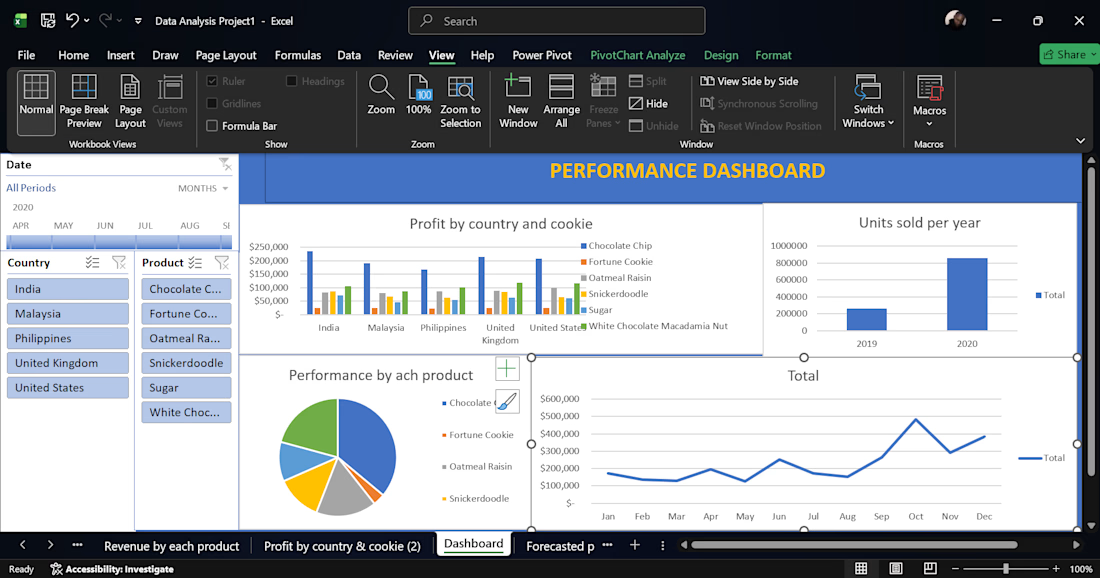
I'm Emmanuel, an aspiring Data Analyst passionate about turning raw data into meaningful insights.
I'm currently building my skills in:
Excel and Power BI for data visualization and reporting.
SQL for data querying and analysis.
Python (Pandas, Matplotlib and Scikit-learn) for data cleaning, analysis and machine learning.
I'm using practical projects to strengthen my skills and explore how data can help businesses make better decisions.
Looking forward to connecting, learning and collaborating with other professionals here!