The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

Fraud Analyst | Transaction Monitoring & BEC Detection | SQL | Remote
The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started










Related posts

Retail Fraud Analysis
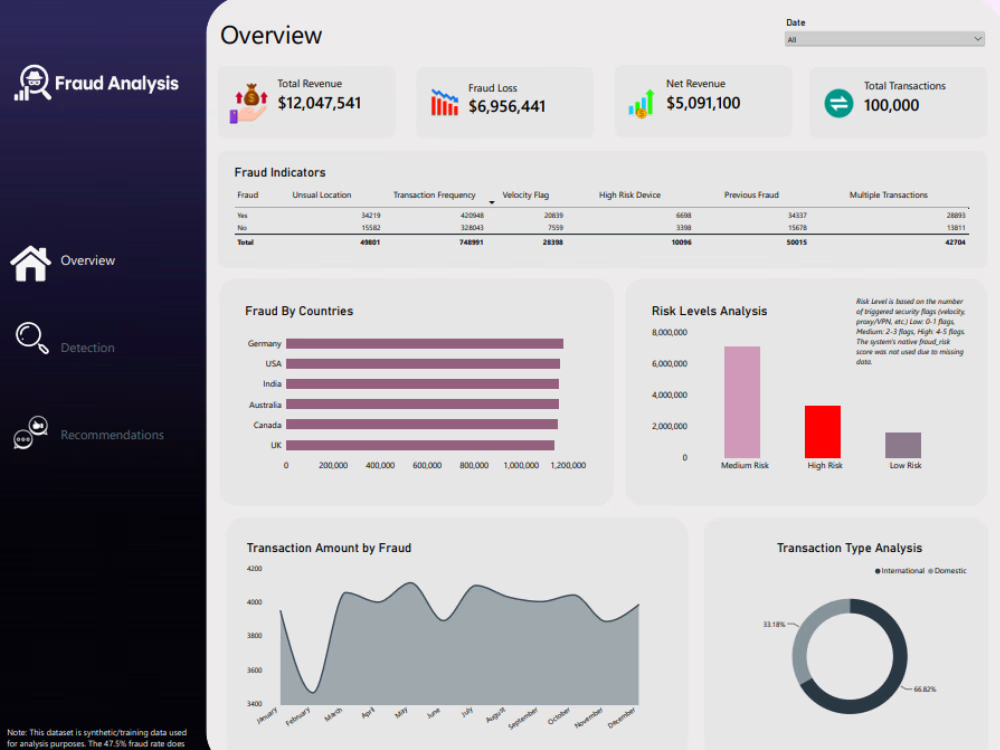
Retail businesses need to detect fraud without unnecessarily flagging legitimate transactions. I built this project using 100,000 retail transactions to explore fraud patterns and identify where financial risk was concentrated.
During data exploration, I found that the original fraud-risk score was stuck at 0.0 across all records, while two location fields contained duplicate information. Rather than inventing a score, I created transparent Low, Medium, and High risk classifications using available security indicators, including transaction velocity, proxy/VPN usage, and high-risk devices.
I used SQL to clean and prepare the data, then built an interactive Power BI dashboard covering the overall picture, fraud detection, and recommendations.
One key finding was that medium-risk transactions represented approximately $7.1 million in financial exposure, compared with $3.3 million for high-risk transactions. The analysis also showed that fraud activity was concentrated in lower transaction-value brackets.
The overview below shows the project, while the full analysis is available on GitHub.



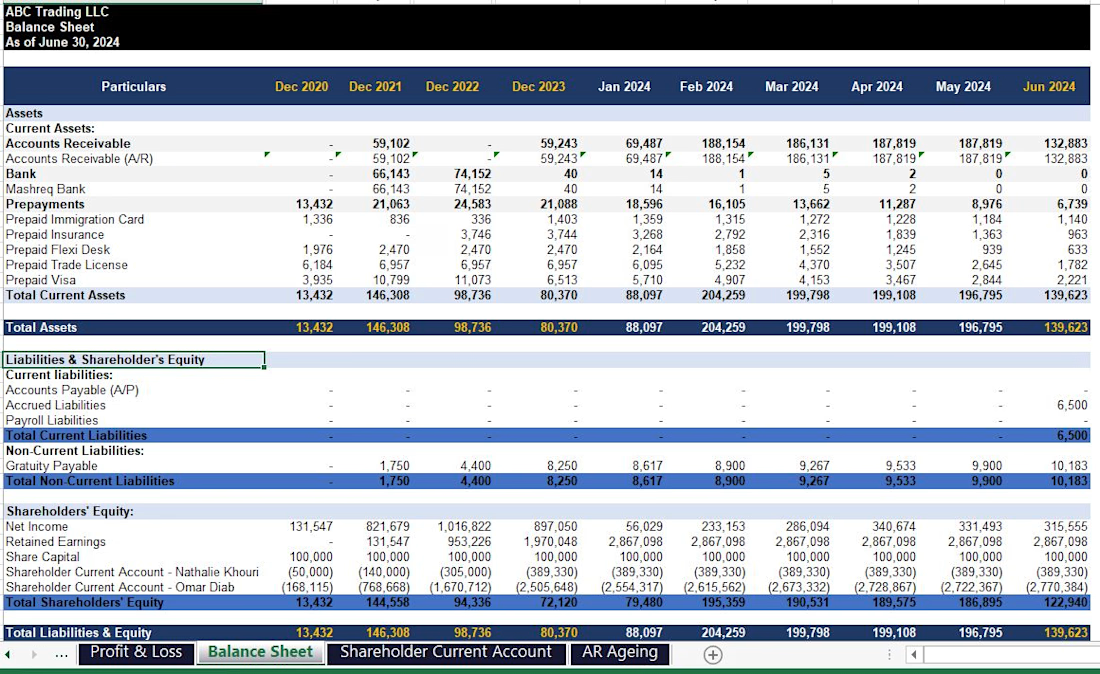
Developed a management accounts reporting process designed to help businesses understand their financial performance and make informed business decisions.


Great work ,keep it up

Title: Nexa Electronics: Premium E-Commerce Website with Interactive 3D Exploded Views
Description:
Nexa Electronics is a demo e-commerce website I designed and built to show my skills in modern web design, front-end development and interactive 3D experiences. This video is a walkthrough of the site.
What’s in the vedio.
The home page, with a cinematic hero section and a 3D device showcase
Browsing by category: Smartphones, Laptops, Audio, Gaming, Smartwatches, Smart Home and Accessories
Product pages with configuration and colour options, a zoom inspection view, pricing, stock status and customer reviews
The interactive 3D exploded view (“Explore Inside in 3D”), where you can take products apart layer by layer to see their internal components
Quick View, the device comparison matrix, the shopping bag and a full checkout flow (shipping details, payment, order review and confirmation)
Customer sign-in and an admin dashboard for managing the store
Website features
Interactive 3D exploded views of products, with labelled internal parts and an explode slider
A mega-menu navigation and fast category browsing
Product configuration (storage and colour variants) with live pricing
Wishlist, compare and shopping bag functionality
Device comparison matrix
A simulated checkout with order confirmation
Customer accounts (sign-in)
An admin dashboard with store stats and inventory and price management
A newsletter signup section
A toggle to turn the 3D experience on or off
A responsive, dark and light themed premium UI
Note: I made this video with the help of AI, and it is just a demo to show my skills. To see my work properly, I recommend visiting live website.