The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

The problem
Teams often get over a thousand alerts a day. Real incidents get buried, on-call engineers burn out, and nobody trusts the dashboards.
What I do
Audit existing alerts and find the noisy, duplicate and non-actionable ones
Rebuild alerting around SLOs (availability, latency, error rate)
Design one clear dashboard: key metrics, latency percentiles, error budget, and active problems with root cause
Sample result shown in the video (demo data)
Alerts per day: 1,284 → 12 actionable
Availability: 97.8% → 99.95%
p95 latency: 842 ms → 187 ms
Error rate: 4.8% → 0.21%
Good fit if you
Run a production service and feel alert fatigue
Use Dynatrace or a similar APM tool and want better dashboards
Need a clear fix plan, not just a report
Message me with your stack and your biggest alerting pain, and I’ll reply with a quick plan.

The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started



Related posts

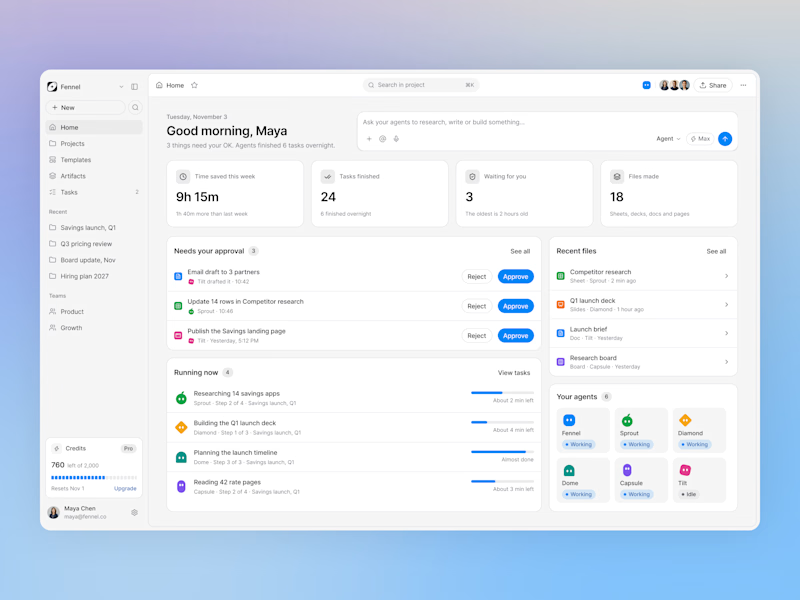
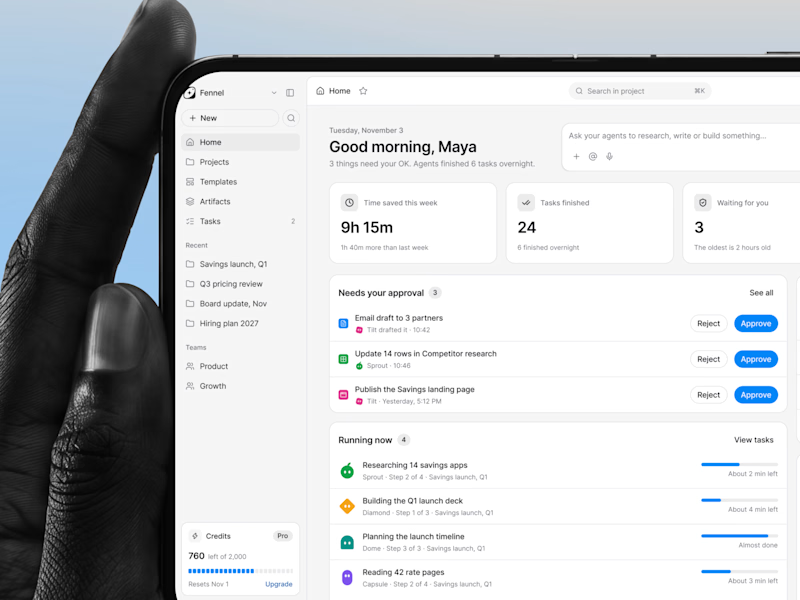
Designed an AI agents dashboard where you approve work, track running tasks, and see your whole team of agents in one place.
Same screen, two shots. Which one would stop your scroll? 👀


1 voted
50%
1 voted
50%
2 votes
Closed

nice one dude

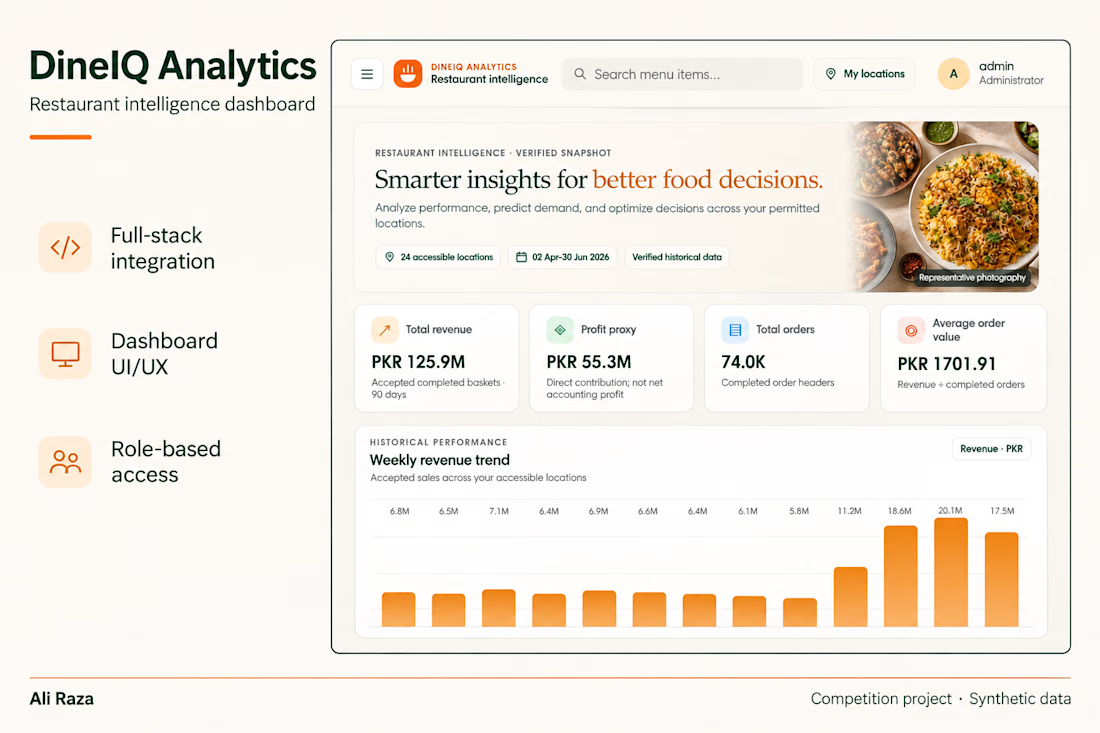
Your best-selling dish could be losing you money.
That insight shaped my dashboard work on DineIQ, a restaurant analytics competition project.
My challenge: turn complex analytics into clear, useful views. I approached it with focused Django dashboards, practical filters, and role-based access—helping managers explore their location’s menu performance and wastage together.
My role covered full-stack integration, UI/UX, dashboards, and architecture. Built with synthetic competition data, DineIQ illustrates why sales volume alone doesn’t tell the full story.
Better decisions start with better visibility.
#FullStackDevelopment #Django #DataAnalytics




Amazing work