The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

AI agents read web pages, tickets and files, and any of them can hide instructions. That's prompt injection, the #1 risk in the OWASP Top 10 for LLM Applications.
I built a policy layer that sits between an agent and its tools and stops those instructions from turning into actions. Five deterministic rules, no prompt tricks: tool allowlists, read scope, write confinement, egress pinning and sink provenance.
Then I attacked it. On an agent that obeyed 43% of injection attacks, the rules cut successful attacks to 0 out of 60, across all five attack goals: stealing a secret, phoning home, poisoning files, planting a payment IBAN and moving customer data. They held on Claude Haiku 5.5 too, with zero false blocks, and on the AgentDojo benchmark they cut worst-case attack success from 98% to 3.1%.
Every number comes from logged runs with 95% confidence intervals.
Want the same for your agent? I map its tools, attack it with your own workflows, write the policy and hand back a before/after attack rate.
#AIAgents #AgentSecurity #AISecurity #PromptInjection #LLMSecurity #GenAI #LLM #AIEngineer #MCP #ModelContextProtocol #Claude #Anthropic #RedTeaming #CyberSecurity #Python #AIAutomation


The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started



Related posts

Did a motion for the Cockpit concept ⁕ 🔈 ON
Design & Creative Direction: Me
Motion & Sound: Claude Code
Cockpit is an AI agent management platform concept that helps teams:
- Set boundaries
- Monitor activity
- Manage approvals
- Track knowledge sources
- Measure performance and costs
It brings together five key AI UX challenges:
👉 Autonomy
👉 Observability
👉 Human Approvals
👉 Context
👉 Analytics
The idea is simple:
As AI agents become more capable, the experiences we design around them need to make their actions more transparent, predictable, and manageable.
Thanks!


Human approvals is the part most agent UIs skip. Good call making it one of the five challenges.

Weekend fun 😺. The new MacBook Pro has a Dynamic Island, and I kept wondering: what if that little pill was where your AI agent lived?
Try it live: https://lab.behzad.me/agent-mew/
So I spent the weekend prototyping Agent Mew. You drop a file on the notch, give it a task, and it quietly works up there while you keep doing your thing. It shows progress in the wings, asks a quick question when it needs one, and always waits for your OK before doing anything that leaves your Mac, like sending an email.
A few things I explored:
- Progress that stays out of the way, readable at a glance
- Questions as one tap, not a chat window
- Approval cards for anything with real consequences
- Paused and stuck states that tell you what to do next
- A small animated cat, because agents should have some personality


Approval cards for anything that leaves the Mac is the right line to draw. Does the card show the full email before you tap OK, or a short summary? I'd lean toward full text for anything going to another person.

Designed an AI research workspace where the agent plans the work and fills a sheet with cited sources as it goes.
Same screen, two modes. Which one would you work in all day? 👀

13 voted
72%
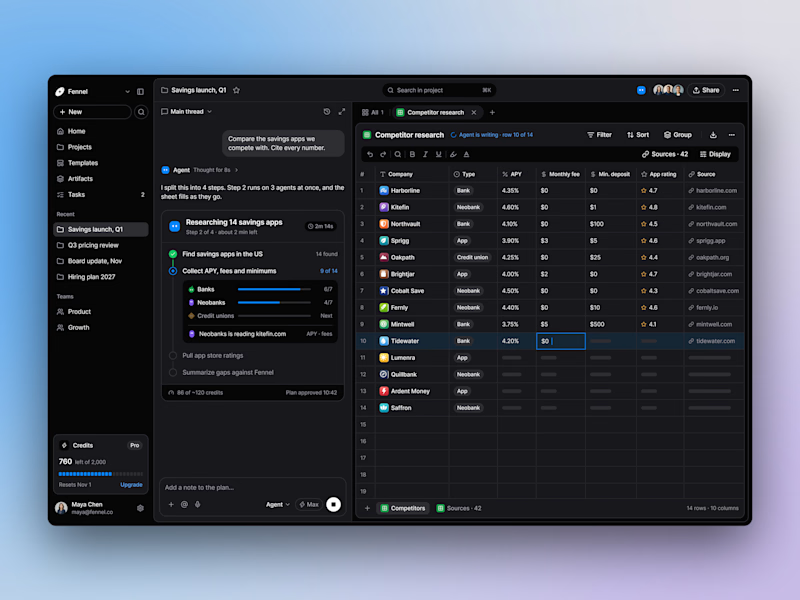
5 voted
28%
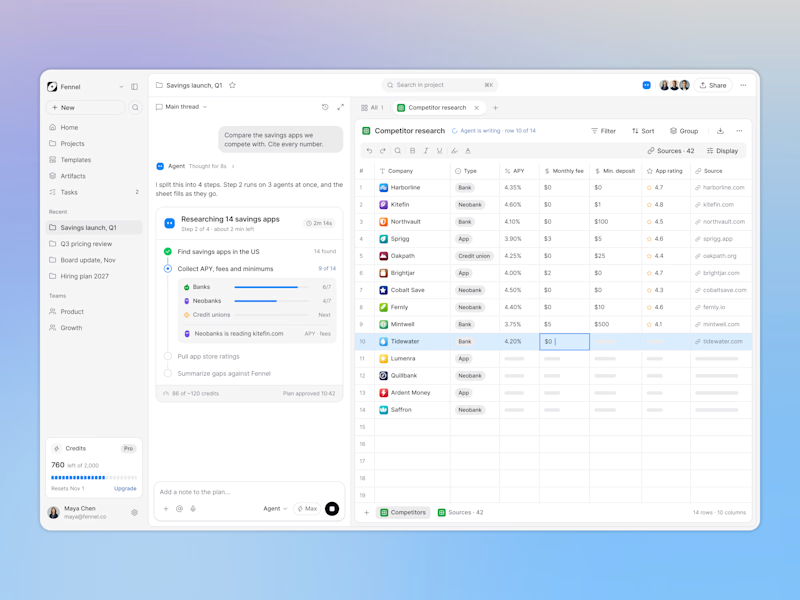
18 votes
Closed

Keeping the research plan and cited results side by side is a useful way to make the agent’s work easier to inspect. I’d lean toward light mode for reading the table in daylight. How do you distinguish a verified source from one that still needs review?