The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

RAG Study Buddy
Built a full-stack, AI-powered study assistant that allows users to upload PDF textbooks and documents, instantly transforming them into interactive learning environments.
The application leverages an advanced Retrieval-Augmented Generation (RAG) pipeline orchestrated with LangChain. Uploaded documents are parsed, chunked, and embedded into a Pinecone vector database. Upon querying, the system retrieves the most semantically relevant sections and passes them to OpenAI's API, ensuring that all answers are strictly grounded in the source text to drastically reduce hallucinations.
Beyond standard Q&A, the system automatically generates study flashcards and maps out document relationships using knowledge graph visualization.
Tech Stack: Python · FastAPI · Next.js · LangChain · Pinecone · OpenAI API
This project demonstrates my ability to build production-ready AI microservices, manage complex backend RAG logic (including semantic chunking and embedding strategies), and integrate them seamlessly with a modern web frontend.


The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started

Challenges
View all


Related posts

Cognis - AI-Powered Learning Platform
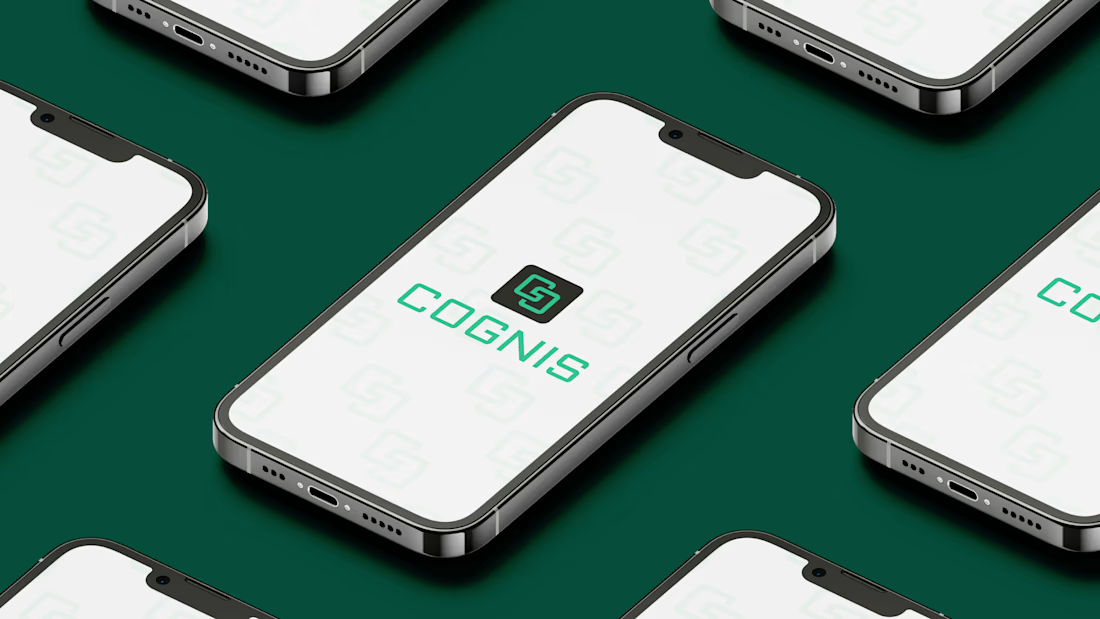
A visual identity designed for Cognis, an AI-powered platform that transforms notes into active learning experiences through AI preparation, quizzes, puzzles, and shared knowledge.
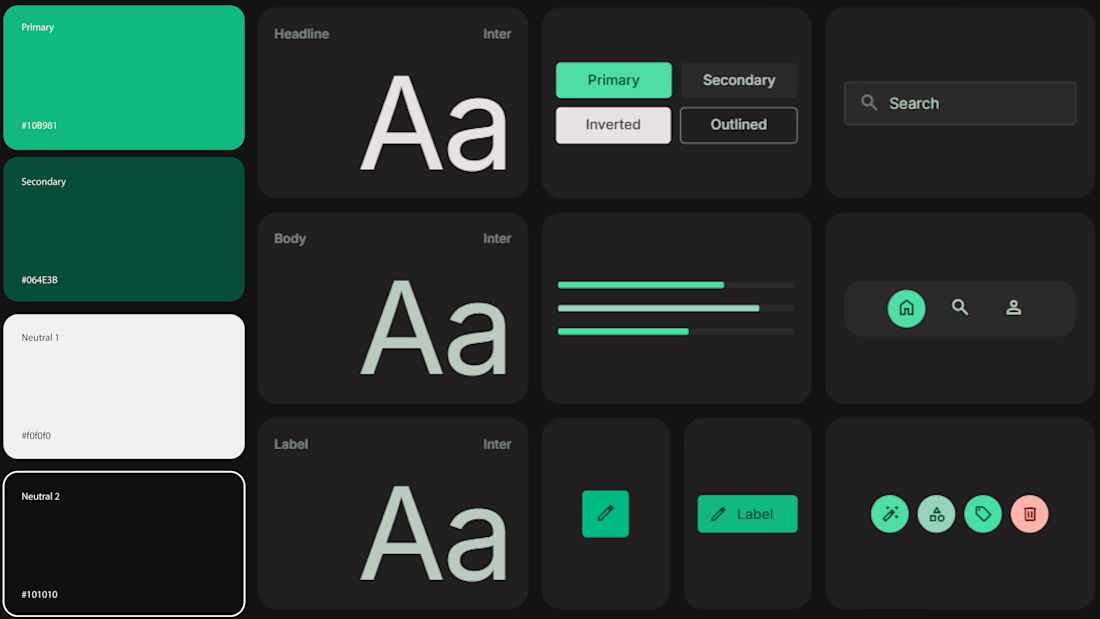
The identity is built around the idea of connected knowledge - expressed through an interlocking logo, flexible pattern system, focused colour palette, and digital product mockups.
Explore the full case study on Behance : https://www.behance.net/gallery/255797847/COGNIS-AI-POWERED-LEARNING-PLATFORM



Love how the interlocking mark carries through into the pattern, Varun.

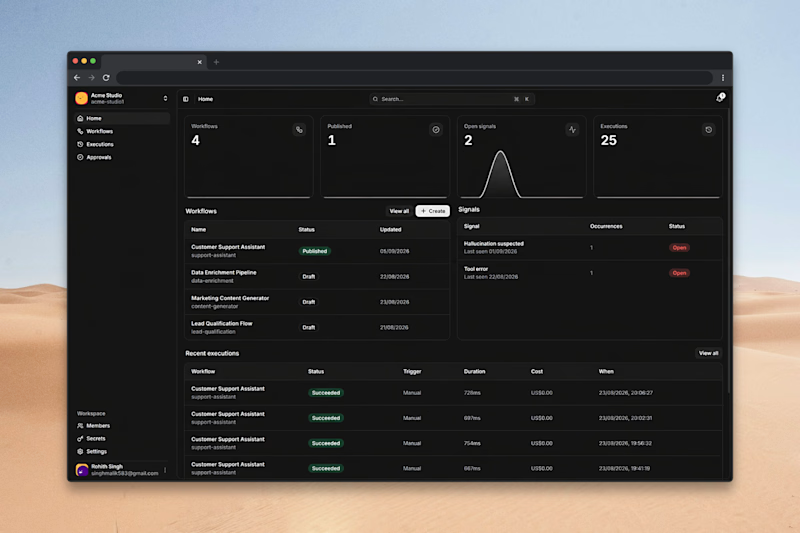
Redesigned Linea's home screen. The bit i care about most is the signals panel, the system watches every run and flags anything that looks wrong: "hallucination suspected", "tool error", last seen, how often. you catch it before a user does.
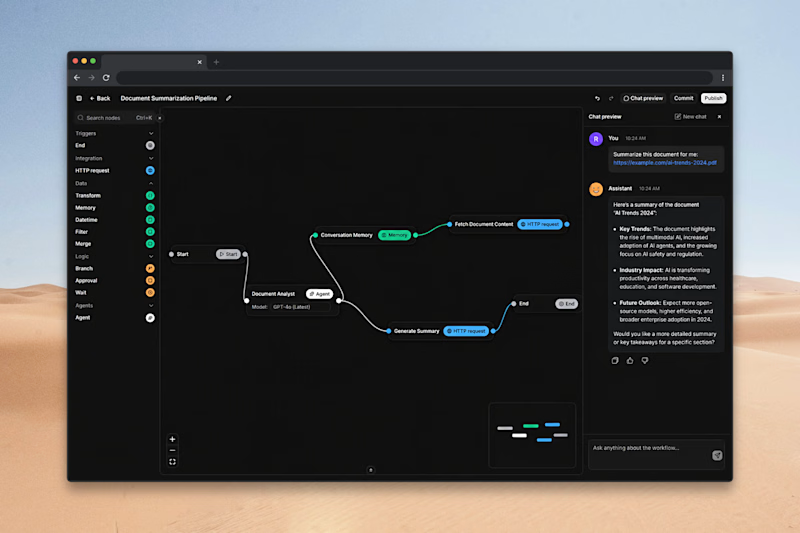
Each execution shows its cost. the support assistant's about a cent a run. Second shot is the canvas where the flows get built.
Is the home page enough at a glance, or would you pull executions higher?


0 voted
0%
1 voted
100%
1 vote
Closed


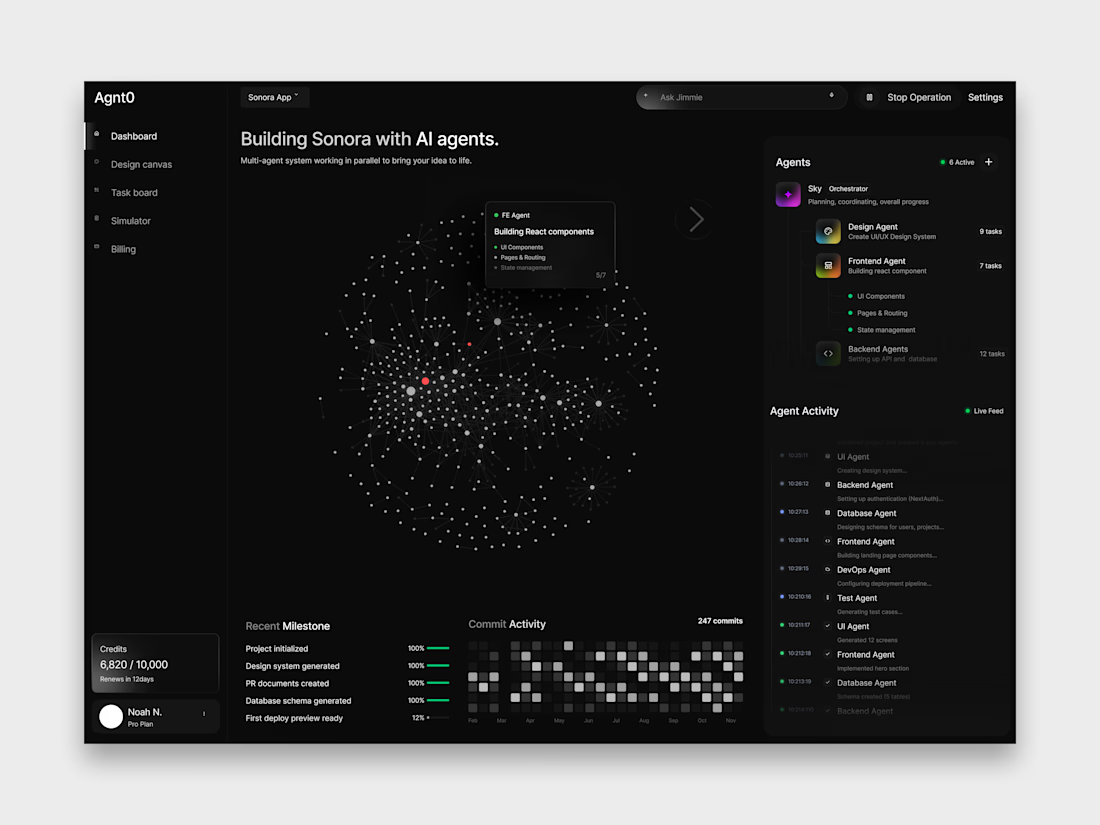


the dotted agent map looks so good