The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

It all started on a Sunday at the AWS User Group Mumbai meetup. I wasn't expecting to walk away with a new obsession, but then the speaker introduced me to Temporal and everything changed.
Temporal is a durable execution engine that solves one of the hardest problems in agentic AI what happens when your LLM workflow crashes mid-run? Normally you lose everything
So I went home and built this: an agent that monitors your competitors around the clock tracking pricing changes, product launches, hiring signals, and strategic moves. Every 24 hours it uses Mistral (running fully on-device via Ollama) to analyze the data and synthesize a structured executive briefing delivered straight to your inbox.
Sometimes the best projects start with a Sunday conversation.


The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started

Challenges
View all


Related posts

: Hi everyone!
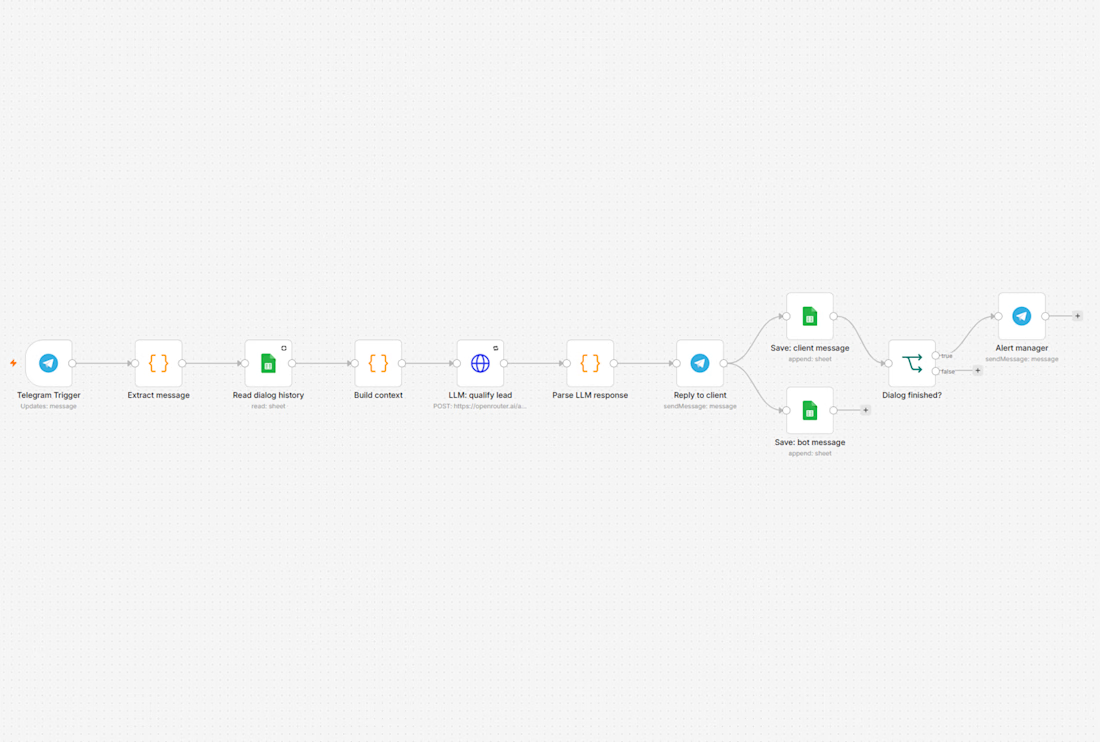
AI Lead Qualifier — chat agent that qualifies leads before your manager picks up the phone.
THE PROBLEM
78% of buyers choose the vendor who answers first. Most inbound leads wait hours for a human.
THE SOLUTION
An AI agent answering every lead within seconds, 24/7: short dialog → structured data (need, budget, timeline, contact) → A/B/C grade → instant Telegram alert with a full lead card. Everything logged to Google Sheets.
BUSINESS IMPACT
• Response in seconds, not hours
• 50–70% of routine questions off your sales team
• Structured lead card for every inquiry
• Self-hosted — no monthly SaaS fees
PROVEN IN A LIVE TEST
From "can you make a website for my store?" the agent extracted need, timeline, budget, name and phone in 2 messages, scored the lead class A, and alerted the manager — automatically.
Built on n8n + LLM + Telegram. Details in my profile — DM me.



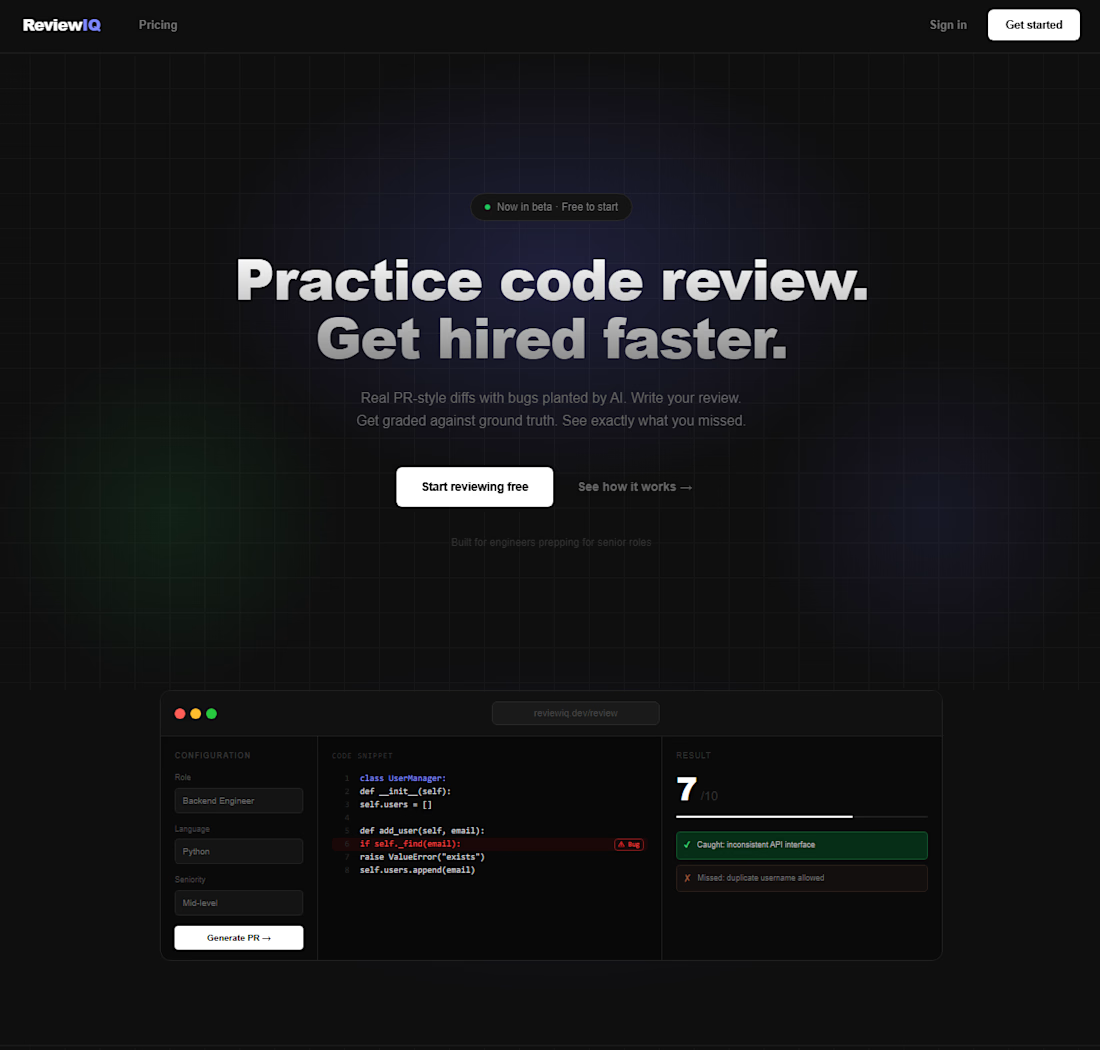
I built ReviewIQ because technical interviews don't always test whether you can actually review code.
ReviewIQ is an AI-powered code review interview trainer built for software engineers.
You pick a role, language, and seniority, then get a realistic PR diff with bugs intentionally planted in it.
You write your review.
Then the system grades it against the actual bugs, shows what you caught, what you missed, and gives you feedback on how a stronger reviewer would approach it.
The interesting part was building the grading system so it isn't just "AI thinks your answer is good." The bugs have a known ground truth, so the review can be evaluated against something concrete.
Built with Next.js, Supabase, PostgreSQL, OpenAI, and Lemon Squeezy.
I'm interested in building more products where AI isn't just a chat box, but an actual part of the product experience.

The known-ground-truth approach is a great product decision—it makes the feedback feel earned rather than like an opaque AI verdict. I also like that the flow tests the actual review skill instead of rewarding pattern-matching in interviews.

OneVerse AI OS is coming ...under development, will change the original world