The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

I test AI agents for the failures that demos hide.
Over the past few months I've built Sentinel, a benchmark that puts MCP security guards through 6 classes of attacks in a sandbox, and I evaluate frontier coding agents on real bugs every week.
The biggest thing I've learned: an agent that looks great in a demo can still take unsafe actions, make up an answer, or quietly misread an ambiguous instruction once it meets real users.
If you're shipping an AI feature and want someone to break it before your users do, send me a message. I'll point out 3 issues I'd test first, free.
The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started


Related posts

🤖 AI can write code, but can we trust AI agents to run things on their own?
We're seeing more developers build AI agents that can use tools, manage workflows, interact with APIs, and perform tasks automatically.
💡 I've built AgentLock app, this app can be used to build a reliability and guardrails layer for AI agents.
The goal is to help agents:
- Prevent duplicate actions.
- Verify that tool calls actually succeed.
- Request human approval for risky operations.
- Keep track of every agent activity.
Contra community, especially AI developers: What would you add to this kind of tool? What problems are you facing when building AI agents?
I'd love to hear your thoughts and opinions! 👇


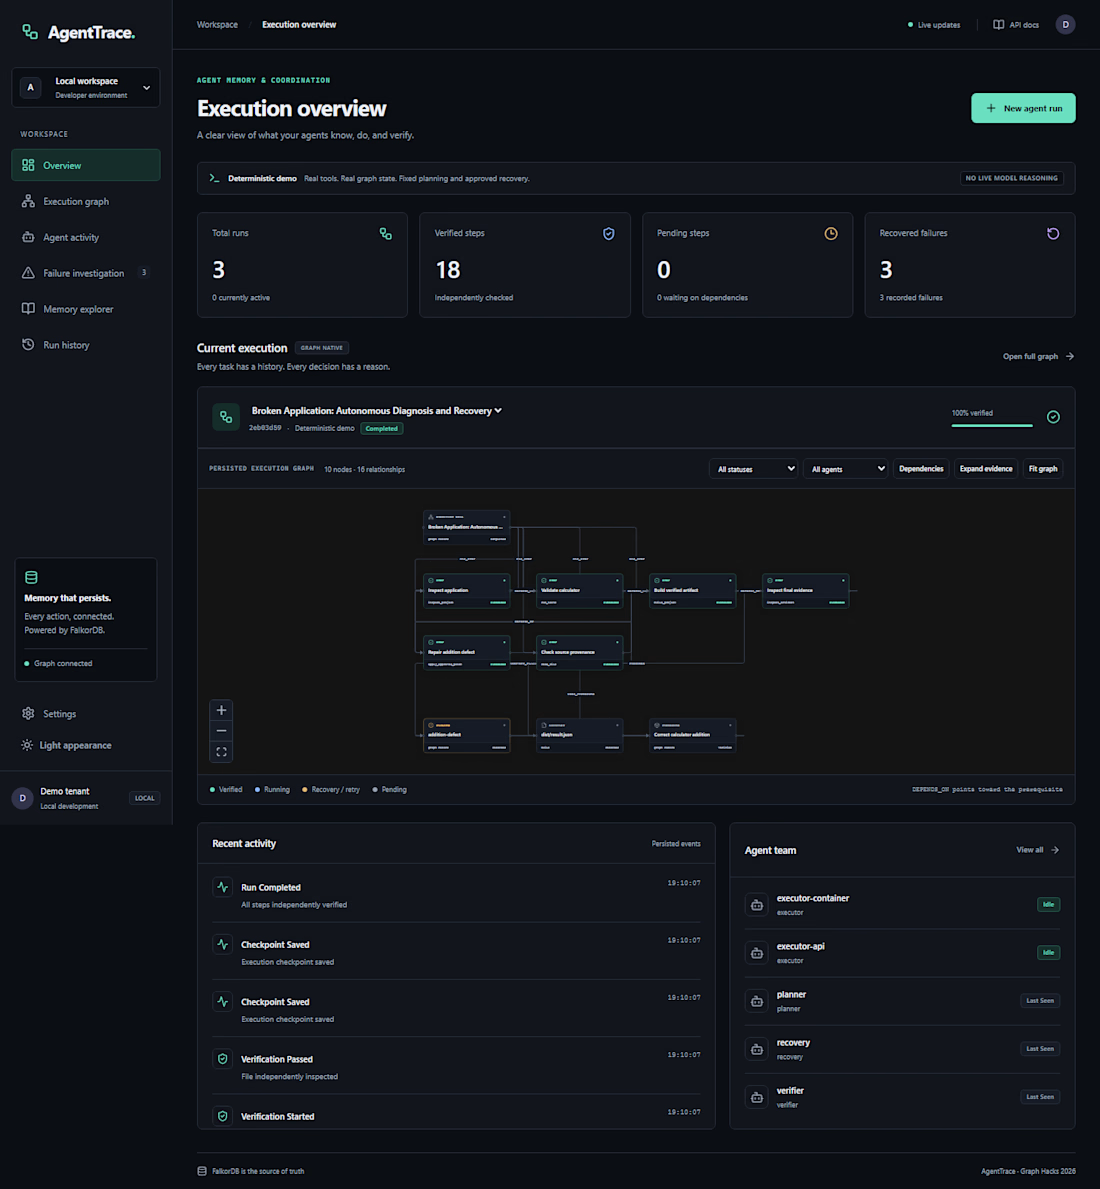
An AI agent fails halfway through a job. What should it remember when it tries again?
That question led me to build AgentTrace, a Python and FalkorDB project for keeping track of agent runs. It records task progress and decisions in a graph so you can inspect what happened and see where a run stopped. That’s especially useful when several agents share a workflow.
When you debug an agent run, what do you look for first: the failed step, the input that caused it, or the decision that sent it down that path?


The Forum: where the few who know are talking. Part of a short film series on how a company's knowledge turns into agents that actually work. Feedback from fellow builders welcome.