The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost
If your RAG system is hallucinating, don't blame the LLM. Blame your retrieval pipeline. 🔍
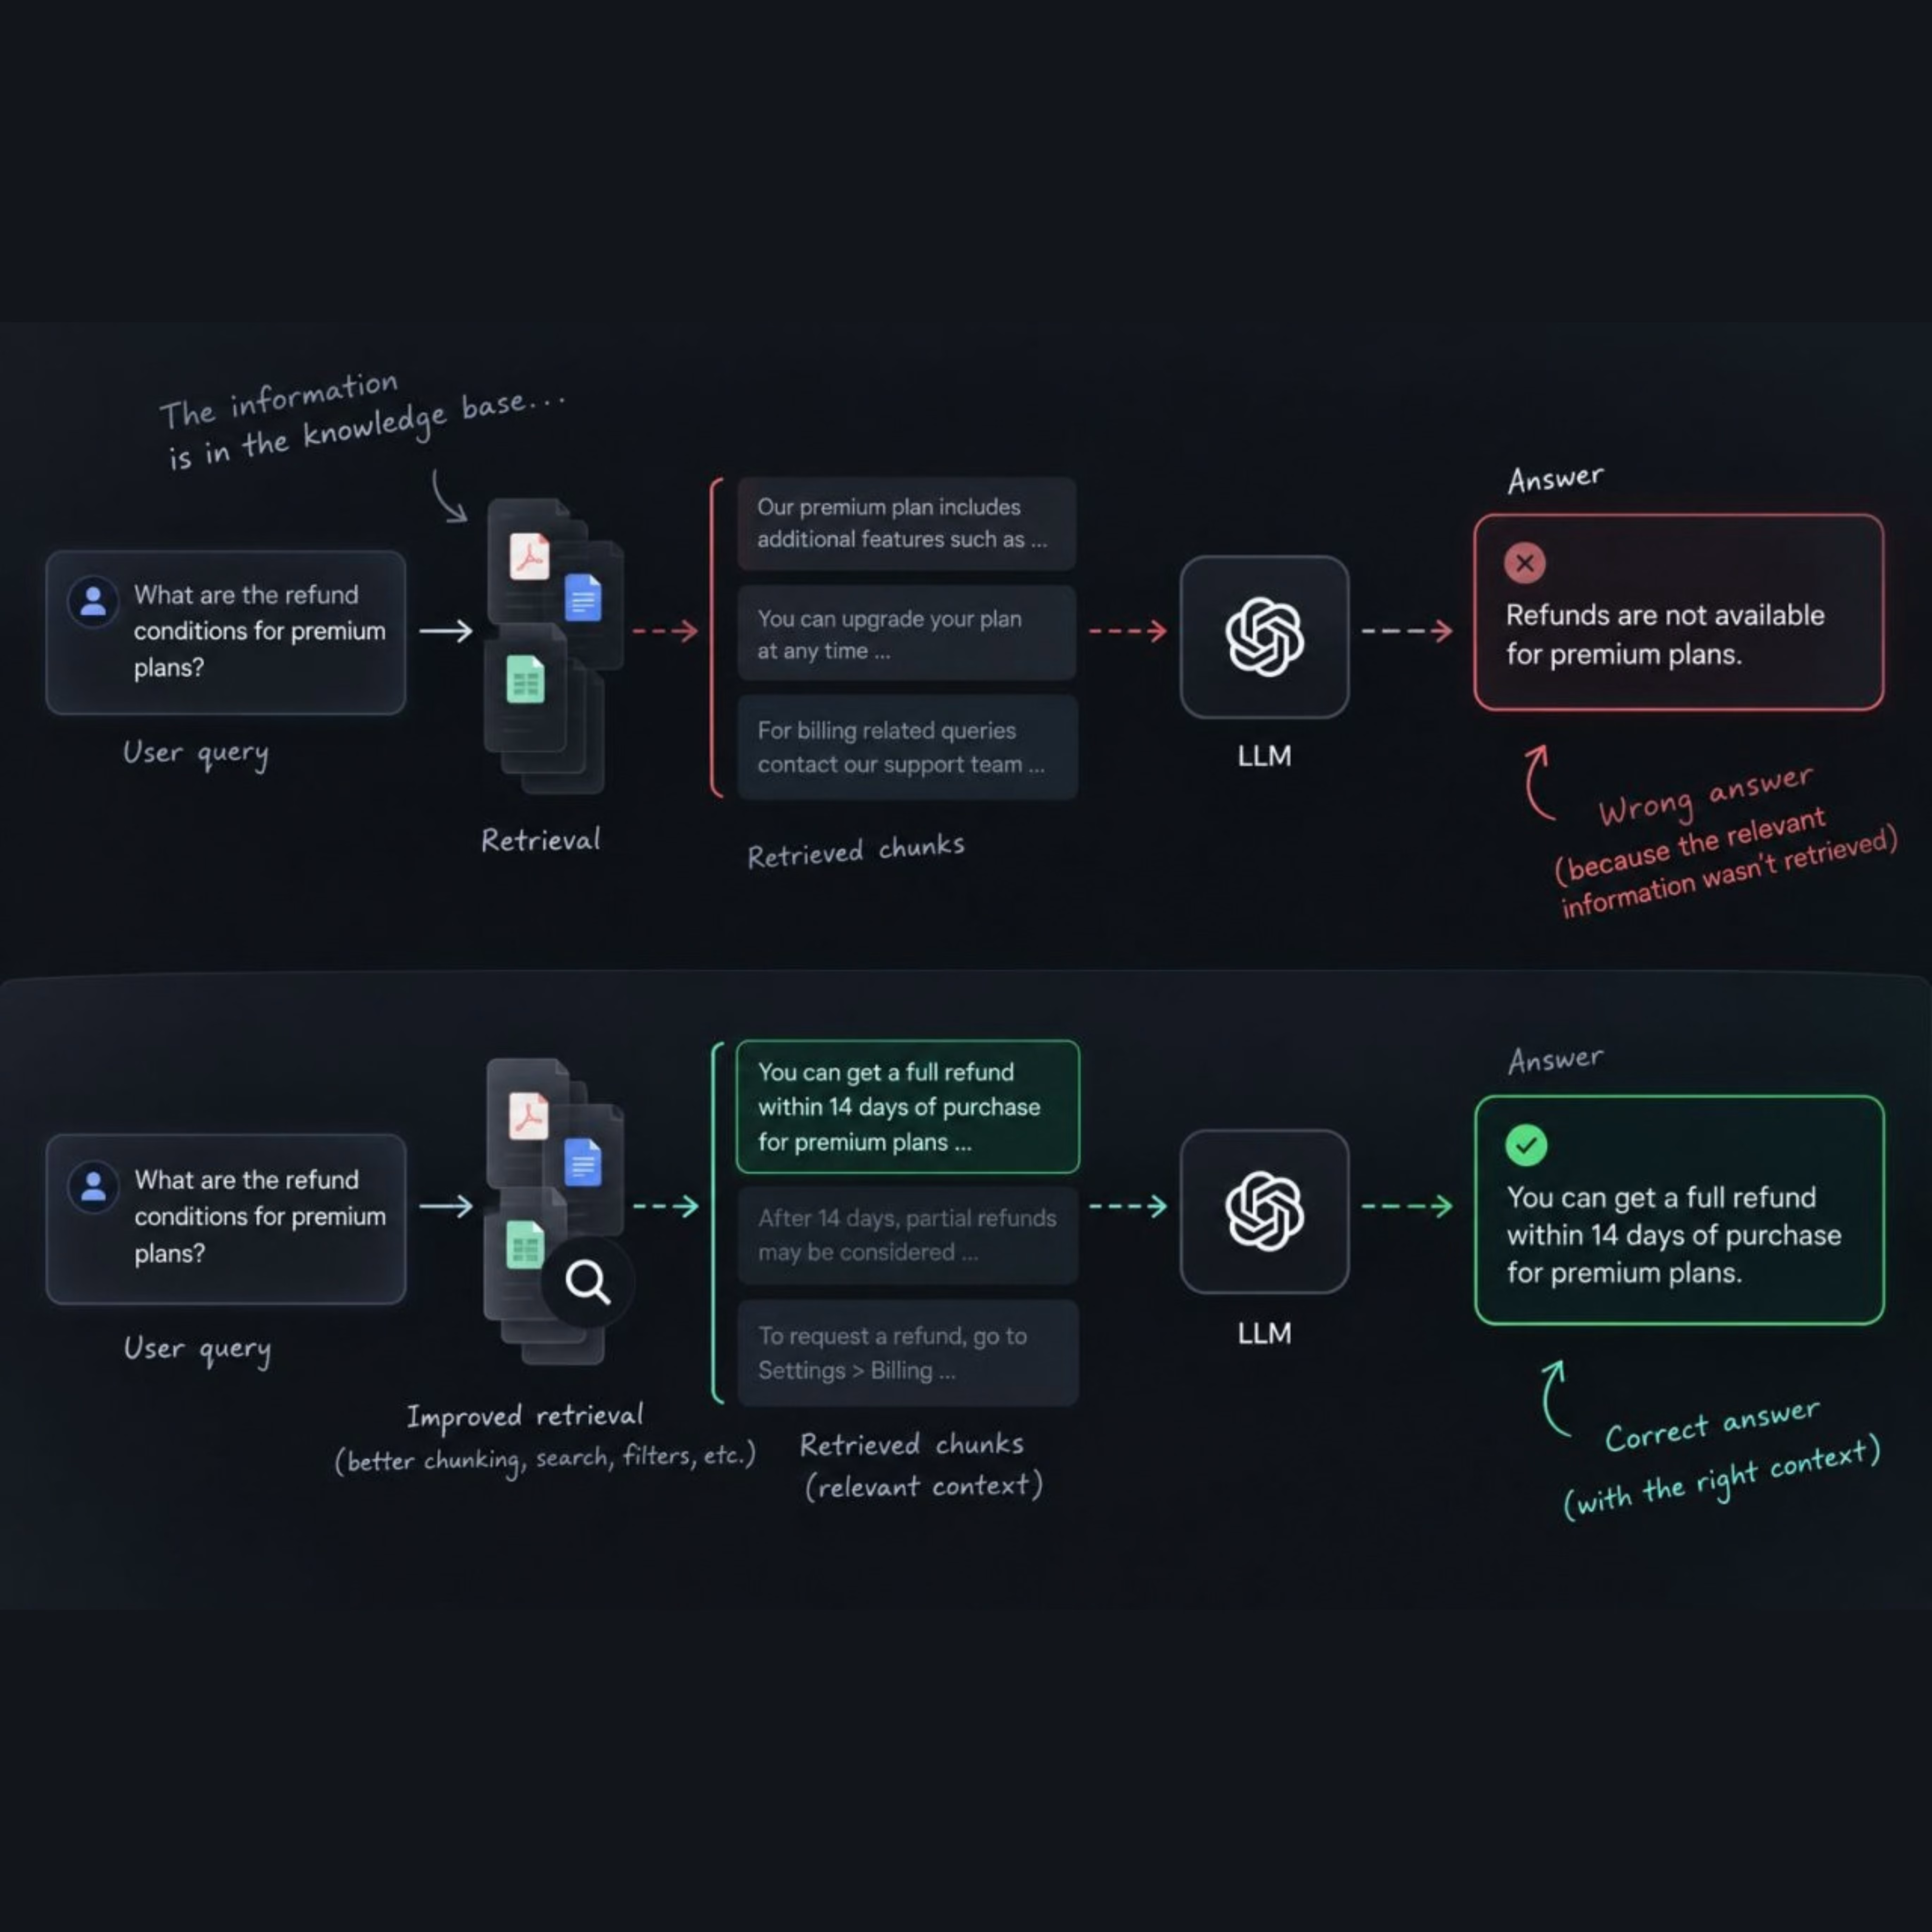
This visual perfectly captures the most common point of failure in Retrieval-Augmented Generation (RAG) applications. The frustrating part? The correct information already exists in your knowledge base, but the system still fails. Why?
❌ The Baseline Failure (Top):
When a user asks a specific question (like refund conditions), a naive retrieval system often pulls chunks that are semantically related to the keywords but lack the actual answer. The LLM is starved of the right context and forced to guess, resulting in a confident—but entirely wrong—hallucination.
✅ The Production Fix (Bottom):
The fix isn't swapping to a more expensive LLM; it's building a smarter search architecture. By implementing improved retrieval—which includes intelligent chunking strategies, metadata filtering, hybrid search, and reranking—we ensure the LLM receives the exact, highly relevant context it needs to synthesize the correct answer.
When building enterprise AI agents, like automated helpdesk routers, optimizing this retrieval step is where 80% of the engineering effort actually goes. Garbage context in, garbage generation out.
What is the number one change you've made to your RAG pipeline to improve retrieval accuracy? Let's discuss below! 👇
The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started





Related posts

Completed "Building and Evaluating Advanced RAG" by DeepLearning.AI (TruEra, LlamaIndex).
The most useful part wasn't building another RAG pipeline, it was learning how to actually evaluate one. The RAG Triad (answer relevance, context relevance, groundedness) gives you a way to catch exactly where a system is failing: bad retrieval vs. the model making things up vs. just answering the wrong question.
Also went through sentence-window and auto-merging retrieval, two ways to fix the classic RAG trade-off between precise matching and having enough context to actually answer well.
Applying this directly to a RAG tool I'm building for equity research. Evaluation is the part of RAG most people skip, and it's exactly where things quietly break in production.
https://www.deeplearning.ai/accomplishments/491d7a76-f89d-4e13-9d6b-3377fced78a2?accomplishmentId=491d7a76-f89d-4e13-9d6b-3377fced78a2&usp=sharing

evaluating RAG is the part nobody talks about, the triad is super handy

Why Reranking Matters in RAG: Fast Retrieval ≠ Precise Relevance 🎯
If you are building Retrieval-Augmented Generation (RAG) applications, you've probably realized that just pulling the top-K results from a vector database isn't always enough to get a great answer.
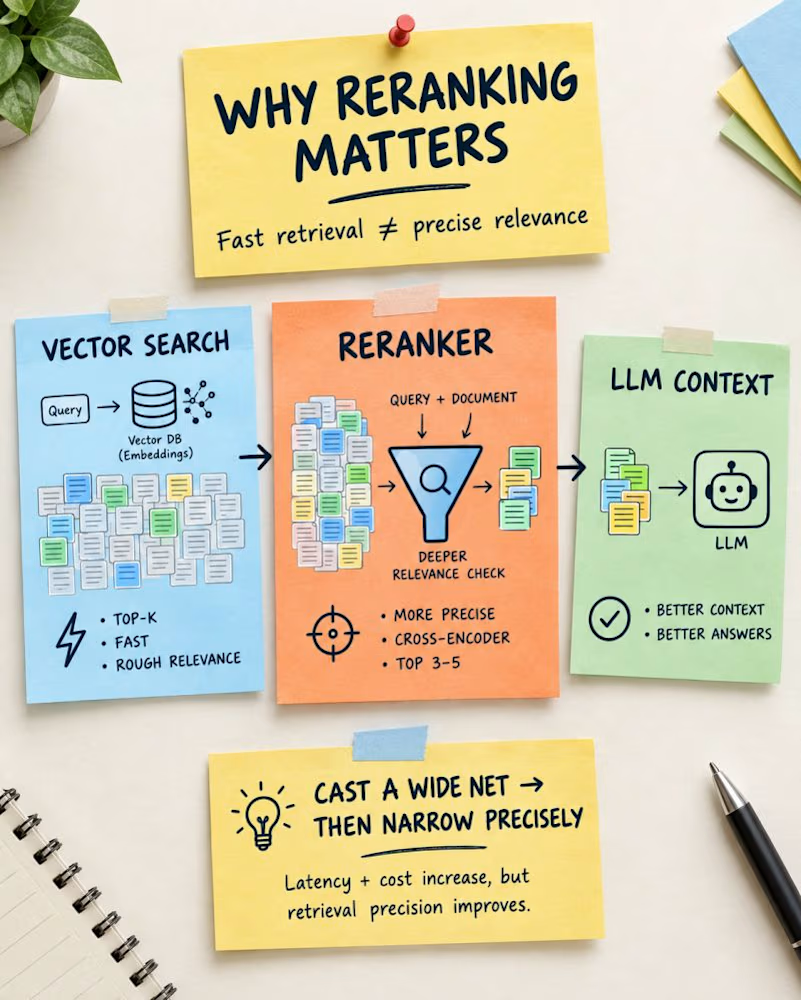
This visual perfectly explains why a two-stage retrieval pipeline is critical for production AI systems: Cast a wide net, then narrow precisely.
Here is the breakdown of why adding a reranker makes all the difference:
⚡ Stage 1: Vector Search (The Wide Net)
Your Vector DB is optimized for speed. It uses bi-encoders to rapidly scan millions of embeddings and return the top-K results. It's incredibly fast, but the results only offer "rough relevance."
🔍 Stage 2: The Reranker (The Precision Funnel)
This is where the magic happens. A reranker (typically a cross-encoder) takes both the user's query and the retrieved documents and performs a much deeper relevance check. It scores and re-orders the chunks, narrowing that wide net down to the absolute best top 3-5 results.
✅ The LLM Context (The Payoff)
Garbage in, garbage out. By passing only the most highly precise, reranked documents into the LLM's context window, you get significantly better, more accurate answers.
The Trade-off:
Yes, adding a cross-encoder introduces a slight bump in latency and cost. But the massive improvement in retrieval precision and reduction in hallucinations makes it entirely worth it for enterprise-grade applications.
Are you currently using rerankers (like Cohere, BGE, or cross-encoders) in your RAG pipelines, or relying solely on vector search? Let's discuss below! 👇

One number is a poor release gate for document AI. An invoice extractor can score well overall and still miss the tax value that sends a bad record downstream. At Procys, I work on a pipeline that pairs OCR and LLM reasoning with deterministic checks on headers, line items and tax. I look at failures by field and keep uncertain values tied to their source so a reviewer can resolve them. Case: https://kapilchauhan.netlify.app/case/procys.html
kapilchauhan.netlify.app
Procys: Document intelligence | Kapil Chauhan
Production LLM agents for document processing and identity verification