The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

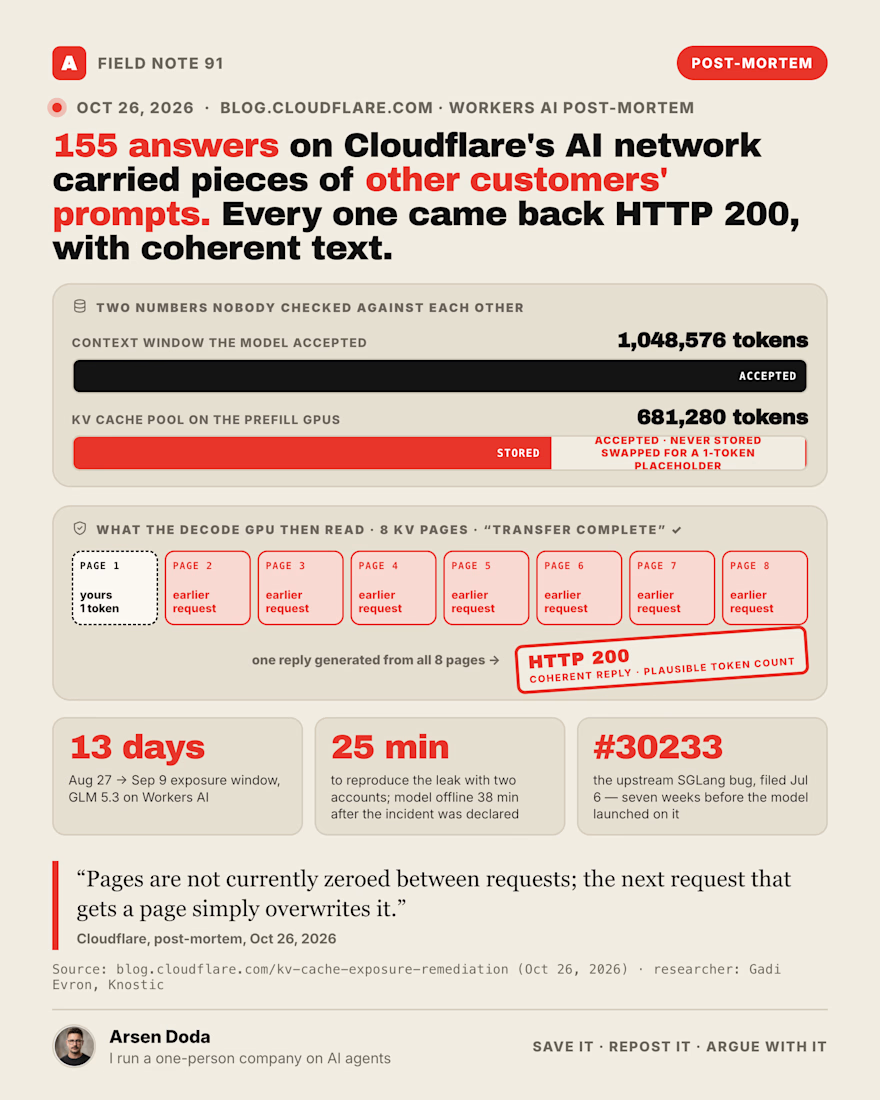
155 responses.
For 13 days, an AI model on Cloudflare's network answered long prompts with pieces of other customers' prompts.
Every one came back HTTP 200, with coherent text.
Cloudflare published the post-mortem last night. The bug is ordinary. That is the point.
What happened, in Cloudflare's own words:
→ The model (GLM 5.3 on Workers AI) accepted a context window of 1,048,576 tokens. The GPU memory holding a prompt in flight, the KV cache, "only had room for 681,280 tokens."
→ A prompt longer than the pool should have been rejected. Instead the inference engine (SGLang, prefill and decode on separate GPUs) marked it rejected, swapped it for a one-token placeholder, and still sent "transfer complete."
→ The decode GPU "assumed that prefill overwrote the KV cache." It had not. So the model answered from whatever earlier requests had left in those memory pages. Other people's prompts and half-written replies.
→ "Pages are not currently zeroed between requests; the next request that gets a page simply overwrites it."
→ Window: Aug 27 to Sep 9. A researcher (Gadi Evron, Knostic) reported it via HackerOne. Cloudflare reproduced it in 25 minutes and had the model offline 38 minutes after declaring the incident. No evidence anyone exploited it on purpose.
The line that should worry anyone who buys AI by the token:
"we only validated HTTP response codes and engine performance at long contexts."
The happy path was tested. The reject path returned 200.
And the upstream bug had been filed as SGLang issue #30233 on July 6, seven weeks before the model launched on it.
I run a one-person company on AI agents. My agents push long documents through hosted models most days. What I take from it:
Your prompt does not end when your request does. It sits in someone's GPU memory until the next tenant overwrites it. Shared inference means shared paper.
Three rules I am applying this week:
Rule 1: Test the failure path, not the demo path. Send a prompt that is too long on purpose and read what comes back. A 400 is a pass. A 200 is the finding.
Rule 2: Two numbers that must agree get a check that runs before deploy. Context window vs cache pool. Cloudflare's line: "Nothing forces the two to agree, and it is our job to check that they do."
Rule 3: Sort your prompts by what would hurt if they came back in someone else's reply. Those go to isolated capacity or hardware you own. The rest can share.
Credit where due: reproduce in 25 minutes, pull the model in 38, fix upstream, publish every timestamp. That is a vendor I keep paying.
Nobody broke in.
The memory was never cleaned.
Have you ever sent your API a prompt that is too long on purpose? Yes or no, one word. 👇
The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Related posts

Landing page design for Lumo — banking for freelance life
Banks sell control — dashboards, charts, a card floating at fifteen degrees. Freelancers don't want control over their money. They want to stop thinking about it in the gap between sending an invoice and the money landing.
That gap is what the page is built on. The product sits in a meadow instead of on a dark grid, because the promise isn't "manage your finances better" — it's "we handle the part that keeps you up." And the strongest line on the page isn't a feature: no waiting for Monday. Freelancers don't lose weekends to fees. They lose them to timing.
The proof follows the same rule. One freelancer, one number — 4% lost on every international payment. A percentage someone can check against their own account beats any adjective.


great visuals 🙌

Cancelling a purchase and failing a purchase reach your Flutter code the same way, as a PlatformException. That is how a paywall ends up showing a red error to someone who simply changed their mind on the store sheet.
PurchasesErrorHelper.getErrorCode is what distinguishes them, and two outcomes are not enough. A single call to Purchases.purchase can end five ways: cancelled, pending, completed, failed and unresolved. Pending is the one that catches people out. A parent still has to approve the purchase, or a slow payment method has to settle, and RevenueCat grants no entitlement until the store confirms it.
Which means the paywall screen should not be what decides access. A pending purchase can complete after the paywall closes or after the app has been killed, and RevenueCat does not push that change to the device. Keep a CustomerInfo listener in an object that lives as long as the app, and have every paid feature read the entitlement from it rather than from whatever the purchase call returned.
https://www.duskolicanin.com/blog/flutter-subscription-pending-cancelled-purchase

duskolicanin.com
Handle Pending and Cancelled Flutter Purchases
Handle RevenueCat cancelled and pending purchases in Flutter: map error codes to paywall states and unlock only from an active entitlement listener.

This is such a real pain point! So many paywalls break exactly here - treating a user cancellation as a crash. Thanks for pointing out PurchasesErrorHelper.getErrorCode to distinguish it. Handling cancelled vs pending correctly is crucial for UX, no one wants a red error for changing their mind. Saving this!

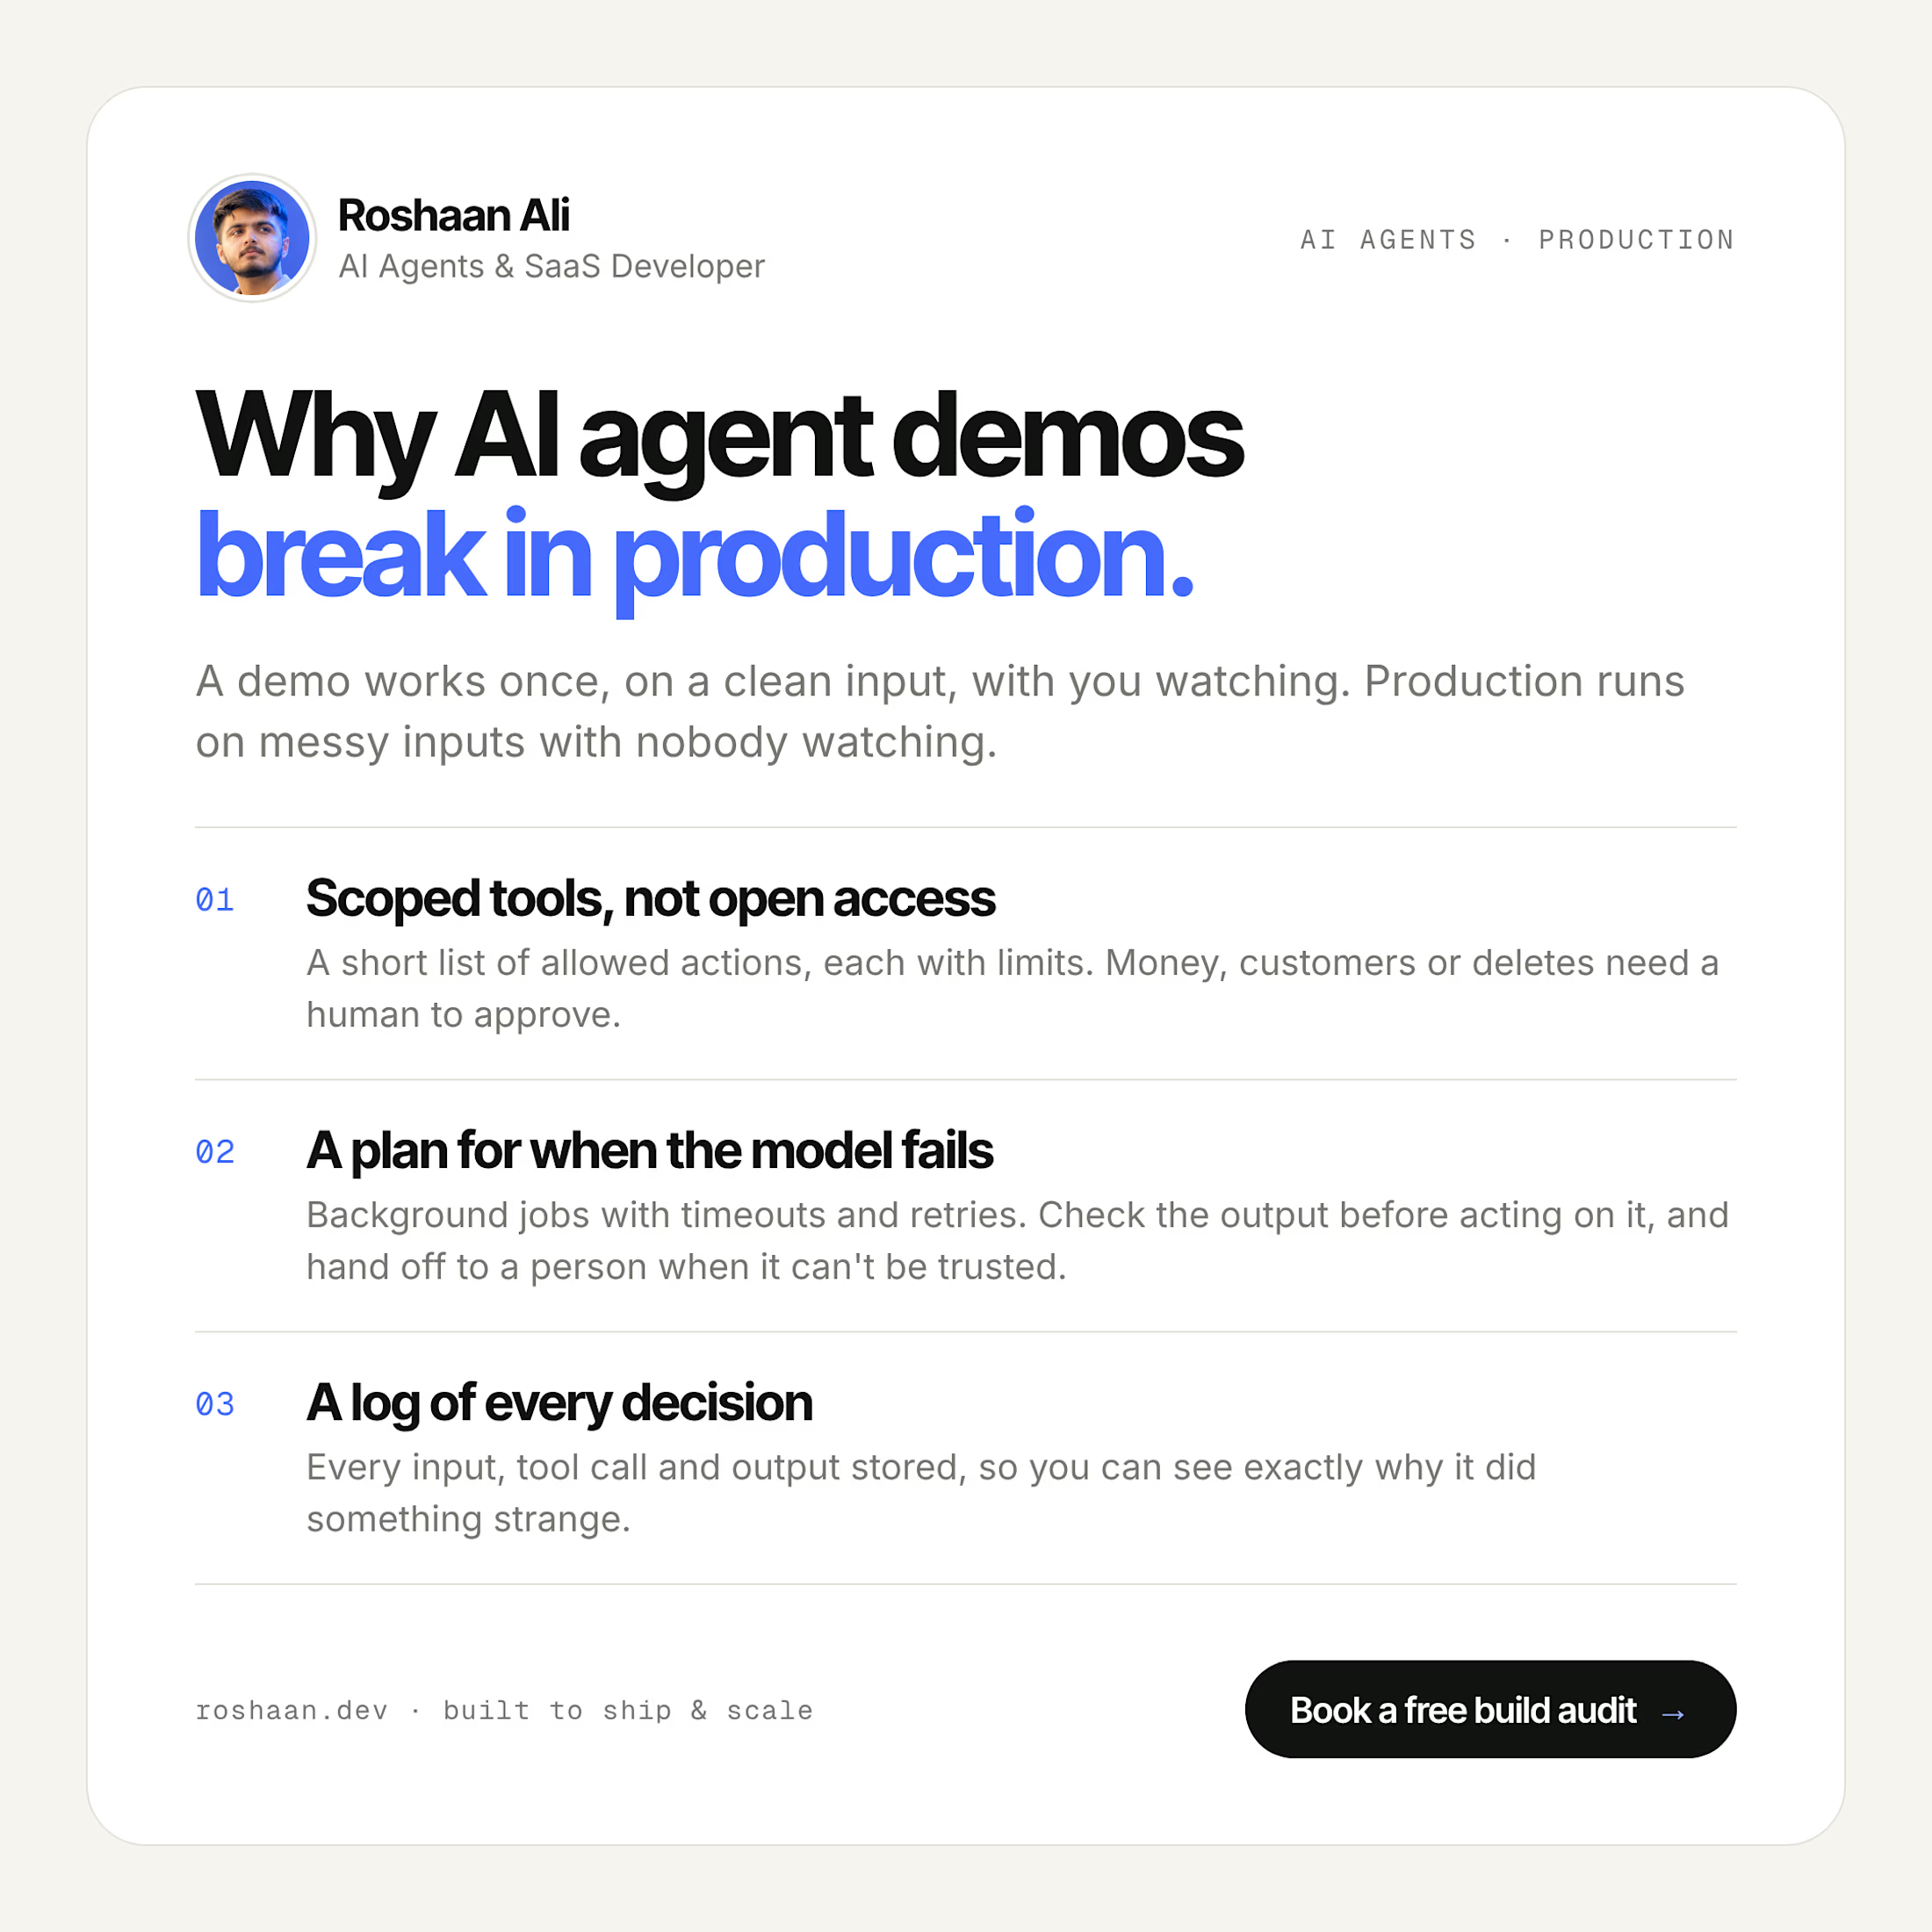
Why AI Agent Demos Break in Production
An AI agent demo only has to work once, on a clean input, with you watching. In production it runs again and again on messy real inputs, and nobody's watching.
I've built AI into real products, from a repricing engine that runs 24/7 for a US Amazon seller to a voice automation platform for a company in Germany. These are the three things I put in place before any agent goes live:
1. Scoped tools, not open access
Give the agent a short list of actions it's allowed to take, each with its own limits, instead of raw access to your database or APIs. Anything that touches money, customers or deleting data needs a human to approve it.
2. A plan for when the model fails
Model calls are slow, they time out, and sometimes they return something that makes no sense. Run agent work in background jobs with timeouts and retries, check the output before acting on it, and hand the task to a person when it still can't be trusted.
3. A log of every decision
Store every input, tool call and output. When the agent does something strange (and at some point it will), you can see exactly why and fix it instead of guessing.
None of this shows up in a demo. All of it decides whether the agent is still running a month later.
Planning an AI agent for your product? I offer a free build audit: calendly.com/roshaanali-business

"Works once with you watching" is the best way I've heard it put. Timeouts and a human fallback are the parts most demos skip.