The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

Most messy spreadsheets aren't messy in one obvious way. They're usually a stack of small problems: dates stored as text, repeated names with different spacing, blank cells that mean different things, and categories that drift over time.
That matters because a clean-looking total can still be built on inconsistent rows.
My rule is simple: normalize what can be verified, flag what can't, and leave a change log so the owner knows exactly what moved. No invented values and no mystery edits.
I now offer that as a fixed, two-day cleanup for one spreadsheet or CSV. If a file is slowing down a report, handoff, or decision, send me the rough row and column count and the part that keeps breaking. I'll tell you plainly whether it fits the scope.

contra.com
Clean and normalize a messy spreadsheet or CSV by Teagan Doherty
Read more about Clean and normalize a messy spreadsheet or CSV by Teagan Doherty on Contra.
The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started





Related posts

Sample project: a bills register and dashboard I built in Excel for a fictional business (Cedar & Stone Studio).
Change one date and everything updates: the status colours, days overdue and overdue balances.
Optional extras:
•A dashboard with status table and percentages in a pie/doughnut chart
• Amounts table and bar chart.
Which would you rather see in a monthly report: the status percentages, or the money totals? I'd love your thoughts.

Hi, I'm Fletch. 👋
I fix messy HubSpot portals and build the automations that keep them clean.
My path here wasn't a straight line: preschool teacher, then BDR, then leading a BD team, then enablement, and now RevOps. Every one of those jobs taught me the same thing. A system only works when the people using it understand it.
That's how I approach HubSpot work. Before I build anything, I want to know how your team actually sells, where the data stops being trustworthy, and who gets stuck when something breaks.
A few recent results:
• A 2-week portal audit that surfaced 296 unused properties and a prioritized fix list
• A lifecycle-stage bug found and fixed, correcting 128 contact records
• Location values cleaned up from 600+ variations down to 0
What I help with:
HubSpot cleanup: dedupe, property rebuilds, data hygiene
HubSpot automation: workflows, routing, sequences, pipelines
Fractional RevOps and enablement, when you need more than a cleanup
I'll be sharing what I see inside real portals here: the patterns, the fixes, and the occasional workflow nobody remembers building.
If your CRM has gotten away from you, send me a note about what's broken. I'll tell you where I'd start.

Best of luck :)

Most Claude Code sessions go wrong in the first message.
Not because the model is weak, but because the starting prompt is vague: “fix this bug” or “add tests.” With nothing else to go on, the model starts editing before it has looked at the repository, and you spend the next ten minutes steering it back.
What changes the outcome is the order of the work. Inspect the repo first. Learn the existing conventions. Plan before editing. Make focused changes, add or update tests, run real commands to verify, then summarize what changed. A prompt that builds that sequence in means you don’t have to remember to ask for it every time.
I put together a set of 2,000 prompts around that workflow, covering areas like debugging, testing, security, architecture, APIs, and cloud. They come as JSON, CSV, and JSONL, so you can browse them, filter them, or feed them into your own scripts.
If you’d rather not start every session from a blank screen, it’s here: https://contra.com/products/5w55SuJ3-claude-code-prompt-vault-2000

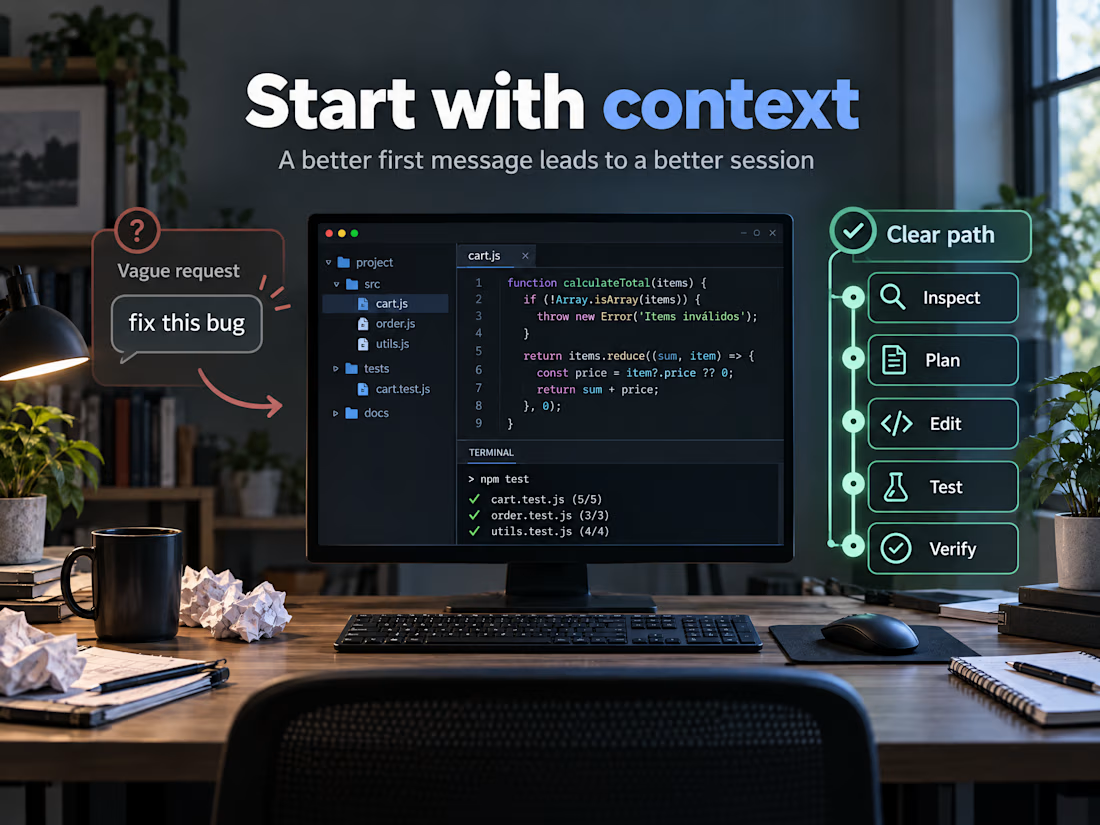

Plan before editing is the step I see skipped most. When I build with Claude, asking it to restate the repo's conventions back to me before any change catches most wrong assumptions early.